P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDAA-C01ダンプ:https://drive.google.com/open?id=1XjF9sIm-7F-Rg18mfUNltUwF_EYQVG_t
私たちに知られているように、当社は、すべての受験者向けのDAA-C01試験資料を編集するために設立された専門ブランドです。当社のDAA-C01ガイドファイルは、この分野の当社の多くの専門家や教授によって設計されています。当社のDAA-C01認定準備資料は、教材資料市場で絶対的な権限を持っていると約束できます。弊社が設計した教材はあなたに最適な選択になると信じています。試験の準備をするときは、当社のDAA-C01ガイドファイルに完全に依存できます。
| Section | Weight | Objectives |
|---|---|---|
| Data Presentation and Data Visualization | 28%-29% | - Integrate with BI tools
|
| Data Transformation and Data Modeling | 22%-30% | - Design data models
|
| Data Ingestion and Data Preparation | 15%-20% | - Perform data discovery to identify what is needed from available datasets
|
| Data Analysis | 30%-32% | - Perform advanced analytics using SQL
|
DAA-C01実践ガイドまたはシステムの内容が更新された場合、更新された情報を電子メールアドレスに送信します。もちろん、製品の更新状況については、当社の電子メールをご覧ください。 DAA-C01模擬試験を使用してDAA-C01試験に合格するように協力できることを願っています。コンテンツの更新に加えて、DAA-C01トレーニング資料のシステムも更新されます。ご意見がありましたら、私たちの共通の目標は、ユーザーが満足する製品を作成することであると言えます。学習を開始した後、メールをチェックするための固定時間を設定できることを願っています。
質問 # 27
You are building a Snowsight dashboard that visualizes website traffic data'. The data includes a column 'visit_timestamp' (TIMESTAMP NTZ) and you need to display the number of unique visitors per hour for the last 24 hours. You also want to allow users to filter the data by country. You plan to use a chart to visualize the trend. Which of the following approaches are the MOST efficient and accurate for achieving this?
正解:C、E
解説:
Option A is a good approach because 'DATE _ TRUNC is efficient for truncating timestamps, and applying the filter directly in the SQL query can optimize data retrieval. Option D is also very efficient, as it pre-aggregates the data, which improves dashboard performance. Option B is less efficient because the 'HOUR' function only returns the hour value without the date, making it harder to filter for last 24 hours. Also, dashboard-level filters can sometimes be less performant than SQL-level filters for large datasets. Option C introduces a calculated field, which is generally less efficient than performing the transformation directly in SQL. Option E is technically correct, it only applies to TEXT stored visit timestamp. Thus, pre-aggregation and 'DATE_TRUNC' are superior.
質問 # 28
A Data Analyst needs to generate a graphic that will identify any natural clusters in a data set containing details about completed orders. Which Snowsight chart should be used?
正解:D
解説:
In the realm of Data Presentation and Data Visualization, selecting the appropriate chart type is critical for revealing the underlying structure of data. When an analyst is tasked with identifying "natural clusters," they are looking for groups of data points that share similar characteristics across two or more dimensions.
A Scatter Plot is the primary visualization tool for this purpose. By plotting two numeric variables (e.g., ORDER_AMOUNT on the X-axis and CUSTOMER_LOYALTY_SCORE on the Y-axis), the scatter plot allows the human eye to immediately detect density. If the data points form distinct "clouds" or groupings, these represent the clusters the analyst is searching for. In Snowsight, scatter plots are highly effective for exploratory data analysis, as they allow analysts to visualize the relationship between variables and spot outliers that may skew statistical summaries.
Evaluating the Options:
* Option A is incorrect because Line Charts are designed to show trends over time (sequential data).
They connect points in a specific order, which would obscure clustering logic by forcing a temporal connection between unrelated data points.
* Option B is incorrect because a Heat Grid (or Heatmap) is best used for comparing categories across two dimensions using color intensity. While it can show high-density areas, it aggregates data into
"bins" or cells, which can mask the fine-grained distribution required to see natural, point-based clusters.
* Option C is incorrect because Bar Charts are used for comparing discrete categories or showing distributions within a single dimension. They do not effectively show the correlation between two continuous variables needed for cluster identification.
* Option D is the 100% correct answer. The Scatter Plot is the standard analytical graphic for cluster detection and correlation analysis within the Snowflake Snowsight interface, providing the necessary granularity to see how individual orders or customers group together in a multi-dimensional space.
質問 # 29
A Data Analyst created two functions and one procedures:
The Analyst then runs this query: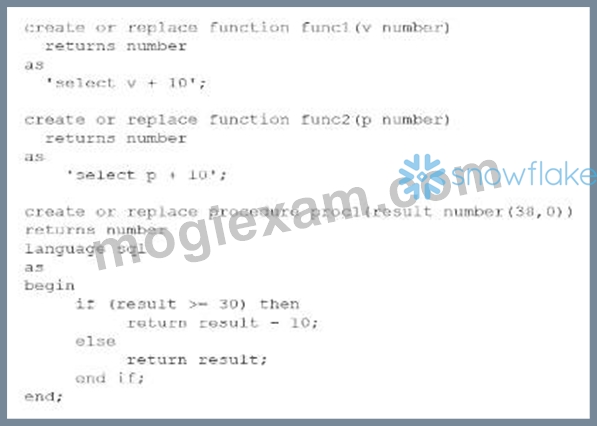
The Analyst then runs this query: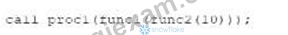
What will be the output?
正解:A
解説:
To determine the output of the final statement, a Data Analyst must perform a step-by-step trace of the code execution, following standard order of operations (inner-to-outer) and procedural logic within the Snowflake Scripting environment.
Step 1: Evaluating the innermost function, func2(10)
The definition for func2 takes a number p and returns p + 10.
* Input: 10
* Calculation: $10 + 10 = 20$
* Result: 20
Step 2: Evaluating the next function, func1(20)
The definition for func1 takes a number v and returns v + 10.
* Input: 20 (the result from Step 1)
* Calculation: $20 + 10 = 30$
* Result: 30
Step 3: Evaluating the procedure call, proc1(30)
The procedure proc1 takes an input variable named result. It then executes a conditional IF statement:
* Conditional Check: IF (result >= 30)
* Since the input is 30, the condition evaluates to True.
* Action: The procedure executes RETURN result - 10.
* Calculation: $30 - 10 = 20$
Summary of Logic:
The nested calls flow as follows: call proc1(30) $\rightarrow$ proc1 evaluates $30 \ge 30$ $\rightarrow$ proc1 returns $30 - 10$, which is 20. If the initial input had been lower, such that the final result passed to the procedure was less than 30, it would have followed the ELSE branch and returned the original value. This question evaluates the analyst's ability to interpret modular code and procedural control flow, which are key components of the Data Transformation and Data Modeling domain in the SnowPro Advanced: Data Analyst exam.
質問 # 30
You are analyzing website traffic data in Snowflake using Snowsight. The data is stored in a table 'WEB TRAFFIC' with columns 'VISIT DATE (DATE), 'PAGE URL' (VARCHAR), 'VISITOR_ID (VARCHAR), and (INT - in seconds). You need to create a Snowsight dashboard to answer the following questions: 1. What is the average session duration per page URL? 2. What is the distribution of session durations (histogram)? 3. How many unique visitors are there per day? Which of the following approaches is the MOST efficient and appropriate for creating this Snowsight dashboard?
正解:E
解説:
Option A is the most efficient and appropriate. Snowsight's direct SQL query functionality, coupled with the 'WIDTH_BUCKET' function, provides a straightforward and performant way to create the required visualizations. Using views (Option E) adds an unnecessary layer of abstraction. Trying to combine all visualizations into a single tile (Options B and D) is not suitable for the different visualization types. Using Snowsight Notebook (Option C) introduces unnecessary overhead for this relatively simple descriptive analysis task. While Notebooks are powerful, they're best used for more complex data transformations and analysis that SQL cannot easily handle.
質問 # 31
You are tasked with analyzing website traffic data stored in a Snowflake table named 'page_views'. The table has columns 'user_id' (INT), 'page_url (VARCHAR), and 'view_time' (TIMESTAMP N T Z). You need to identify users who are likely bots based on an unusually high number of page views within a short period. Specifically, you want to flag users who have more than 100 page views within any 5-minute window Which of the following queries is the MOST efficient and accurate way to achieve this?





正解:E
解説:
Option C is the most accurate and efficient. It correctly calculates the number of views within a 5-minute window for each user using the 'DATE DIFF function and a window function. It then filters to only include users who exceed 100 views in any of those windows, and ensures each user is only counted once with the DISTINCT keyword. Option A is incorrect because it only looks at total page views across the entire dataset. Option B is syntactically incorrect and doesn't implement the time window. Option D is truncating by minute and then groups across that resulting in incorrect aggregation. The correct function is 'DATE DIFF, not 'DATE TRUNC and the logic for window is incorrect. Option E will result in errors as TUMBLE_START requires view_time to be timestamp_ltz or timestamp_tz data type.
質問 # 32
......
試験準備のための学習資料を見つけている場合、当社の資料は検索を終了します。私たちのDAA-C01試験トレントは、あなたが期待できない高品質を持っています。 DAA-C01試験トレントは時間を大幅に節約するのに役立ち、あなたがやりたいことをする自由時間が増えると思います。私たちのDAA-C01テスト問題集の使用について後悔がないことを保証できます。アクションの時間が来たら、思考を止めて、入って、私たちのDAA-C01試験トレントを試してください。DAA-C01試験に合格し、短時間で証明書を取得する必要があります。
DAA-C01専門トレーリング: https://www.mogiexam.com/DAA-C01-exam.html
BONUS!!! MogiExam DAA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1XjF9sIm-7F-Rg18mfUNltUwF_EYQVG_t