2026 Latest Exam4Free Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1PgcGrmRuUulaeJ1oHGAqPqu7nSRIMFc7
Our web backend is strong for our Databricks-Generative-AI-Engineer-Associate study braindumps. No matter how many people are browsing our websites at the same time, you still can quickly choose your favorite Databricks-Generative-AI-Engineer-Associate exam questions and quickly pay for it. There has no delay reaction of our website. So you can begin your pleasant selecting journey on our websites. And you will find our Databricks-Generative-AI-Engineer-Associate practice materials are easy to download.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate Exam |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 45 |
| Available Languages: | Japanese, Brazilian Portuguese, English, Korean |
| Exam Format: | Multiple choice |
| Passing Score: | 700/1000 or 70% |
| Exam Price: | USD 200 |
| Exam Duration: | 90 minutes |
| Recommended Training: | Generative AI Engineering with Databricks |
| Exam Registration: | Databricks Certification Registration |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person test center |
| Pre Condition: | No formal prerequisites; recommended 6+ months hands-on experience building generative AI solutions |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Latest Databricks-Generative-AI-Engineer-Associate Test Questions <<
Exam4Free online digital Databricks Databricks-Generative-AI-Engineer-Associate exam questions are the best way to prepare. Using our Databricks Databricks-Generative-AI-Engineer-Associate exam dumps, you will not have to worry about whatever topics you need to master. To practice for a Databricks Databricks-Generative-AI-Engineer-Associate Certification Exam in the software (free test), you should perform a self-assessment.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 93
A Generative AI Engineer has been reviewing issues with their company ' s LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
Answer: C
Explanation:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity.
Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to " identify the legal jurisdiction, " followed by a step to " extract relevant statutes, " and finally a step to " summarize the findings. " This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output.
It also allows for intermediate validation and error handling between steps, which is impossible in a single- call architecture.
NEW QUESTION # 94
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: D
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance.
Let's evaluate the options.
* Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation
* Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent'stool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
* Databricks Reference:"Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems"("Databricks Feature Engineering Guide," 2023).
* Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool
* Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
* Databricks Reference:"Direct SQL queries are flexible but may introduce overhead in real-time applications"("Building LLM Applications with Databricks").
* Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation
* Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
* Databricks Reference:"Vector search excels for unstructured data, not structured tabular lookups"("Databricks Vector Search Documentation").
* Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation
* Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
* Databricks Reference:"Avoid external systems when Delta tables provide real-time data natively"("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 95
A company has a typical RAG-enabled, customer-facing chatbot on its website.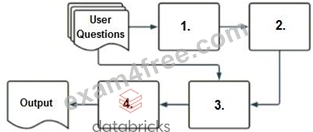
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
NEW QUESTION # 96
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. Thematch should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
Answer: D
NEW QUESTION # 97
A Generative AI Engineer developed an LLM application using the provisioned throughput Foundation Model API. Now that the application is ready to be deployed, they realize their volume of requests are not sufficiently high enough to create their own provisioned throughput endpoint. They want to choose a strategy that ensures the best cost-effectiveness for their application.
What strategy should the Generative AI Engineer use?
Answer: C
Explanation:
* Problem Context: The engineer needs a cost-effective deployment strategy for an LLM application with relatively low request volume.
* Explanation of Options:
* Option A: Switching to external models may not provide the required control or integration necessary for specific application needs.
* Option B: Using a pay-per-token model is cost-effective, especially for applications with variable or low request volumes, as it aligns costs directly with usage.
* Option C: Changing to a model with fewer parameters could reduce costs, but might also impact the performance and capabilities of the application.
* Option D: Manually throttling requests is a less efficient and potentially error-prone strategy for managing costs.
OptionBis ideal, offering flexibility and cost control, aligning expenses directly with the application's usage patterns.
NEW QUESTION # 98
......
Free Databricks-Generative-AI-Engineer-Associate Learning Cram: https://www.exam4free.com/Databricks-Generative-AI-Engineer-Associate-valid-dumps.html
BTW, DOWNLOAD part of Exam4Free Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1PgcGrmRuUulaeJ1oHGAqPqu7nSRIMFc7