P.S. Free 2026 CompTIA DY0-001 dumps are available on Google Drive shared by VCE4Dumps: https://drive.google.com/open?id=1nRZJCYdCP3ueBQhBVBIYI3rLycjVwXzD
If you are anxious about whether you can pass your exam and get the certificate, we think you need to buy our DY0-001 study materials as your study tool, our product will lend you a good helping hand. If you are willing to take our DY0-001 study materials into more consideration, it must be very easy for you to pass your exam in a short time. 99% people who have used our DY0-001 Study Materials passed their exam and got their certificate successfully, it is no doubt that it means our DY0-001 study materials have a 99% pass rate. So our product will be a very good choice for you.
| Section | Weight | Objectives |
|---|---|---|
| Specialized Applications of Data Science | 13% | - Specialized Domains
|
| Operations and Processes | 22% | - Business & Data Lifecycle
|
| Modeling, Analysis, and Outcomes | 24% | - Feature Engineering & Transformation
|
| Mathematics and Statistics | 17% | - Statistical Methods and Concepts
|
| Machine Learning | 24% | - Foundational Concepts
|
This format enables you to assess your DY0-001 test preparation with a DY0-001 practice exam. You can also customize your time and the kinds of questions of the CompTIA DY0-001 Practice Test. This CompTIA DataAI Certification Exam DY0-001 practice test imitates the CompTIA DY0-001 real exam pattern. Thus, it helps you kill CompTIA DataAI Certification Exam exam anxiety.
NEW QUESTION # 30
Which of the following distributions would be best to use for hypothesis testing on a data set with 20 observations?
Answer: B
Explanation:
# For small sample sizes (typically n < 30), the Student's t-distribution is preferred over the normal distribution for hypothesis testing because it accounts for the added uncertainty in the estimate of the standard deviation. With 20 observations, the t-distribution is more appropriate and reliable.
Why the other options are incorrect:
* A: Power law is used in modeling rare events or heavy-tailed distributions, not hypothesis testing.
* B: The normal distribution is more appropriate when the sample size is large.
* C: Uniform distribution assumes equal probability - not used in inferential statistics.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 1.3:"The t-distribution is used for small sample hypothesis testing where the population standard deviation is unknown."
-
NEW QUESTION # 31
A statistician notices gaps in data associated with age-related illnesses and wants to further aggregate these observations. Which of the following is the best technique to achieve this goal?
Answer: C
Explanation:
Binning groups continuous age values into discrete intervals (e.g., age ranges), filling gaps by aggregating observations into broader categories. This directly addresses uneven or sparse age data by creating consistent age groups.
NEW QUESTION # 32
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are shown.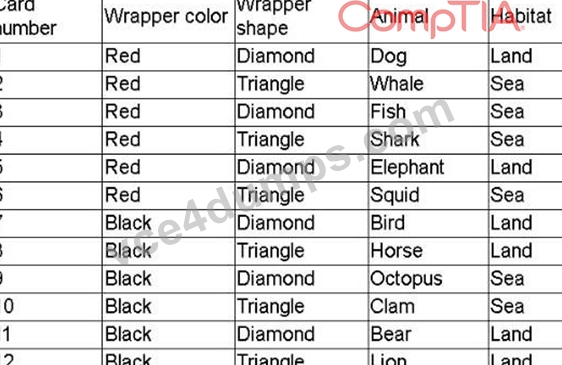
The data scientist is tasked with designing an initial model iteration to predict whether the animal on the card lives in the sea or on land, given the card's features: Wrapper color, Wrapper shape, and Animal.
Which of the following is the best way to accomplish this task?
Answer: D
Explanation:
# Decision trees are supervised classification models that can be used to predict a categorical target variable (e.
g., Habitat: Land or Sea) based on input features (e.g., Wrapper color, Wrapper shape, Animal type). They are interpretable, require minimal preprocessing, and are ideal for structured categorical data like this.
Why the other options are incorrect:
* A: ARIMA (AutoRegressive Integrated Moving Average) is used for time-series forecasting, not classification.
* B: Linear regression is used for predicting continuous numeric values, not categorical variables like
"Land" or "Sea".
* C: Association rules (like in market basket analysis) are used to discover relationships or co-occurrence among variables, not to build predictive models.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.1 & 4.2:"Decision trees are powerful classifiers for categorical output variables and allow for interpretable models based on feature splits."
* Machine Learning Textbook, Chapter 6:"Decision trees are ideal for early-stage model prototyping when the output is categorical and the data structure is tabular."
NEW QUESTION # 33
A data scientist receives an update on a business case about a machine that has thousands of error codes. The data scientist creates the following summary statistics profile while reviewing the logs for each machine: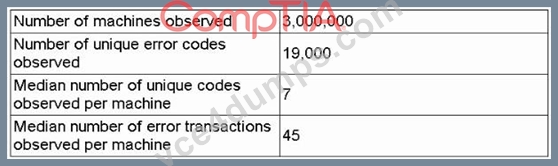
| Number of machines observed | 3,000,000
| Number of unique error codes observed | 19,000
| Median number of unique codes per machine | 7
| Median number of error transactions | 45
Which of the following is the most likely concern with respect to data design for model ingestion?
Answer: A
Explanation:
# With 19,000 unique error codes and only 7 codes per machine (on median), the data structure will likely consist of a very large number of binary features (e.g., one-hot encoded error codes), most of which will be 0 for any given machine. This leads to a sparse matrix-where the majority of elements are zero-which poses computational and modeling challenges.
Why the other options are incorrect:
* B: Granularity misalignment would mean mismatched levels (e.g., mixing daily and hourly data), which is not the issue here.
* C: There are many features (error codes), not too few.
* D: Multivariate outliers involve unusual combinations across features, not sparsity.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"High-cardinality categorical features can result in sparse matrices, especially when one-hot encoded for models."
NEW QUESTION # 34
Which of the following describes the appropriate use case for PCA?
Answer: A
Explanation:
# Principal Component Analysis (PCA) is an unsupervised technique used to reduce the dimensionality of large datasets by transforming correlated features into a smaller set of uncorrelated components (principal components) while retaining the most variance.
Why the other options are incorrect:
* B: Classification is a predictive modeling task; PCA is not inherently predictive.
* C: Regression models numerical relationships; PCA does not predict outcomes.
* D: Recommendation systems use collaborative or content filtering, not PCA directly.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"PCA is primarily used for reducing the number of variables while preserving data structure and minimizing information loss."
* Pattern Recognition and Machine Learning, Chapter 12:"PCA identifies principal axes of variation and is widely used in preprocessing for dimensionality reduction."
-
NEW QUESTION # 35
......
There is a succession of anecdotes, and there are specialized courses. Experts call them experts, and they must have their advantages. They are professionals in every particular field. The DY0-001 test material, in order to enhance the scientific nature of the learning platform, specifically hired a large number of qualification exam experts, composed of product high IQ team, these experts by combining his many years teaching experience of DY0-001 quiz guide and research achievements in the field of the test, to exam the popularization was very complicated content of CompTIA DataAI Certification Exam exam dumps, better meet the needs of users of various kinds of cultural level. Expert team not only provides the high quality for the DY0-001 Quiz guide consulting, also help users solve problems at the same time, leak fill a vacancy, and finally to deepen the user's impression, to solve the problem of CompTIA test material and no longer make the same mistake.
DY0-001 Dumps Torrent: https://www.vce4dumps.com/DY0-001-valid-torrent.html
What's more, part of that VCE4Dumps DY0-001 dumps now are free: https://drive.google.com/open?id=1nRZJCYdCP3ueBQhBVBIYI3rLycjVwXzD