BONUS!!! Download part of NewPassLeader DP-800 dumps for free: https://drive.google.com/open?id=1YtHmYz-CGIxKySaeN4k7kjPSpn3VLaiF
Our DP-800 study prep has inspired millions of exam candidates to pursuit their dreams and motivated them to learn more high-efficiently. Many customers get manifest improvement. DP-800 simulating exam will inspire your potential. And you will be more successful with the help of our DP-800 training guide. Just imagine that when you have the certification, you will have a lot of opportunities to come to the bigger companies and get a higher salary.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement data solutions | - Design database solutions using Azure data services - Implement data storage and data processing solutions |
| Topic 2: Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Topic 3: Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
| Topic 4: Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
>> DP-800 Latest Test Online <<
The top features of NewPassLeader DP-800 exam questions are the availability of Microsoft certification exam in three different formats, real, valid, and updated DP-800 exam questions, subject matter experts verified DP-800 Exam Questions, free demo download facility, 1 year updated DP-800 exam questions download facility, affordable price and 100 percent Microsoft DP-800 exam passing money back guarantee.
NEW QUESTION # 50
You have a database that contains production data. The schema is stored in a Git repository as an SDK-style SQL database project and contains the following reference data.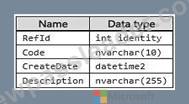
A deployment pipeline can be rerun automatically when a transient failure occurs.
You need to deploy the reference data as part of the same CI/CD process. Rerunning the pipeline must produce the same outcome and must NOT create duplicate rows.
What should you do?
Answer: A
Explanation:
To ensure your reference data deployment is idempotent (safe to rerun) and prevents duplicates within an SDK-style SQL project, you should use a Post-Deployment Script combined with a MERGE statement.
The Core Strategy: MERGE Statement
The MERGE command allows you to synchronize a target table with a source (your hardcoded data) in a single atomic operation. It checks for existing records based on a unique key and decides whether to insert, update, or delete.
Implementation Steps
1. Create a Seed Script
Add a file named Script.PostDeployment.sql to your project.
Set the Build Action to PostDeploy in the file properties.
2. Handle the Identity Column
Since RefID is an IDENTITY column, you must use SET IDENTITY_INSERT [Table] ON to specify exact IDs.
This ensures RefID values remain consistent across environments.
3. Write the Idempotent Logic
Define your reference data in a Common Table Expression (CTE) or a virtual table.
Use the sCode or RefID as the join key to find matches.
Reference:
https://www.mssqltips.com/sqlservertip/5648/including-predetermined-datasets-in-a-microsoft- database-project/
NEW QUESTION # 51
You have an Azure SQL database named SalesDB
You have a Data API builder (DAB) instance that exposes the following entities in SalesDB
* A table entity named Order mapped to a table named dbo. Orders
* A stored procedure entity named FinalizeOrder mapped to a stored procedure named dbo.usp_FinalizeOrder The DAB runtime configuration includes the following permissions.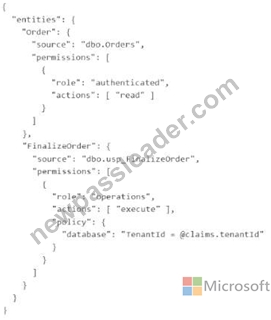
Client requests include a Microsoft Entra access token. The client also sends HTTP header x-MS-APl-ROlE:
operations for both REST and GraphQL requests.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.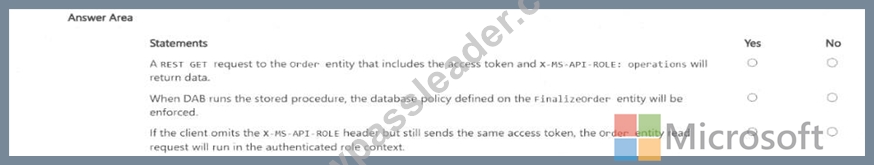
Answer:
Explanation: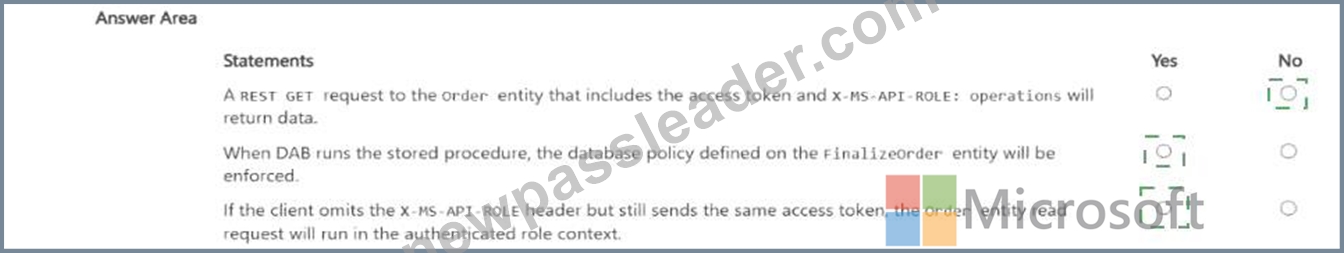
Explanation:
* A REST GET request to the order entity that includes the access token and x-MS-API-ROLE:
operations will return data. # No
* When DAB runs the stored procedure, the database policy defined on the FinalizeOrder entity will be enforced. # Yes
* If the client omits the x-MS-API-ROLE header but still sends the same access token, the order entity read request will run in the authenticated role context. # Yes The first statement is No . In Data API builder, when a valid token is sent with X-MS-API-ROLE, the request runs in that requested role if that role is present in the token . Here, that means the effective role becomes operations , not authenticated. But the order entity grants read only to the authenticated role, not to operations, so the GET request would not be authorized to return data.
The second statement is Yes . DAB evaluates the request against the permissions and policies configured for the effective role on the requested entity. The FinalizeOrder entity grants execute to role operations and includes a database policy of TenantId = @claims.tenantid, so that policy is part of the enforced authorization
/filtering behavior when the stored procedure entity is executed.
The third statement is Yes . If the client sends a valid access token without X-MS-API-ROLE, DAB uses the built-in Authenticated system role by default. Since the order entity allows read for the authenticated role, that read request runs in the authenticated role context.
Top of Form
Bottom of Form
NEW QUESTION # 52
You have an Azure SQL database named AdventureWorksDB that contains a table named dbo.Employee.
You have a C# Azure Functions app that uses an HTTP-triggered function with an Azure SQL input binding to query dbo.Employee.
You are adding a second function that will react to row changes in dbo.Employee and write structured logs.
You need to configure AdventureWorksDB and the app to meet the following requirements:
- Changes to dbo.Employee must trigger the new function within five
seconds.
- Each invocation must process no more than 100 changes.
Which two database configurations should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
To use an Azure SQL trigger in an Azure Functions app, you must perform the following two database configurations:
Enable change tracking on the database: You must turn on change tracking at the database level to allow the system to monitor for row-level modifications.
Enable change tracking on the table: You must specifically enable change tracking for the table that the second function is monitoring.
These configurations are mandatory for the Azure SQL trigger to detect inserts, updates, and deletes.
Incorrect:
Configuring Timing and Batching
While the database setup enables the tracking mechanism, the specific performance requirements (triggering within five seconds and processing no more than 100 changes) are managed through application settings in the Azure Function app, rather than database-side configurations:
Sql_Trigger_MaxBatchSize: Set this to 100 to ensure each invocation processes no more than
100 changes.
Sql_Trigger_PollingIntervalMs: Set this to 5000 (5,000 milliseconds) or less to ensure changes are detected and triggered within five seconds.
Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-bindings-azure-sql-trigger
NEW QUESTION # 53
You have an Azure SQL database that contains a table named Rooms. Rooms was created by using the following transact-SQL statement.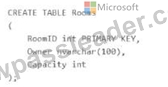
You discover that some records in the Rooms table contain NULL values for the Owner field. You need to ensure that all future records have a value for the Owner field. What should you add?
Answer: B
Explanation:
The table definition allows Owner to be nullable because it was created as Owner nvarchar(100) without NOT NULL. Since the question asks what to add so that future rows must have a value, a check constraint such as CHECK (Owner IS NOT NULL) is the appropriate choice. Microsoft documents that check constraints validate future INSERT and UPDATE operations against the constraint condition.
The other options do not solve the requirement:
* A foreign key enforces referential integrity, not non-null entry by itself.
* A nonclustered index does not require values to be present.
* A unique constraint prevents duplicate values but still does not serve as the right mechanism here for enforcing presence across future writes. Microsoft's constraint documentation also notes that primary- key columns are implicitly NOT NULL, which helps distinguish nullability enforcement from other constraint types.
NEW QUESTION # 54
You need to meet the development requirements for the FeedbackJson column How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.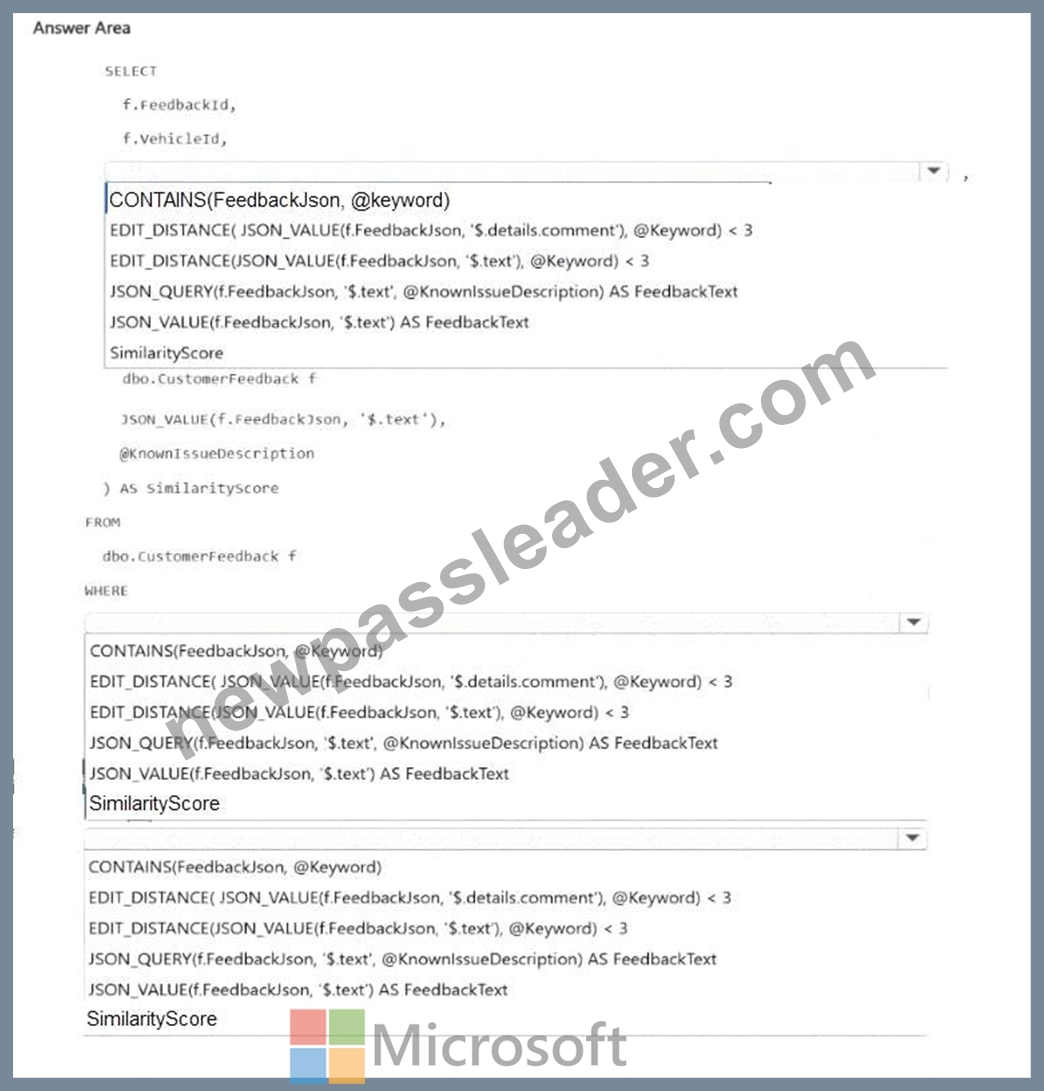
Answer:
Explanation: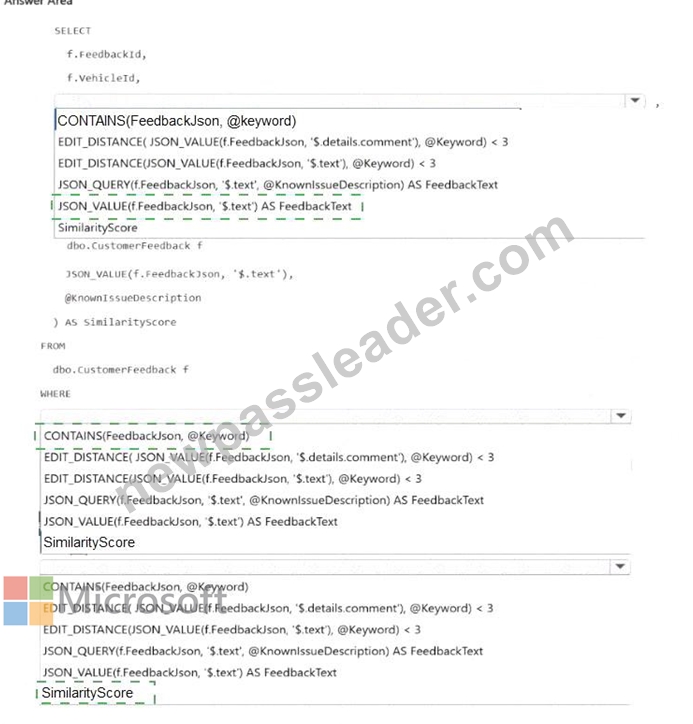
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document , the correct expression is JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText . Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array .
Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword , the best choice is CONTAINS (FeedbackJson, @Keyword) . The scenario explicitly states that FeedbackJson already has a full-text index
, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first , the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 55
......
Even in a globalized market, the learning material of similar DP-800 doesn't have much of a share, nor does it have a high reputation or popularity. In this dynamic and competitive market, the DP-800 learning questions can be said to be leading and have absolute advantages. In order to facilitate the user real-time detection of the learning process, we DP-800 Exam Material provided by the questions and answers are all in the past.it is closely associated, as our experts in constantly update products every day to ensure the accuracy of the problem, so all DP-800 practice materials are high accuracy.
DP-800 Valid Exam Pattern: https://www.newpassleader.com/Microsoft/DP-800-exam-preparation-materials.html
What's more, part of that NewPassLeader DP-800 dumps now are free: https://drive.google.com/open?id=1YtHmYz-CGIxKySaeN4k7kjPSpn3VLaiF