2026 Latest TestValid DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1qBJRveeSc-CsZZgxwVK22QY7QhRPLtN7
We can guarantee that our study materials will be suitable for all people and meet the demands of all people, including students, workers and housewives and so on. If you decide to buy and use the DP-100 study materials from our company with dedication on and enthusiasm step and step, it will be very easy for you to pass the exam without doubt. We sincerely hope that you can achieve your dream in the near future by the DP-100 Study Materials of our company.
Microsoft DP-100 certification exam covers a wide range of topics related to data science and machine learning. It requires candidates to have a deep understanding of Azure data services, including Azure Machine Learning, Azure Stream Analytics, and Azure Data Factory. DP-100 exam also tests candidates' knowledge of statistical analysis, data visualization, and data exploration techniques.
The DP-100 exam is a hands-on practical exam that requires the candidate to demonstrate their ability to design and implement data science solutions on Azure. DP-100 Exam includes various tasks, such as creating machine learning models, building data pipelines, and deploying models to production environments. The tasks are designed to simulate real-world scenarios that data scientists and engineers face in their jobs.
>> New DP-100 Braindumps Ebook <<
The Microsoft DP-100 certification exam also enables you to stay updated and competitive in the market which will help you to gain more career opportunities. Do you want to gain all these Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam benefits? Looking for the quick and complete Microsoft DP-100 exam dumps preparation way that enables you to pass the DP-100 Certification Exam with good scores? If your answer is yes then you are at the right place and you do not need to go anywhere. Just download the TestValid DP-100 Questions and start Designing and Implementing a Data Science Solution on Azure (DP-100) exam preparation without wasting further time.
After successfully passing the Microsoft DP-100 Exam, you will obtain the Microsoft Certified: Azure Data Scientist Associate certification. Getting certified will allow you to qualify for several positions, including the following titles:
Obtaining this certification is also beneficial from a financial point of view. In fact, the average salary that a certified professional can earn is $96,642 per year.
NEW QUESTION # 58
You need to set up the Permutation Feature Importance module according to the model training requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.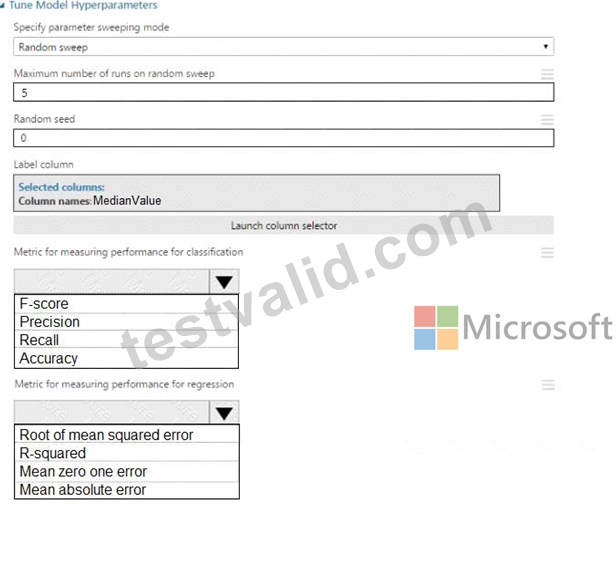
Answer:
Explanation: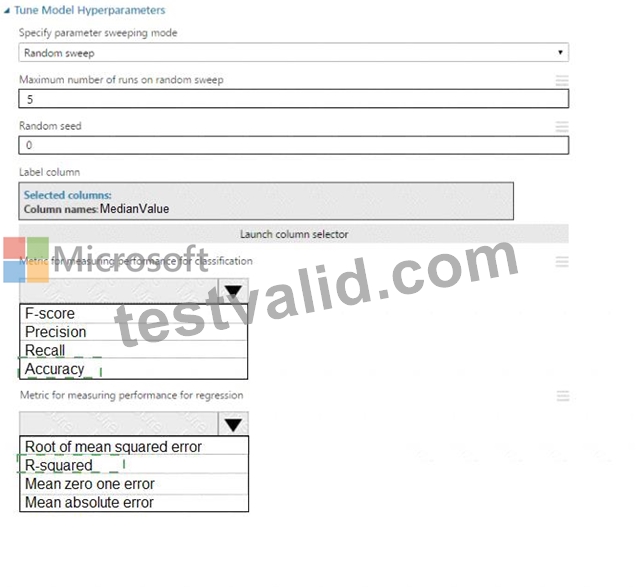
Explanation: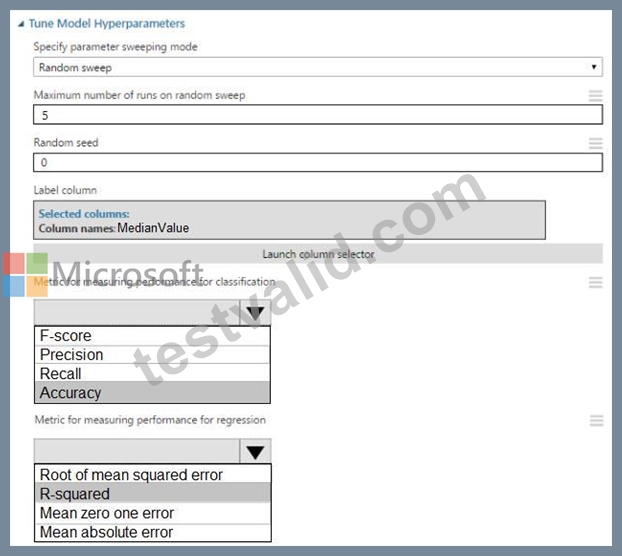
Box 1: Accuracy
Scenario: You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
Box 2: R-Squared
NEW QUESTION # 59
You create an Azure Machine Learning dataset. You use the Azure Machine Learning designer to transform the dataset by using an Execute Python Script component and custom code.
You must upload the script and associated libraries as a script bundle.
You need to configure the Execute Python Script component.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE Each correct selection is worth one point.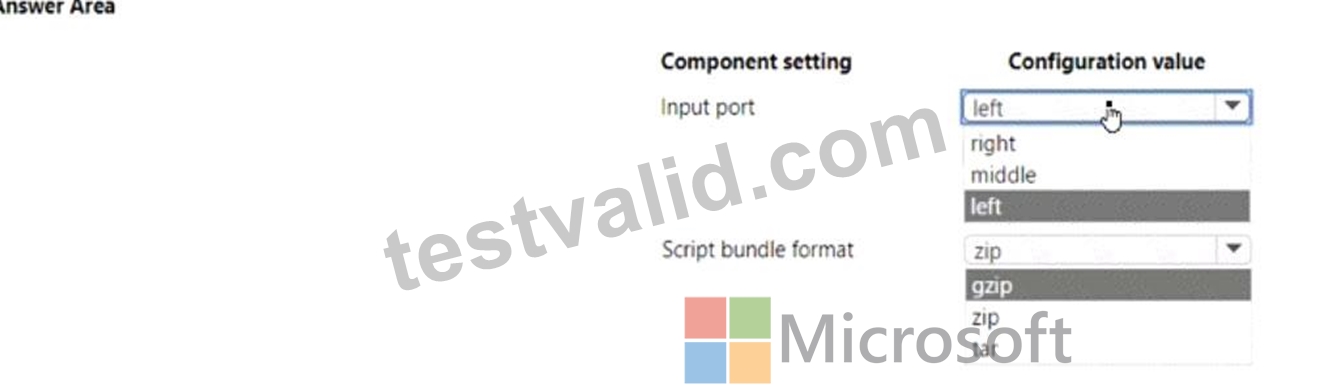
Answer:
Explanation: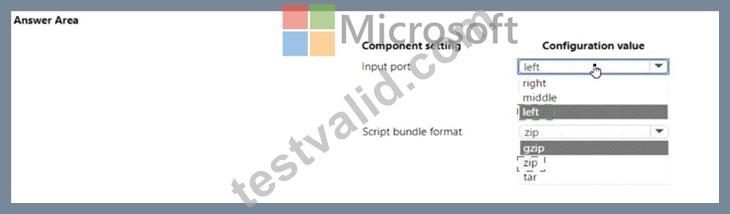
Explanation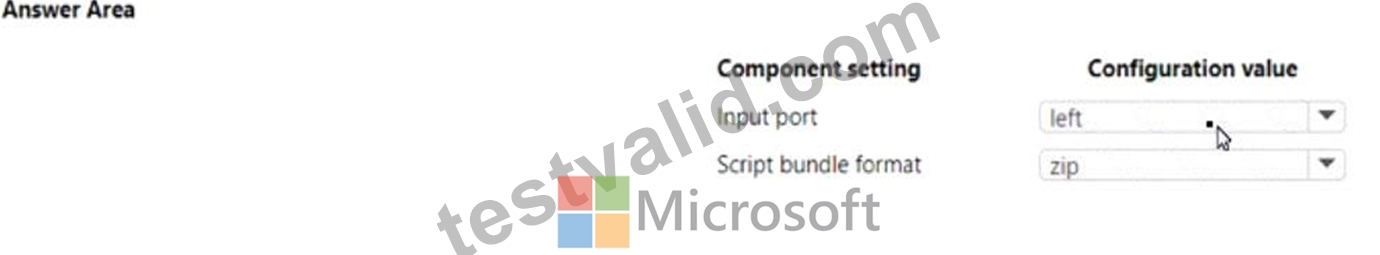
NEW QUESTION # 60
You have an Azure Machine Learning workspace that contains a training cluster and an inference cluster.
You plan to create a classification model by using the Azure Machine Learning designer.
You need to ensure that client applications can submit data as HTTP requests and receive predictions as responses.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.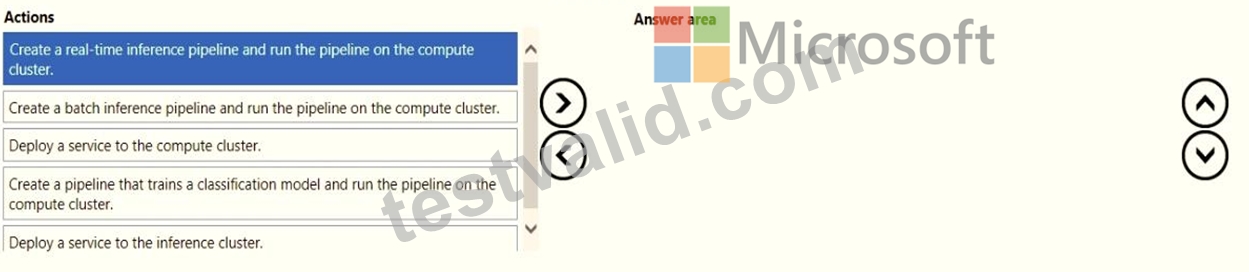
Answer:
Explanation: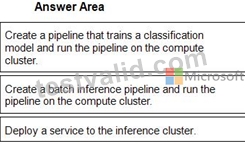
1 - Create a pipeline that trains a classification model and run the pipeline on the compute cluster.
2 - Create a batch inference pipeline and run the pipeline on the compute cluster.
3 - Deploy a service to the inference cluster.
NEW QUESTION # 61
You use Azure Machine Learning to implement hyperparameter tuning for an Azure ML Python SDK v2- based model training.
Training runs must terminate when the primary metric is lowered by 25 percent or more compared to the best performing run.
You need to configure an early termination policy to terminate training jobs.
Which values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.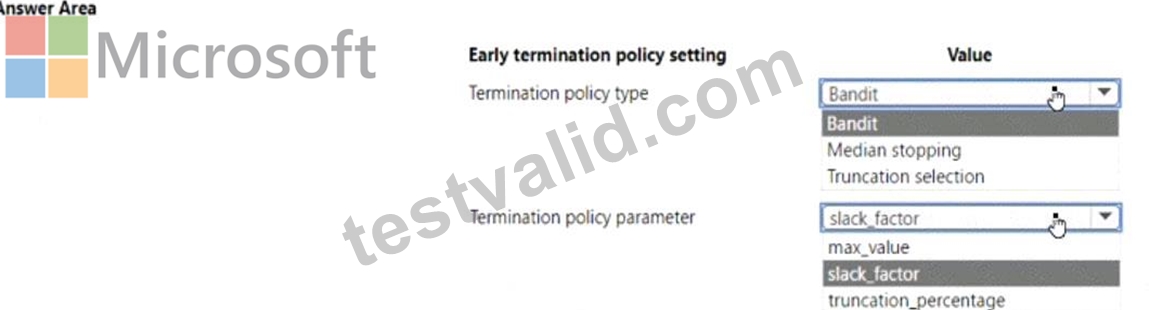
Answer:
Explanation: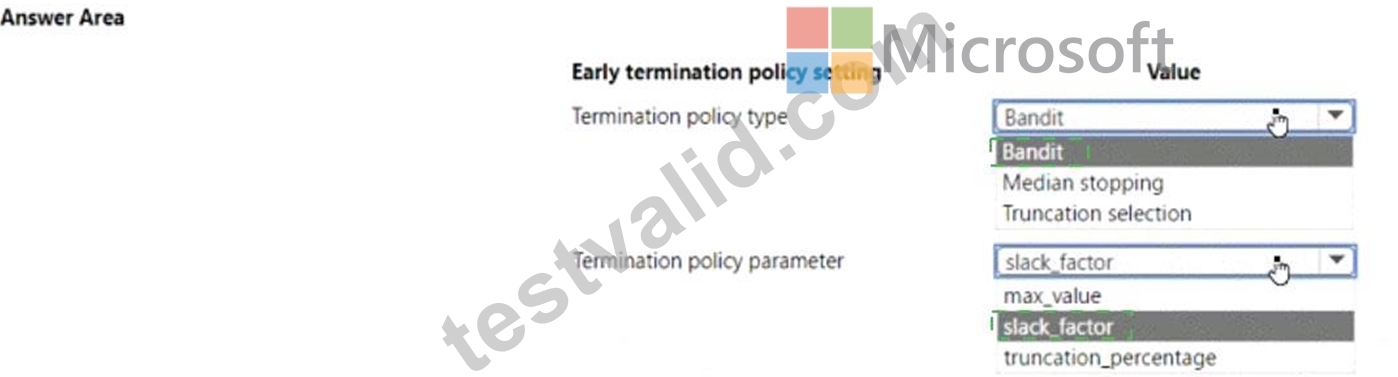
Explanation: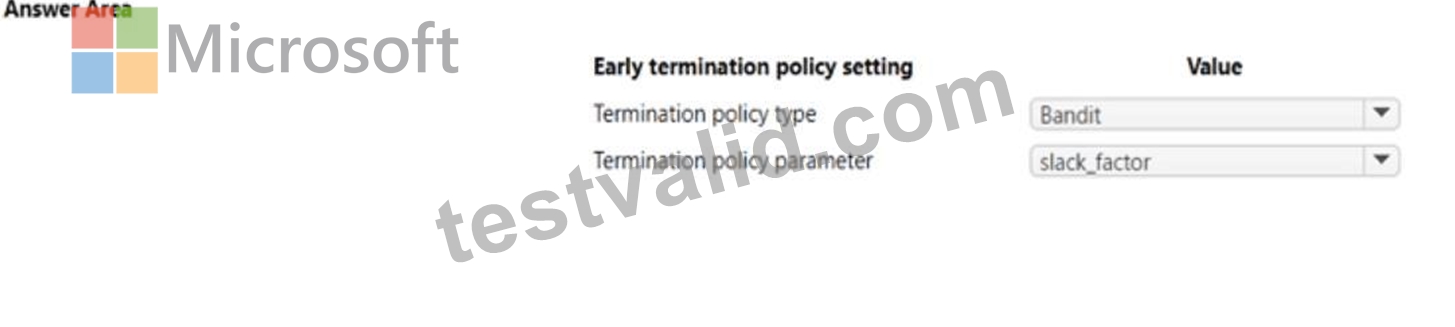
NEW QUESTION # 62
You are solving a classification task.
You must evaluate your model on a limited data sample by using k-fold cross-validation. You start by configuring a k parameter as the number of splits.
You need to configure the k parameter for the cross-validation.
Which value should you use?
Answer: D
Explanation:
Leave One Out (LOO) cross-validation
Setting K = n (the number of observations) yields n-fold and is called leave-one out cross-validation (LOO), a special case of the K-fold approach.
LOO CV is sometimes useful but typically doesn't shake up the data enough. The estimates from each fold are highly correlated and hence their average can have high variance.
This is why the usual choice is K=5 or 10. It provides a good compromise for the bias-variance tradeoff.
Perform Feature Engineering
Testlet 1
Case study
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
* Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
* Assess a user's tendency to respond to an advertisement.
* Customize styles of ads served on mobile devices.
* Use video to detect penalty events
Current environment
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo formats.
Penalty detection and sentiment
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
* Ad response rated declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too slow.
* Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
* The performance of the global penalty detection models shows lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation models must optimize for similar ad response history.
* Sampling must guarantee mutual and collective exclusively between local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Ad response models must support non-linear boundaries of features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from
0.1 +/- 5%.
* The ad propensity model uses cost factors shown in the following diagram: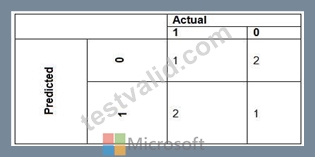
* The ad propensity model uses proposed cost factors shown in the following diagram: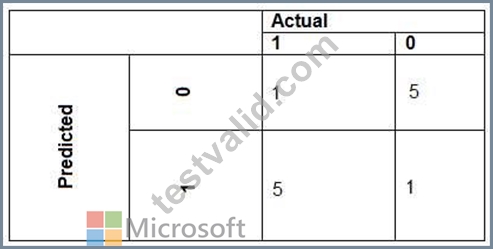
* Performance curves of current and proposed cost factor scenarios are shown in the following diagram: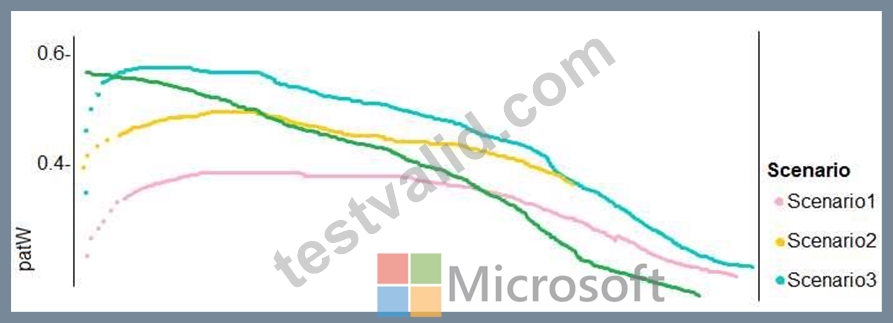
NEW QUESTION # 63
......
New DP-100 Learning Materials: https://www.testvalid.com/DP-100-exam-collection.html
DOWNLOAD the newest TestValid DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qBJRveeSc-CsZZgxwVK22QY7QhRPLtN7