This updated Databricks Certified-Data-Engineer-Professional exam study material of BraindumpStudy consists of these 3 formats: Databricks Certified-Data-Engineer-Professional PDF, desktop practice test software, and web-based practice exam. Each format of BraindumpStudy aids a specific preparation style and offers unique advantages, each of which is beneficial for strong Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam preparation. The features of our three formats are listed below. You can choose any format as per your practice needs.
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
>> Certified-Data-Engineer-Professional Valid Test Prep <<
New latest Databricks Certified-Data-Engineer-Professional valid exam study guide can help you exam in short time. Candidates can save a lot time and energy on preparation. It is a shortcut for puzzled examinees to purchase Certified-Data-Engineer-Professional valid exam study guide. If you choose our products, you only need to practice questions several times repeatedly before the real test. Our products are high-quality and high passing rate, and then you will obtain many better opportunities.
NEW QUESTION # 119
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: B
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 120
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
Answer: D
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks.
NEW QUESTION # 121
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: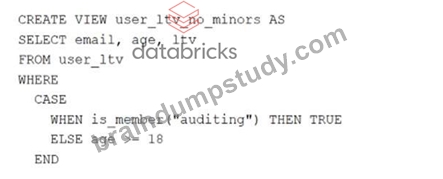
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 122
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
Answer: A
Explanation:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted.
NEW QUESTION # 123
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
Answer: D
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 124
......
If you are still in colleges, it is a good chance to learn the knowledge of the Certified-Data-Engineer-Professional study engine because you have much time. At present, many office workers are keen on learning our Certified-Data-Engineer-Professional guide materials even if they are busy with their work. So you should never give up yourself as long as there has chances. In short, what you have learned on our Certified-Data-Engineer-Professional study engine will benefit your career development.
Certified-Data-Engineer-Professional Pass Test: https://www.braindumpstudy.com/Certified-Data-Engineer-Professional_braindumps.html