Try Before You Buy Free Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions Demos

The second form is Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) web-based practice test which can be accessed through online browsing. The Databricks-Certified-Professional-Data-Engineer web-based practice test is supported by browsers like Firefox, Microsoft Edge, Databricks Chrome, and Safari. You don't need to install any plugins or software to attempt the Databricks-Certified-Professional-Data-Engineer web-based practice test. This online Databricks Databricks-Certified-Professional-Data-Engineer exam is also compatible with all operating systems.
| Section | Objectives |
|---|
| Topic 1: Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling
- Pipeline reliability and fault tolerance
- Build and manage workflows using Databricks Jobs
|
| Topic 2: Data Modeling and Storage | - Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
- Delta Lake table design and optimization
|
| Topic 3: Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
|
| Topic 4: Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs
- Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
|
>> Databricks-Certified-Professional-Data-Engineer Dumps Vce <<
Buy DumpsReview Databricks Databricks-Certified-Professional-Data-Engineer Questions Today and Get Free Updates for one year
The empty promise is not enough. So our DumpsReview provides to all customers with the most comprehensive service of the highest quality including the free trial of Databricks-Certified-Professional-Data-Engineer software before you buy, and the one-year free update after purchase. We will be with you in every stage of your Databricks-Certified-Professional-Data-Engineer Exam Preparation to give you the most reliable help. Even if you still failed the Databricks-Certified-Professional-Data-Engineer certification exam, we will full refund to reduce your economic loss as much as possible.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q94-Q99):
NEW QUESTION # 94
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. Whenever a database is being created, make sure that the location keyword is used
- B. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- C. Whenever a table is being created, make sure that the location keyword is used.
- D. When tables are created, make sure that the external keyword is used in the create table statement.
- E. When the workspace is being configured, make sure that external cloud object storage has been mounted.
Answer: C
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 95
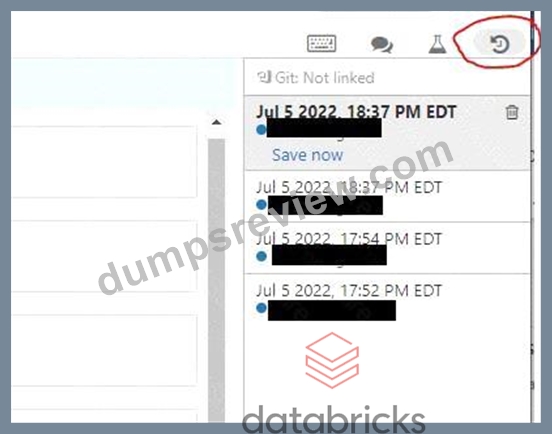
You are currently working with the second team and both teams are looking to modify the same notebook, you noticed that the second member is copying the notebooks to the personal folder to edit and replace the collaboration notebook, which notebook feature do you recommend to make the process easier to collaborate.
- A. Databricks Notebooks support real-time coauthoring on a single notebook
- B. Databricks notebooks can be exported into dbc archive files and stored in data lake
- C. Databricks notebooks support automatic change tracking and versioning
- D. Databricks notebook can be exported as HTML and imported at a later time
- E. Databricks notebooks should be copied to a local machine and setup source control lo-cally to version the notebooks
Answer: A
Explanation:
Explanation
Answer is Databricks Notebooks support real-time coauthoring on a single notebook Every change is saved, and a notebook can be changed my multiple users.
NEW QUESTION # 96
Which of the following techniques structured streaming uses to create an end-to-end fault toler-ance?
- A. Write ahead logging and water marking
- B. Write ahead logging and idempotent sinks
- C. Checkpointing and idempotent sinks
- D. Stream will failover to available nodes in the cluste
- E. Checkpointing and Water marking
Answer: C
Explanation:
Explanation
The answer is Checkpointing and idempotent sinks
How does structured streaming achieves end to end fault tolerance:
*First, Structured Streaming uses checkpointing and write-ahead logs to record the offset range of data being processed during each trigger interval.
*Next, the streaming sinks are designed to be _idempotent_-that is, multiple writes of the same data (as identified by the offset) do not result in duplicates being written to the sink.
Taken together, replayable data sources and idempotent sinks allow Structured Streaming to en-sure end-to-end, exactly-once semantics under any failure condition.
NEW QUESTION # 97
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
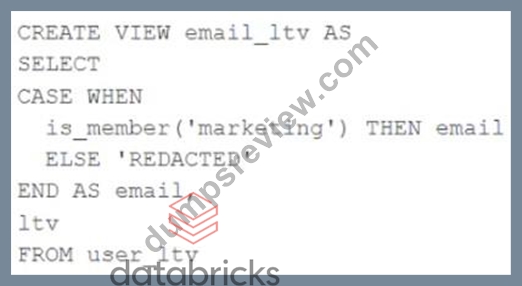
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. The email and ltv columns will be returned with the values in user itv.
- B. Only the email and ltv columns will be returned; the email column will contain the string "REDACTED" in each row.
- C. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- D. The email, age. and ltv columns will be returned with the values in user ltv.
- E. Only the email and itv columns will be returned; the email column will contain all null values.
Answer: B
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 98
The data engineering team maintains the following code:
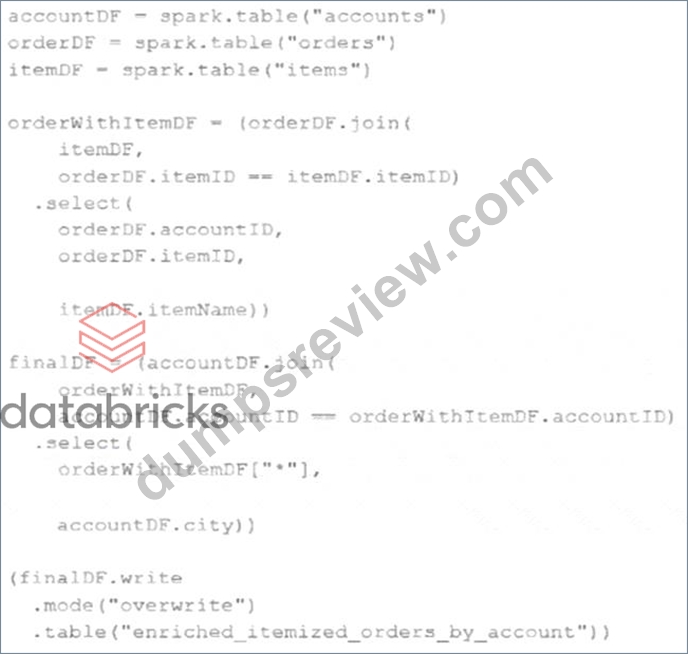
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- B. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- C. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- D. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- E. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
Answer: A
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 99
......
These Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test questions also boost your confidence. If you have prepared well, tried all the Databricks Databricks Certified Professional Data Engineer Exam Certification Exams, and understood each concept clearly, there is minimal or no chance of failure. Desktop Practice exam software and web-based Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test are available at DumpsReview.
New Databricks-Certified-Professional-Data-Engineer Test Vce Free: https://www.dumpsreview.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps-review.html
- Databricks-Certified-Professional-Data-Engineer Test Torrent - Databricks-Certified-Professional-Data-Engineer Learning Materials - Databricks-Certified-Professional-Data-Engineer Dumps VCE 🛸 Search for ( Databricks-Certified-Professional-Data-Engineer ) and download it for free immediately on ➽ www.verifieddumps.com 🢪 🔷New Databricks-Certified-Professional-Data-Engineer Exam Cram
- Latest Databricks-Certified-Professional-Data-Engineer Dumps Vce to Obtain Databricks Certification 🧸 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and download it for free immediately on 《 www.pdfvce.com 》 🐧Databricks-Certified-Professional-Data-Engineer Clear Exam
- Databricks-Certified-Professional-Data-Engineer Dump Collection 🌟 Databricks-Certified-Professional-Data-Engineer New Real Exam 🎉 Latest Databricks-Certified-Professional-Data-Engineer Test Objectives ✋ Enter ( www.practicevce.com ) and search for [ Databricks-Certified-Professional-Data-Engineer ] to download for free 🥦Databricks-Certified-Professional-Data-Engineer Latest Exam Registration
- Quiz 2026 Useful Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Dumps Vce ◀ { www.pdfvce.com } is best website to obtain ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download 🧺Databricks-Certified-Professional-Data-Engineer High Quality
- Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 📘 Databricks-Certified-Professional-Data-Engineer Passed 🕙 Databricks-Certified-Professional-Data-Engineer Latest Test Discount 🎳 Copy URL ▷ www.testkingpass.com ◁ open and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download for free 🈺Test Databricks-Certified-Professional-Data-Engineer Engine
- Quiz 2026 Useful Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Dumps Vce 📼 Immediately open { www.pdfvce.com } and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to obtain a free download 🟠Databricks-Certified-Professional-Data-Engineer Latest Exam Cram
- Quiz 2026 Useful Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Dumps Vce 🌱 Open website ▛ www.practicevce.com ▟ and search for { Databricks-Certified-Professional-Data-Engineer } for free download 🎭Valid Databricks-Certified-Professional-Data-Engineer Test Voucher
- Databricks-Certified-Professional-Data-Engineer Latest Test Discount 🍽 Latest Databricks-Certified-Professional-Data-Engineer Test Preparation 😅 Databricks-Certified-Professional-Data-Engineer Flexible Testing Engine 💙 Search on ☀ www.pdfvce.com ️☀️ for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to obtain exam materials for free download ⬛Databricks-Certified-Professional-Data-Engineer Dump Collection
- Exam Databricks-Certified-Professional-Data-Engineer Discount 📔 Test Databricks-Certified-Professional-Data-Engineer Engine 🚎 Databricks-Certified-Professional-Data-Engineer High Quality ‼ Simply search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download on ➡ www.pdfdumps.com ️⬅️ 🦖Databricks-Certified-Professional-Data-Engineer New Real Exam
- Exam Databricks-Certified-Professional-Data-Engineer Discount 💘 Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 🤓 Latest Databricks-Certified-Professional-Data-Engineer Test Objectives 🕘 Download ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ for free by simply searching on ▛ www.pdfvce.com ▟ 🖌Valid Databricks-Certified-Professional-Data-Engineer Test Voucher
- Exam Databricks-Certified-Professional-Data-Engineer Discount 🥋 Databricks-Certified-Professional-Data-Engineer Clear Exam 🦙 Latest Databricks-Certified-Professional-Data-Engineer Test Objectives 😖 Open ➤ www.prepawayete.com ⮘ and search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 to download exam materials for free 🥈Exam Databricks-Certified-Professional-Data-Engineer Discount
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes