P.S.TopexamがGoogle Driveで共有している無料の2026 Nutanix NCM-MCI-6.10ダンプ:https://drive.google.com/open?id=1UfUmO2qj97lajOcNCzDGGKEbfIzsAof4
私たちのNCM-MCI-6.10問題集は有名で、多くの人に知られています。利用するとき、NCM-MCI-6.10問題の精確性をみつけることができます。だから、いい好評をもらいました。それはずっとNCM-MCI-6.10問題集に取り組んでいる専門家の苦労です。そして、NCM-MCI-6.10 問題集は定期的に更新されます。できるだけ、お客様に最新版を提供します。NCM-MCI-6.10問題集を選ばない理由はないです!
| Section | Objectives |
|---|---|
| Topic 1: Analyze and Optimize VM Performance | - Cluster and node metrics analysis - VM resource optimization |
| Topic 2: Advanced Configuration and Troubleshooting | - Third-party integrations - Risk mitigation configuration - Troubleshooting Nutanix services - CLI and API execution - Security posture analysis |
| Topic 3: Analyze and Optimize Storage Performance | - Workload performance evaluation - Storage internals and I/O analysis - Storage configuration optimization |
| Topic 4: Business Continuity | - Workload resilience evaluation - BCDR compliance analysis |
| Topic 5: Analyze and Optimize Network Performance | - Advanced network configuration - Physical and virtual network evaluation - Flow policies analysis and optimization - Overlay networking optimization |
当代社会の競争が激しいとともに、自分の生きがいを探すために、できるだけ自分の能力を生かさなければならない。IT業界でのあなたは自分の能力を高めるために、NCM-MCI-6.10試験を準備しているのでしょう。我々はNCM-MCI-6.10試験に参加するつもりのあなたに最高のサービスを提供します。我々の提供するNCM-MCI-6.10問題集を利用して、あなたは試験に合格することができると信じています。
質問 # 16
Task 3
An administrator needs to create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month.
No other entities should be included in the report.
The report should run monthly and should send an email to admin@syberdyne.net when it runs.
Generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip Note: Make sure the report and zip file are named correctly. The SMTP server will not be configured.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To create a report named VMs_Power_State that lists the VMs in the cluster and their basic details including the power state for the last month, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter VMs_Power_State as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, Cluster Name, vCPUs, Memory, Power State. Click Next.
Under the Time Period option, select Last Month. Click Next.
Under the Report Settings option, select Monthly from the Schedule drop-down menu. Enter admin@syberdyne.net as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.
To generate an instance of the report named VMs_Power_State as a CSV and save the zip file as Desktop\Files\VMs_Power_state.zip, you can follow these steps:
Log in to Prism Central and click on Operations on the left menu.
Select Reports from the drop-down menu and find the VMs_Power_State report from the list. Click on Run Now.
Wait for the report to be generated and click on Download Report. Save the file as Desktop\Files\VMs_Power_state.zip.
1.Open the Report section on Prism Central (Operations > Reports)
2.Click on the New Report button to start the creation of your custom report
3.Under the Custom Views section, select Data Table
4.Provide a title to your custom report, as well as a description if required.
5.Under the Entity Type option, select VM
6.This report can include all as well as a selection of the VMs
7.Click on the Custom Columns option and add the below variables:
a.Name - Name of the listed Virtual Machine
b.vCPUs - A combination of the vCores and vCPU's assigned to the Virtual Machine c.Memory - Amount of memory assigned to the Virtual Machine d.Disk Capacity - The total amount of assigned virtual disk capacity e.Disk Usage - The total used virtual disk capacity f.Snapshot Usage - The total amount of capacity used by snapshots (Excluding Protection Domain snapshots)
8.Under the Aggregation option for Memory and Disk Usage accept the default Average option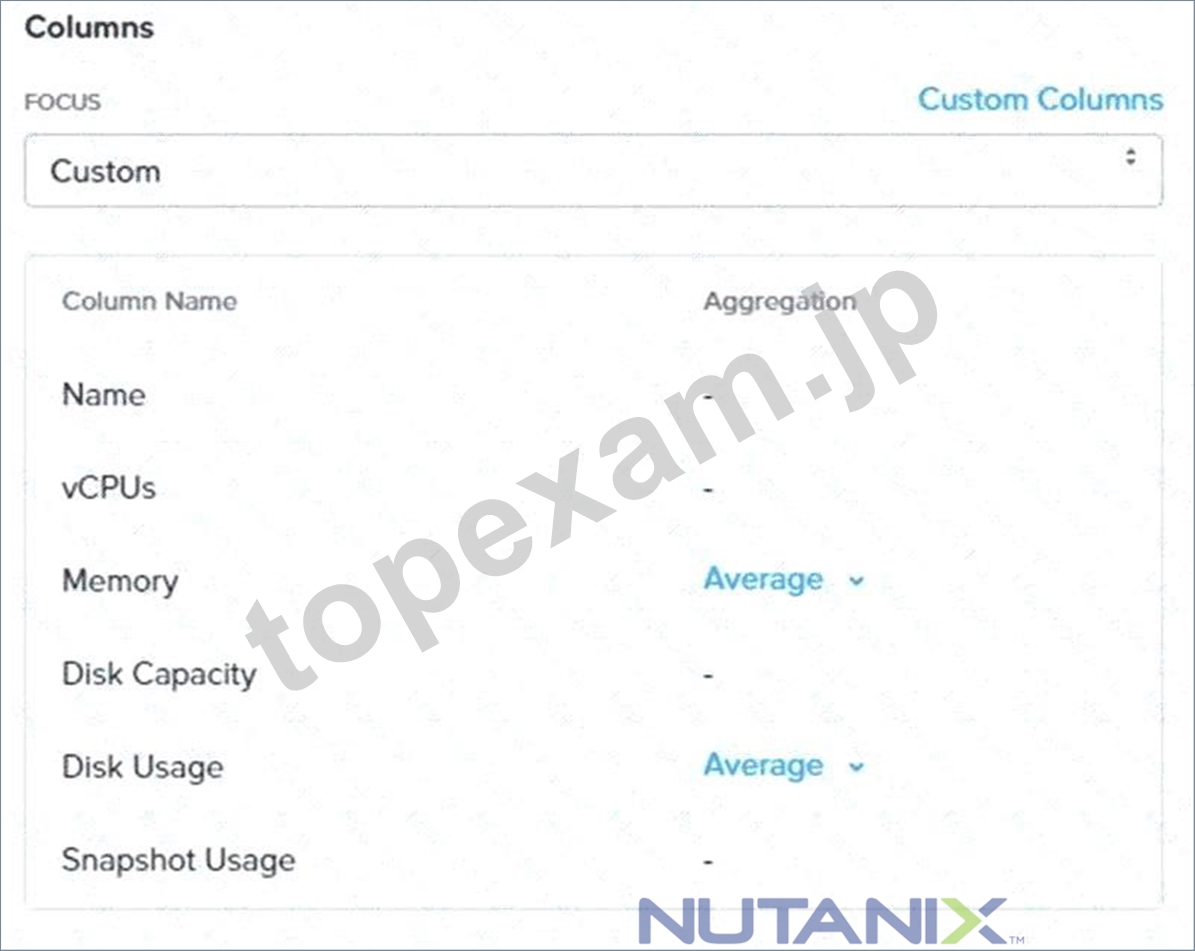
9.Click on the Add button to add this custom selection to your report
10.Next click on the Save and Run Now button on the bottom right of the screen
11.Provide the relevant details on this screen for your custom report:
12.You can leave the Time Period For Report variable at the default of Last 24 Hours
13.Specify a report output of preference (PDF or CSV) and if required Additional Recipients for this report to be mailed to. The report can also simply be downloaded after this creation and initial run if required
14.Below is an example of this report in a CSV format:
質問 # 17
Task 15
Depending on the order you perform the exam items, the access information and credentials could change.
Please refer to the other item performed on Cluster B if you have problems accessing the cluster.
The infosec team has requested that audit logs for API Requests and replication capabilities be enabled for all clusters for the top 4 severity levels and pushed to their syslog system using highest reliability possible. They have requested no other logs to be included.
Syslog configuration:
Syslog Name: Corp_syslog
Syslop IP: 34.69.43.123
Port: 514
Ensure the cluster is configured to meet these requirements.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To configure the cluster to meet the requirements of the infosec team, you need to do the following steps:
Log in to Prism Central and go to Network > Syslog Servers > Configure Syslog Server. Enter Corp_syslog as the Server Name, 34.69.43.123 as the IP Address, and 514 as the Port. Select TCP as the Transport Protocol and enable RELP (Reliable Logging Protocol). This will create a syslog server with the highest reliability possible.
Click Edit against Data Sources and select Cluster B as the cluster. Select API Requests and Replication as the data sources and set the log level to CRITICAL for both of them. This will enable audit logs for API requests and replication capabilities for the top 4 severity levels (EMERGENCY, ALERT, CRITICAL, and ERROR) and push them to the syslog server. Click Save.
Repeat step 2 for any other clusters that you want to configure with the same requirements.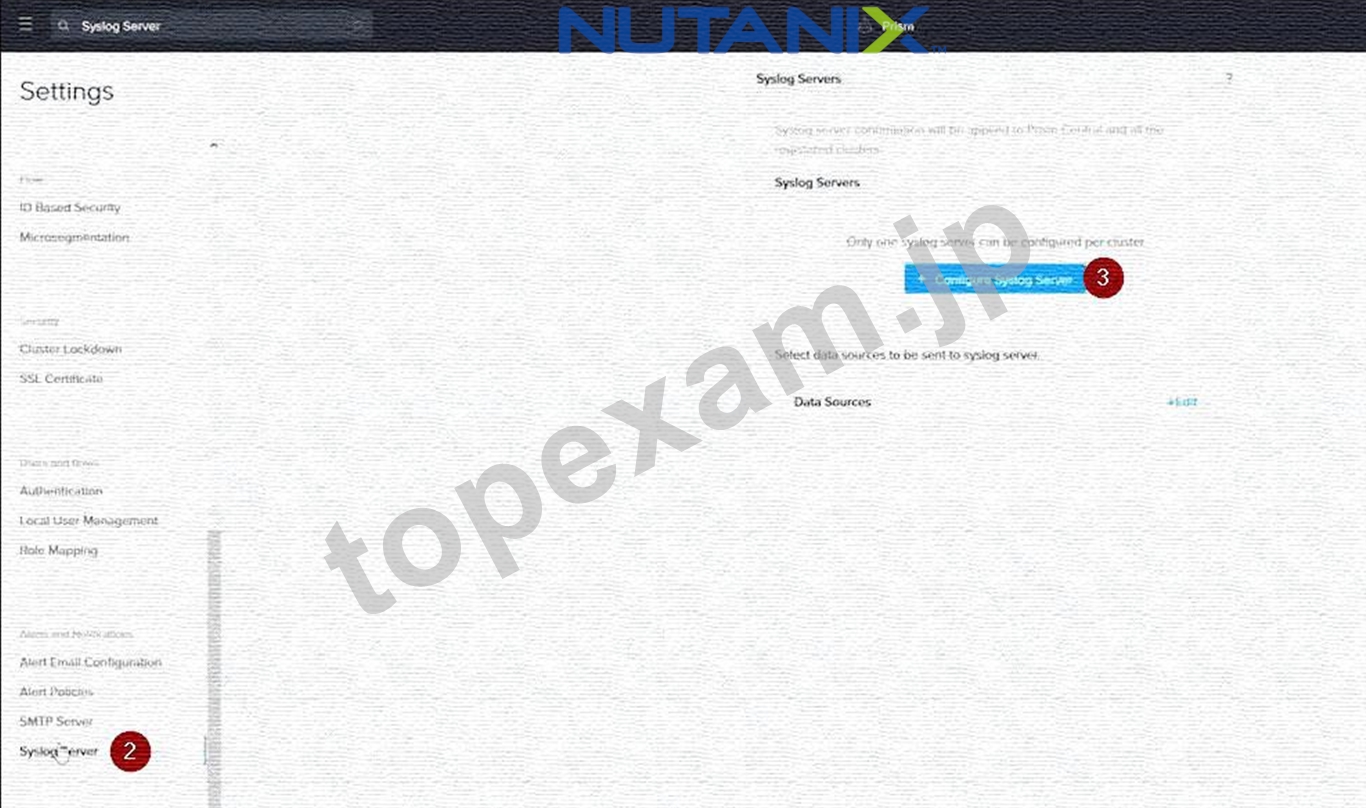
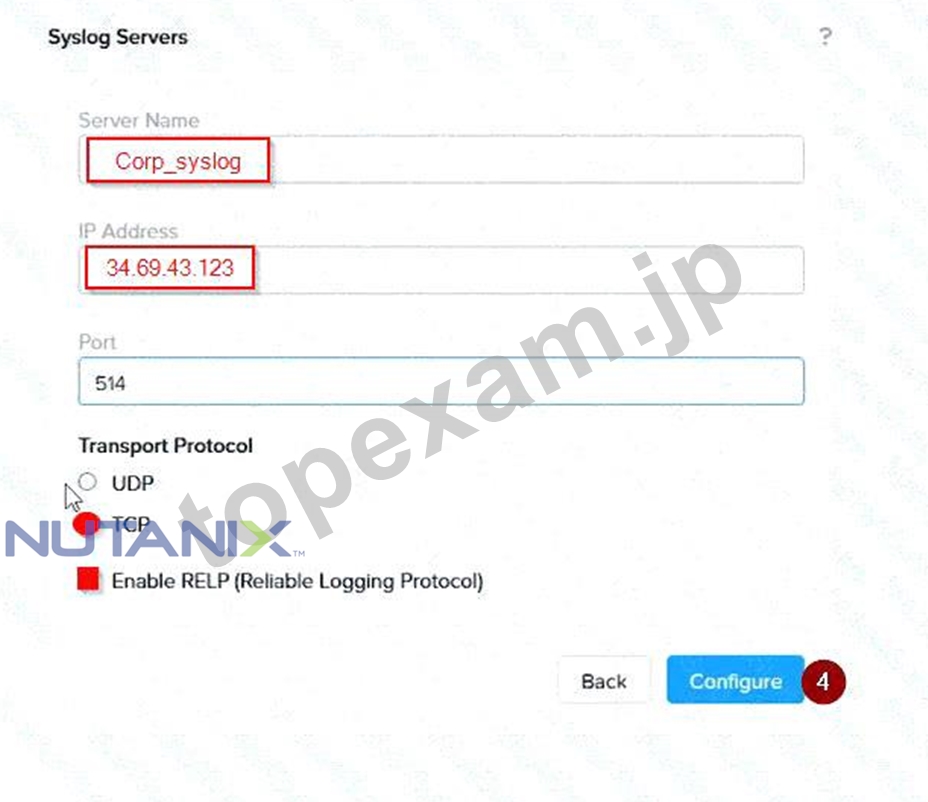
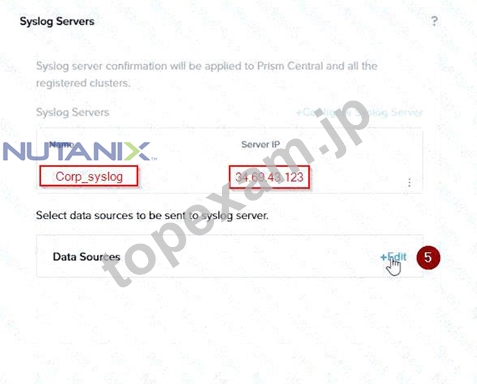
To configure the Nutanix clusters to enable audit logs for API Requests and replication capabilities, and push them to the syslog system with the highest reliability possible, you can follow these steps:
Log in to the Nutanix Prism web console using your administrator credentials.
Navigate to the "Settings" section or the configuration settings interface within Prism.
Locate the "Syslog Configuration" or "Logging" option and click on it.
Configure the syslog settings as follows:
Syslog Name: Enter "Corp_syslog" as the name for the syslog configuration.
Syslog IP: Set the IP address to "34.69.43.123", which is the IP address of the syslog system.
Port: Set the port to "514", which is the default port for syslog.
Enable the option for highest reliability or persistent logging, if available. This ensures that logs are sent reliably and not lost in case of network interruptions.
Save the syslog configuration.
Enable Audit Logs for API Requests:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and API requests. Enable the audit logging feature and select the top
4 severity levels to be logged.
Save the audit configuration.
Enable Audit Logs for Replication Capabilities:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and replication capabilities. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
After completing these steps, the Nutanix clusters will be configured to enable audit logs for API Requests and replication capabilities. The logs will be sent to the specified syslog system with the highest reliability possible.
ncli
<ncli> rsyslog-config set-status enable=false
<ncli> rsyslog-config add-server name=Corp_Syslog ip-address=34.69.43.123 port=514 network- protocol=tdp relp-enabled=false
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=APLOS level=INFO
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=CEREBRO level=INFO
<ncli> rsyslog-config set-status enable=true
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e0000009CEECA2
質問 # 18
Task 14
An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the data.
You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type.
Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster.
The datastore will provide low cost per GB and high performance for your distributed application.
質問 # 19
Use Prism Element for this question.
The Application team has a 3 tier application (App Server, Web Server, and Database Server) that is mission critical and requires as close to 0 RPO and RTO as possible with their current license level.
The organization has 2 clusters, with one cluster (Cluster 1) being production and the other cluster (Cluster 2) being remote/DR. Cluster 2 should be able to fail back to Cluster 1.
The connectivity between the two sites is >5ms and replication traffic should not use more than 10Mbps of bandwidth. The Application team requests a plan that includes the ability to go back 2 days locally, and 2 days remotely.
The team also requests that all 3 VMs be treated as a single group and backed up collectively in a snapshot.
The three VMs are:
* Web-Prod
* App-Prod
* DB-Prod
Use Task3 as part of the name for any objects created for this task.
Note: VMs do NOT need to be powered on. You will need to use the 172.30.0.x IP addresses when configuring DR.
正解:
解説:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Disaster Recovery from the Cluster 1 Prism Element interface.
1. Add Cluster 2 as a Remote Site
First, you must register Cluster 2 as a DR target for Cluster 1.
* From the Cluster 1 Prism Element dashboard, navigate to Data Protection from the main dropdown menu.
* Click the Remote Site tab.
* Click the + Remote Site button and select Physical Cluster.
* In the "Name" field, enter Cluster2_DR_Task3.
* In the "Address" field, enter the 172.30.0.x Virtual IP address of Cluster 2.
* Click Save. The clusters will exchange credentials and connect.
2. Throttle Replication Bandwidth
Next, apply the 10 Mbps bandwidth limit for traffic going to Cluster 2.
* On the same Remote Site tab, select the newly created Cluster2_DR_Task3.
* Click the Update button.
* In the dialog, set the Bandwidth Limit to 10 Mbps.
* Click Save.
3. Create the Protection Domain
A Protection Domain (PD) is the top-level object that will manage the VMs and replication schedules.
* In the Data Protection dashboard, click the Table tab.
* Click the + Protection Domain button and select Async DR.
* For the Name, enter App_PD_Task3.
* Click Create.
4. Protect VMs in a Consistency Group
Now you will add the three application VMs to the new Protection Domain as a single Consistency Group (CG).
* You will be taken to the dashboard for the new App_PD_Task3. In the Entities panel, click the Protect Entities button.
* In the "Protect Entities" dialog, search for and select the three VMs:
* Web-Prod
* App-Prod
* DB-Prod
* Click Next.
* Select Create new consistency group and name it App_CG_Task3.
* Click Protect.
5. Create the Replication Schedule
Finally, configure the schedule to meet the RPO and retention requirements.
* In the App_PD_Task3 dashboard, click the Schedules tab.
* Click the + New Schedule button.
* Remote Site: Select Cluster2_DR_Task3.
* RPO (Repeat every): Select NearSync. Set the RPO to 1 minute.
* Note: This is the lowest possible RPO for an Async (>5ms latency) connection, fulfilling the "as close to 0" requirement.
* Local Retention: Set to 2 Days.
* Remote Retention: Set to 2 Days.
* Ensure the "Store snapshots for 2-way replication" checkbox is enabled to allow failback from Cluster 2.
* Click Create Schedule.
質問 # 20
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
正解:
解説:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
質問 # 21
......
我々Topexamが数年以来商品の開発をしている目的はIT業界でよく発展したい人にNutanixのNCM-MCI-6.10試験に合格させることです。NutanixのNCM-MCI-6.10試験のための資料がたくさんありますが、Topexamの提供するのは一番信頼できます。我々の提供するソフトを利用する人のほとんどは順調にNutanixのNCM-MCI-6.10試験に合格しました。その中の一部は暇な時間だけでNutanixのNCM-MCI-6.10試験を準備します。
NCM-MCI-6.10合格記: https://www.topexam.jp/NCM-MCI-6.10_shiken.html
無料でクラウドストレージから最新のTopexam NCM-MCI-6.10 PDFダンプをダウンロードする:https://drive.google.com/open?id=1UfUmO2qj97lajOcNCzDGGKEbfIzsAof4