2026 Latest DumpsActual DEA-C01 PDF Dumps and DEA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1iHOeMRVCBPyjqtNeyvTgl1VC_zNMamTT
It can be difficult to prepare for the Snowflake DEA-C01 exam successfully, but with actual and updated SnowPro Advanced: Data Engineer Certification Exam (DEA-C01) exam questions, it can be much simpler. The difference between successful and failed DEA-C01 Certification Exam attempts can be determined by studying with real DEA-C01 exam questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Snowflake DEA-C01 Practice Questions <<
Quality should be tested by time and quantity, which is also the guarantee that we give you to provide DEA-C01 exam software for you. Continuous update of the exam questions, and professional analysis from our professional team have become the key for most candidates to Pass DEA-C01 Exam. The promise of "no help, full refund" is the motivation of our team. We will continue improving DEA-C01 exam study materials. We will guarantee that you you can share the latest DEA-C01 exam study materials free during one year after your payment.
NEW QUESTION # 277
Snowflake computes and adds partitions based on the defined partition column expressions when an external table metadata is refreshed.
What are the Correct Statements to configure Partition metadata refresh in case of External Tables?
Answer: A,B
Explanation:
Explanation
Snowflake strongly recommend partitioning your external tables, which requires that your underly-ing data is organized using logical paths that include date, time, country, or similar dimensions in the path.
Partitioning divides your external table data into multiple parts using partition columns.
An external table definition can include multiple partition columns, which impose a multi-dimensional structure on the external data.
Partitions are stored in the external table metadata.
Benefits of partitioning include improved query performance.
Because the external data is partitioned into separate slices/parts, query response time is faster when processing a small part of the data instead of scanning the entire data set.
Based on your individual use cases, you can either:
Add new partitions automatically by refreshing an external table that defines an expression for each partition column.
Add new partitions manually.
Partition columns are defined when an external table is created, using the CREATE EXTERNAL TABLE ...
PARTITION BY syntax.
After an external table is created, the method by which partitions are added cannot be changed.
Partitions Added Automatically
An external table creator defines partition columns in a new external table as expressions that parse the path and/or filename information stored in the METADATA$FILENAME pseudocolumn.
A partition consists of all data files that match the path and/or filename in the expression for the partition column.
The CREATE EXTERNAL TABLE syntax for adding partitions automatically based on expres-sions is as follows:
CREATE EXTERNAL TABLE
<table_name>
( <part_col_name> <col_type> AS <part_expr> )
[ , ... ]
[ PARTITION BY ( <part_col_name> [, <part_col_name> ... ] ) ]
Snowflake computes and adds partitions based on the defined partition column expressions when an external table metadata is refreshed.
By default, the metadata is refreshed automatically when the object is created.
In addition, the object owner can configure the metadata to refresh automatically when new or up-dated data files are available in the external stage.
The owner can alternatively refresh the metadata manually by executing the ALTER EXTERNAL TABLE ...
REFRESH command.
The metadata for an external table can be refreshed automatically using the event notification ser-vice for your cloud storage service.
NEW QUESTION # 278
A large table with 200 columns contains two years of historical data. When queried. the table is filtered on a single day Below is the Query Profile: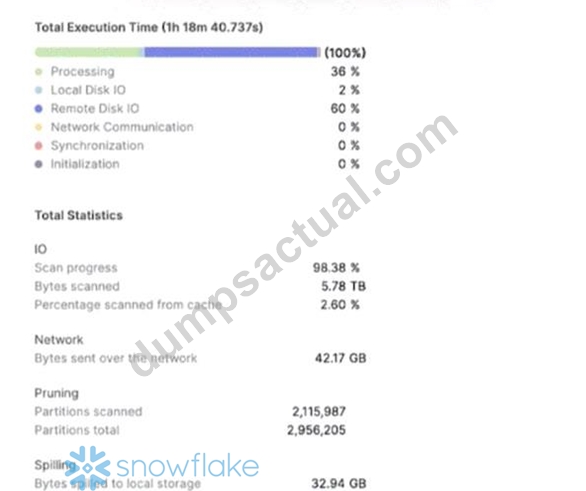
Using a size 2XL virtual warehouse, this query look over an hour to complete What will improve the query performance the MOST?
Answer: D
Explanation:
Explanation
Adding a date column as a cluster key on the table will improve the query performance by reducing the number of micro-partitions that need to be scanned. Since the table is filtered on a single day, clustering by date will make the query more selective and efficient.
NEW QUESTION # 279
Company A and Company B both have Snowflake accounts. Company A's account is hosted on a different cloud provider and region than Company B's account Companies A and B are not in the same Snowflake organization.
How can Company A share data with Company B? (Select TWO).
Answer: B,C
Explanation:
Explanation
The ways that Company A can share data with Company B are:
Create a share within Company A's account and add Company B's account as a recipient of that share:
This is a valid way to share data between different accounts on different cloud platforms and regions.
Snowflake supports cross-cloud and cross-region data sharing, which allows users to create shares and grant access to other accounts regardless of their cloud platform or region. However, this option may incur additional costs for network transfer and storage replication.
Create a separate database within Company A's account to contain only those data sets they wish to share with Company B Create a share within Company A'saccount and add all the objects within this separate database to the share Add Company B's account as a recipient of the share: This is also a valid way to share data between different accounts on different cloud platforms and regions. This option is similar to the previous one, except that it uses a separate database to isolate the data sets that need to be shared. This can improve security and manageability of the shared data. The other options are not valid because:
Create a share within Company A's account, and create a reader account that is a recipient of the share Grant Company B access to the reader account: This option is not valid because reader accounts are not supported for cross-cloud or cross-region data sharing. Reader accounts are Snowflake accounts that can only consume data from shares created by their provider account. Reader accounts must be on the same cloud platform and region as their provider account.
Use database replication to replicate Company A's data into Company B's account Create a share within Company B's account and grant users within Company B's account access to the share: This option is not valid because database replication cannot be used for cross-cloud or cross-region data sharing.
Database replication is a feature in Snowflake that allows users to copy databases across accounts within the same cloud platform and region. Database replication cannot copy databases across different cloud platforms or regions.
Create a new account within Company A's organization in the same cloud provider and region as Company B's account Use database replication to replicate Company A's data to the new account Create a share within the new account and add Company B's account as a recipient of that share: This option is not valid because it involves creating a new account within Company A's organization, which may not be feasible or desirable for Company A. Moreover, this option is unnecessary, as Company A can directly share data with Company B without creating an intermediate account.
NEW QUESTION # 280
To advance the offset of a stream to the current table version without consuming the change data in a DML operation, which of the following operations can be done by Data Engineer? [Select 2]
Answer: A,C
Explanation:
Explanation
When created, a stream logically takes an initial snapshot of every row in the source object (e.g. ta-ble, external table, or the underlying tables for a view) by initializing a point in time (called an off-set) as the current transactional version of the object. The change tracking system utilized by the stream then records information about the DML changes after this snapshot was taken. Change rec-ords provide thestate of a row before and after the change. Change information mirrors the column structure of the tracked source object and includes additional metadata columns that describe each change event.
Note that a stream itself does not contain any table data. A stream only stores an offset for the source object and returns CDC records by leveraging the versioning history for the source object.
A new table version is created whenever a transaction that includes one or more DML statements is committed to the table.
In the transaction history for a table, a stream offset is located between two table versions. Query-ing a stream returns the changes caused by transactions committed after the offset and at or before the current time.
Multiple queries can independently consume the same change data from a stream without changing the offset.
A stream advances the offset only when it is used in a DML transaction. This behavior applies to both explicit and autocommit transactions. (By default, when a DML statement is execut-ed, an autocommit transaction is implicitly started and the transaction is committed at the comple-tion of the statement. This behavior is controlled with the AUTOCOMMIT parameter.) Querying a stream alone does not advance its offset, even within an explicit transaction; the stream contents must be consumed in a DML statement.
To advance the offset of a stream to the current table version without consuming the change data in a DML operation, complete either of the following actions:
Recreate the stream (using the CREATE OR REPLACE STREAM syntax).
Insert the current change data into a temporary table. In the INSERT statement, query the stream but include a WHERE clause that filters out all of the change data (e.g. WHERE 0 = 1).
NEW QUESTION # 281
A company has implemented a lake house architecture in Amazon Redshift. The company needs to give users the ability to authenticate into Redshift query editor by using a third-party identity provider (IdP).
A data engineer must set up the authentication mechanism.
What is the first step the data engineer should take to meet this requirement?
Answer: D
Explanation:
To enable users to authenticate into the Amazon Redshift query editor using a third-party identity provider (IdP), the data engineer must first register that IdP within the configuration settings of the Redshift cluster itself.
Amazon Redshift natively supports integrating with external identity providers to manage user authentication. By registering the third-party IdP directly in the Redshift cluster settings, it establishes the trust relationship needed for Redshift to rely on that IdP for authenticating users when they log into the query editor.
NEW QUESTION # 282
......
All contents of the DEA-C01 exam questions are masterpieces from experts who imparted essence of the exam into our DEA-C01 study prep. So our high quality and high efficiency DEA-C01 practice materials conciliate wide acceptance around the world. By incubating all useful content DEA-C01 training engine get passing rate from former exam candidates of 98 which evince our accuracy rate and proficiency.
Reliable DEA-C01 Test Objectives: https://www.dumpsactual.com/DEA-C01-actualtests-dumps.html
P.S. Free & New DEA-C01 dumps are available on Google Drive shared by DumpsActual: https://drive.google.com/open?id=1iHOeMRVCBPyjqtNeyvTgl1VC_zNMamTT