P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Dumps4PDF: https://drive.google.com/open?id=1lRpSW_YauEYQqgkf663bSsxCSCoNvyZT
Nowadays, the Databricks-Generative-AI-Engineer-Associate certificate is popular among job seekers. After all, the enormous companies attach great importance to your skills. If you can obtain the Databricks-Generative-AI-Engineer-Associate certificate, you will have the greatest chance to get the job. So you need to improve yourself during your spare time. Maybe you are always worrying that you are too busy to prapare for an exam, but our Databricks-Generative-AI-Engineer-Associate Training Materials will help you obtain the certification in the lest time for the advantage of high-efficency.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Reliable Databricks-Generative-AI-Engineer-Associate Dumps Free <<
In our study, we found that many people have the strongest ability to use knowledge for a period of time at the beginning of their knowledge. As time goes on, memory fades. Our Databricks-Generative-AI-Engineer-Associate study materials are designed to help users consolidate what they have learned, will add to the instant of many training, the user can test their learning effect in time after finished the part of the learning content, have a special set of wrong topics in our Databricks-Generative-AI-Engineer-Associate Study Materials, enable users to find their weak spot of knowledge in this function, iterate through constant practice, finally reach a high success rate.
NEW QUESTION # 26
After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:
What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)
Answer: D,E
Explanation:
* Problem Context: After switching to a model with a shorter context length, the error message indicating that the prompt token count has exceeded the limit suggests that the input to the model is too large.
* Explanation of Options:
* Option A: Use a smaller embedding model to generate- This wouldn't necessarily address the issue of prompt size exceeding the model's token limit.
* Option B: Reduce the maximum output tokens of the new model- This option affects the output length, not the size of the input being too large.
* Option C: Decrease the chunk size of embedded documents- This would help reduce the size of each document chunk fed into the model, ensuring that the input remains within the model's context length limitations.
* Option D: Reduce the number of records retrieved from the vector database- By retrieving fewer records, the total input size to the model can be managed more effectively, keeping it within the allowable token limits.
* Option E: Retrain the response generating model using ALiBi- Retraining the model is contrary to the stipulation not to change the response generating model.
OptionsCandDare the most effective solutions to manage the model's shorter context length without changing the model itself, by adjusting the input size both in terms of individual document size and total documents retrieved.
NEW QUESTION # 27
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company's customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
Answer: A
Explanation:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined "automatically" by the serving infrastructure because they require either human feedback or an LLM-as-a-judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not "default operational metrics" that appear without additional evaluation configuration.
NEW QUESTION # 28
A Generative AI Engineer is building a RAG application that will rely on context retrieved from source documents that are currently in PDF format. These PDFs can contain both text and images. They want to develop a solution using the least amount of lines of code.
Which Python package should be used to extract the text from the source documents?
Answer: B
Explanation:
* Problem Context: The engineer needs to extract text from PDF documents, which may contain both text and images. The goal is to find a Python package that simplifies this task using the least amount of code.
* Explanation of Options:
* Option A: flask: Flask is a web framework for Python, not suitable for processing or extracting content from PDFs.
* Option B: beautifulsoup: Beautiful Soup is designed for parsing HTML and XML documents, not PDFs.
* Option C: unstructured: This Python package is specifically designed to work with unstructured data, including extracting text from PDFs. It provides functionalities to handle various types of content in documents with minimal coding, making it ideal for the task.
* Option D: numpy: Numpy is a powerful library for numerical computing in Python and does not provide any tools for text extraction from PDFs.
Given the requirement,Option C(unstructured) is the most appropriate as it directly addresses the need to efficiently extract text from PDF documents with minimal code.
NEW QUESTION # 29
A company has a typical RAG-enabled, customer-facing chatbot on its website.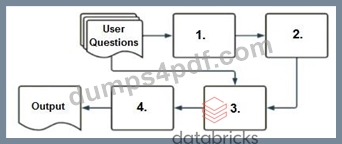
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
Embedding Model (1):
The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
Vector Search (2):
The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
Context-Augmented Prompt (3):
The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
Response-Generating LLM (4):
Finally, the context-augmented prompt is fed into a response-generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response-generating LLM, which is option A.
NEW QUESTION # 30
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: D
NEW QUESTION # 31
......
We believe that the best brands are those that go beyond expectations. They don't just do the job – they go deeper and become the fabric of our lives. Our product boosts many merits and functions. You can download and try out our Databricks-Generative-AI-Engineer-Associate test question freely before the purchase. You can use our product immediately after you buy our product. We provide 3 versions for you to choose and you only need 20-30 hours to learn our Databricks-Generative-AI-Engineer-Associate Training Materials and prepare the exam. The passing rate and the hit rate are both high.
Databricks-Generative-AI-Engineer-Associate Testking Learning Materials: https://www.dumps4pdf.com/Databricks-Generative-AI-Engineer-Associate-valid-braindumps.html
BTW, DOWNLOAD part of Dumps4PDF Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1lRpSW_YauEYQqgkf663bSsxCSCoNvyZT