P.S. Kostenlose 2026 Microsoft DP-100 Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1VeQ4yq2SXA3UYbkwPFEgUDXJFOedJjHC
Sie können im Internet kostenlos die Software und Prüfungsfragen und Antworten zur Microsoft DP-100 Zertifizierungsprüfung als Probe herunterladen. It-Pruefung wird Ihnen helfen, die Microsoft DP-100 Zertifizierungsprüfung zu bestehen. Wenn Sie unvorsichtigerweise in der Prüfung durchfallen, erstatten wir Ihnen Ihre an uns geleistene Zahlung.
| Section | Weight | Objectives |
|---|---|---|
| Prepare a model for deployment | 20-25% | - Deploy machine learning models
|
| Explore data and train models | 35-40% | - Optimize model performance
|
| Design and prepare a machine learning solution | 20-25% | - Design an Azure Machine Learning workspace
|
| Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
Viele Leute, die in der IT-Branche arbeiten, wissen die mühsame Vorbereitung auf die Microsoft DP-100 Prüfung. Wir It-Pruefung können doch den Schwierigkeitsgrad der Microsoft DP-100 Prüfung nicht ändern, aber wir können die Schwierigkeitsgrad der Vorbereitung für Sie vermindern. Ihre Angst vor der Microsoft DP-100 Prüfung wird beseitigen, solange Sie die Prüfungsunterlagen von unserem Technik-Team probiert haben. Wir tun unser Bestes, um Ihnen zu helfen, Ihre Konfidenz für Microsoft DP-100 zu verstärken!
193. Frage
You register a model that you plan to use in a batch inference pipeline.
The batch inference pipeline must use a ParallelRunStep step to process files in a file dataset.
The script has the ParallelRunStep step runs must process six input files each time the inferencing function is called.
You need to configure the pipeline.
Which configuration setting should you specify in the ParallelRunConfig object for the PrallelRunStep step?
Antwort: A
Begründung:
node_count is the number of nodes in the compute target used for running the ParallelRunStep.
Incorrect Answers:
A: process_count_per_node
Number of processes executed on each node. (optional, default value is number of cores on node.) C: mini_batch_size For FileDataset input, this field is the number of files user script can process in one run() call. For TabularDataset input, this field is the approximate size of data the user script can process in one run() call.
Example values are 1024, 1024KB, 10MB, and 1GB.
D: error_threshold
The number of record failures for TabularDataset and file failures for FileDataset that should be ignored during processing. If the error count goes above this value, then the job will be aborted.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-contrib-pipeline-
steps/azureml.contrib.pipeline.steps.parallelrunconfig?view=azure-ml-py
194. Frage
You are producing a multiple linear regression model in Azure Machine Learning Studio.
Several independent variables are highly correlated.
You need to select appropriate methods for conducting effective feature engineering on all the data.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.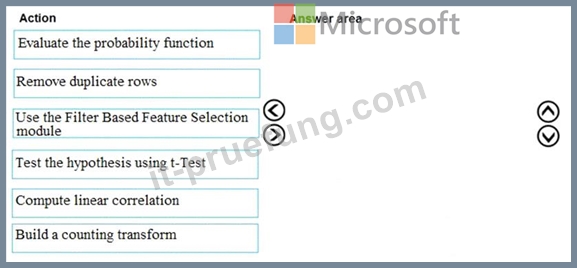
Antwort:
Begründung: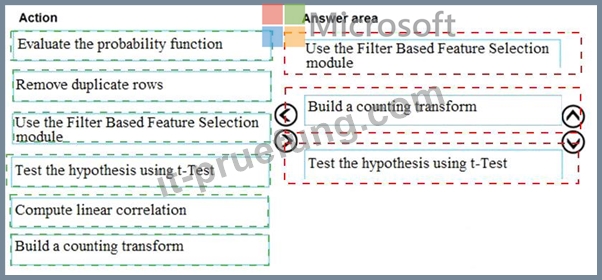
Explanation: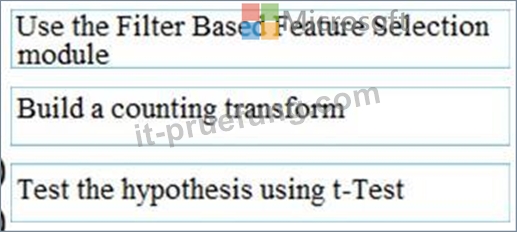
Step 1: Use the Filter Based Feature Selection module
Filter Based Feature Selection identifies the features in a dataset with the greatest predictive power.
The module outputs a dataset that contains the best feature columns, as ranked by predictive power. It also outputs the names of the features and their scores from the selected metric.
Step 2: Build a counting transform
A counting transform creates a transformation that turns count tables into features, so that you can apply the transformation to multiple datasets.
Step 3: Test the hypothesis using t-Test
References:
https://docs.microsoft.com/bs-latn-ba/azure/machine-learning/studio-module-reference/filter-based-feature- selection
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/build-counting-transform
195. Frage
You develop a flow for an Azure Al Foundry project.
You plan to use outputs generated by running the flow to determine the following information:
* the number of tokens used by each large language model (LLM) node of the flow
* the accuracy of the model used by the flow
You need to examine the output that provides the required information.
Which output type should you examine? To answer, move the appropriate output types to the correct evaluations. You may use each output type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.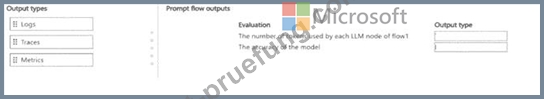
Antwort:
Begründung: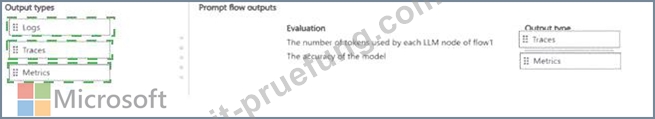
Explanation: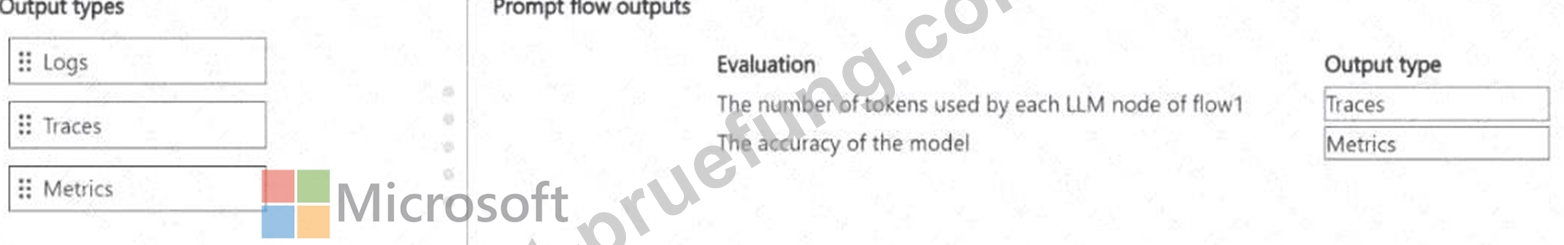
196. Frage
You manage an Azure Machine Learning workspace named workspace1.
You must develop Python SDK v2 code to attach an Azure Synapse Spark pool as a compute target in workspace1. The code must invoke the constructor of the SynapseSparkCompute class.
You need to invoke the constructor.
What should you use?
Antwort: A
Begründung:
To attach a Synapse Compute using Python SDK, first create an instance of azure.ai.ml.MLClient class. This provides convenient functions for interaction with Azure Machine Learning services.
The following code sample uses azure.identity.DefaultAzureCredential for connecting to a workspace in resource group of a specified Azure subscription. In the following code sample, define the SynapseSparkCompute with the parameters:
name - user-defined name of the new attached Synapse Spark pool.
resource_id - resource ID of the Synapse Spark pool created earlier in the Azure Synapse Analytics workspace.
197. Frage
You create an Azure Machine Learning workspace named woricspace1. The workspace contains a Python SDK v2 notebook that uses MLflow to collect model training metrics and artifacts from your local computer.
You must reuse the notebook to run on Azure Machine Learning compute instance in workspace1.
You need to continue to log metrics and artifacts from your data science code.
What should you do?
Antwort: B
198. Frage
......
Wenn Sie It-Pruefung wählen, versprechen wir Ihnen eine 100%-Pass-Garantie zur Microsoft DP-100 Zertifizierungsprüfung. Sonst erstatteten wir Ihnen Ihre an uns geleisteten Zahlung.
DP-100 Deutsch Prüfungsfragen: https://www.it-pruefung.com/DP-100.html
Übrigens, Sie können die vollständige Version der It-Pruefung DP-100 Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1VeQ4yq2SXA3UYbkwPFEgUDXJFOedJjHC