The dream of IT in front of the reality is always tiny. But the dream to pass AI-500 certification exam, with the help of Prep4away, can be absolutely realized. The service of our Prep4away is high-quality, the accuracy of AI-500 Certification Exam training materials is very high, the passing rate of AI-500 exam is as high as 100%. As long as you choose Prep4away, we guarantee that you can pass the AI-500 certification exam!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
| Topic 3: Develop multi-agent solutions in Azure | 30–35% | - Implement agents using Azure AI services
|
| Topic 4: Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
It is quite clear that let the facts speak for themselves is more convincing than any word, therefore, we have prepared free demo in this website for our customers to have a taste of the AI-500 test torrent compiled by our company. You will understand the reason why we are so confident to say that the AI-500 exam torrent compiled by our company is the top-notch AI-500 Exam Torrent for you to prepare for the exam. Just like the old saying goes:" Facts are stronger than arguments." You can choose to download our free demo at any time as you like, you are always welcome to have a try, and we trust that our AI-500 exam materials will never let you down.
NEW QUESTION # 57
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.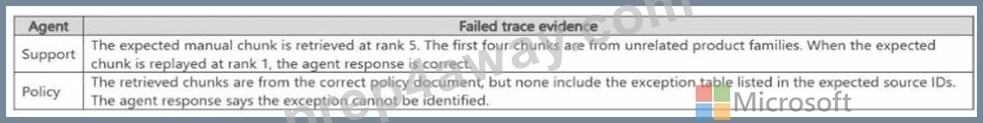
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.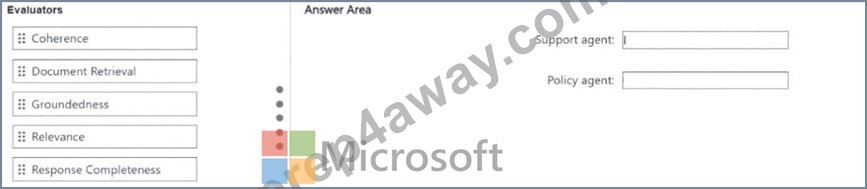
Answer:
Explanation: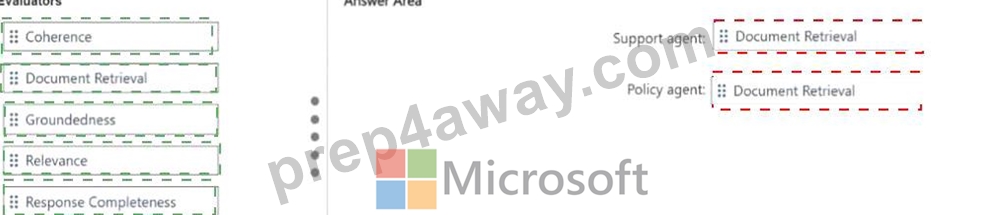
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 58
You are designing an enterprise automation solution that has a web portal for users and the following types of workflows:
* Routine workflows that use prompt-defined agents, approved knowledge stores, and HTTPS tools
* Modernization workflows that use custom Microsoft Agent Framework code packaged as container images with predefined handoffs and task states You need to recommend Azure services that meets the following requirements:
* The routine workflows must run agents in a fully managed environment.
* The user portal must be deployed as a managed platform as a service (PaaS) web app
* The modernization workflows must run agents in serverless containers that support automatic scaling What should you recommend for each requirement? To answer, drag the appropriate services to the correct components. Each service may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.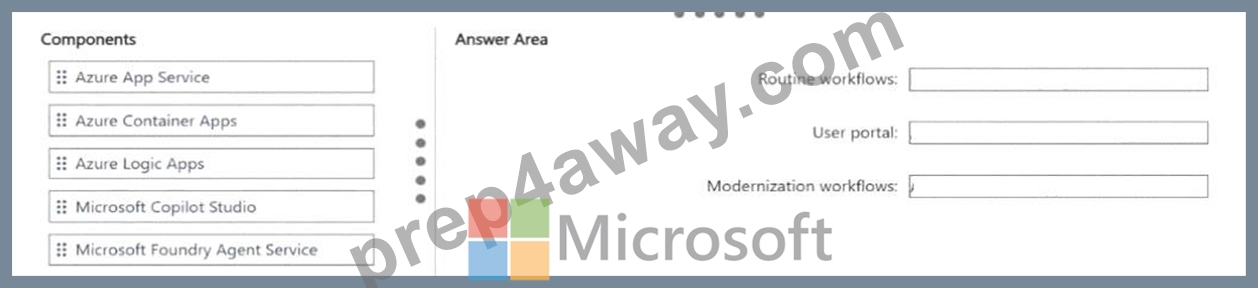
Answer:
Explanation: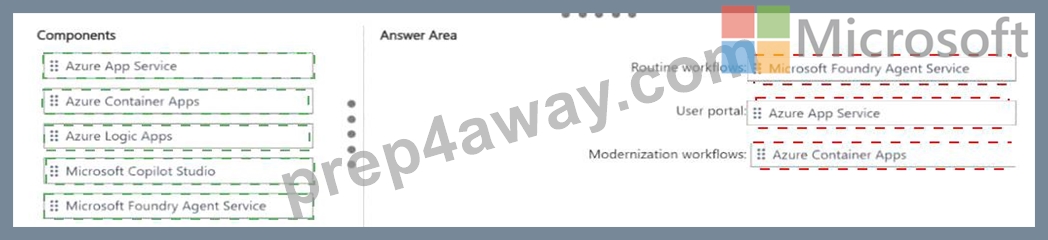
Explanation:
Routine workflows: Microsoft Foundry Agent Service; User portal: Azure App Service; Modernization workflows: Azure Container Apps.
The three workload types map to three different managed Azure services. Prompt-defined agents that use approved knowledge and HTTPS tools fit Microsoft Foundry Agent Service because it provides a managed agent runtime and hosted agent capabilities without requiring the team to operate the underlying orchestration infrastructure. The user portal is a conventional managed web application, making Azure App Service the direct PaaS fit. The modernization workflow is custom Microsoft Agent Framework code packaged as container images and therefore needs a serverless container platform; Azure Container Apps supplies managed container execution and automatic scaling while preserving control of the custom application image.
Logic Apps targets integration workflows rather than arbitrary Agent Framework containers, and Copilot Studio is not the requested general-purpose container runtime. The answer therefore selects the managed service that matches each component ' s execution model. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry Agent Service overview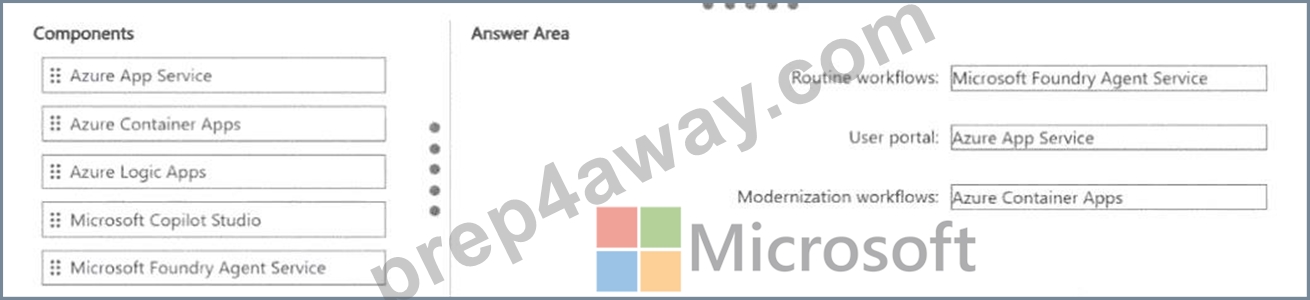
NEW QUESTION # 59
You have a Microsoft Foundry Agent Sen/ice solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and set scope for each memory search tool to
{{Suserld}} Does this meet the goal?
Answer: A
Explanation:
A dedicated memory store for each agent establishes agent-domain isolation. Setting each memory search tool
' s scope to the current user identity establishes the second isolation dimension: users within the same agent domain receive separate logical memory collections. Microsoft Foundry Memory documents `scope` as the partitioning mechanism and specifically supports `{{$userId}}` for automatic per-user isolation. Memory associated with one scope can be deleted without removing memories stored under other scopes, which satisfies the deletion requirement. The source text renders the token imperfectly as `{{Suserld}}`; the current documented syntax is `{{$userId}}`. Interpreting the question as the documented user-scope token, the design satisfies domain isolation, user isolation, and per-user deletion. Therefore A, Yes, is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 60
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.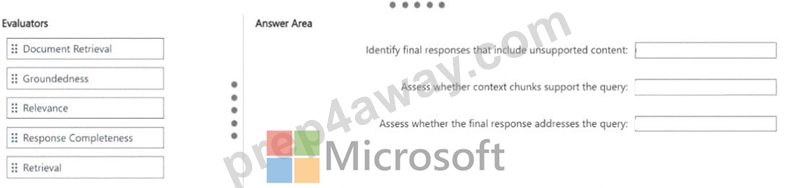
Answer:
Explanation: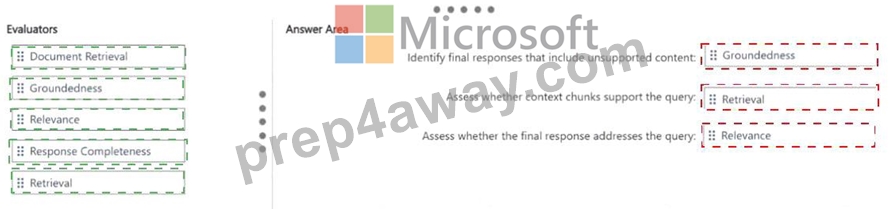
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators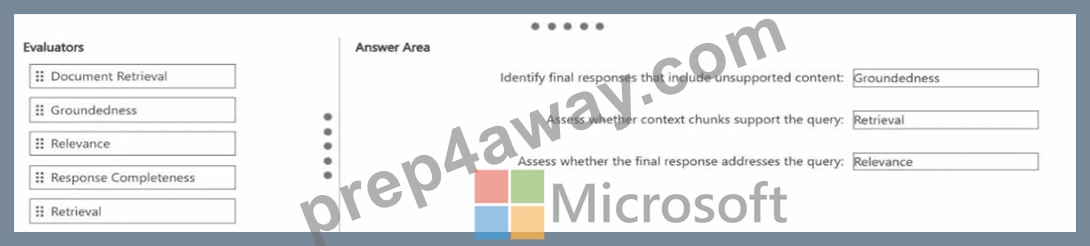
NEW QUESTION # 61
You have a Microsoft Agent Framework solution for customer support that includes the following agents:
* A triage agent
* A refund specialist agent that runs in the same process as the triage agent
* A compliance review agent that is exposed by a partner team as a remote service You need to identify which integration components the triage agent will use to coordinate interactions with the other agents.
What should you identify for each agent? To answer, drag the appropriate components to the correct agents Each component may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.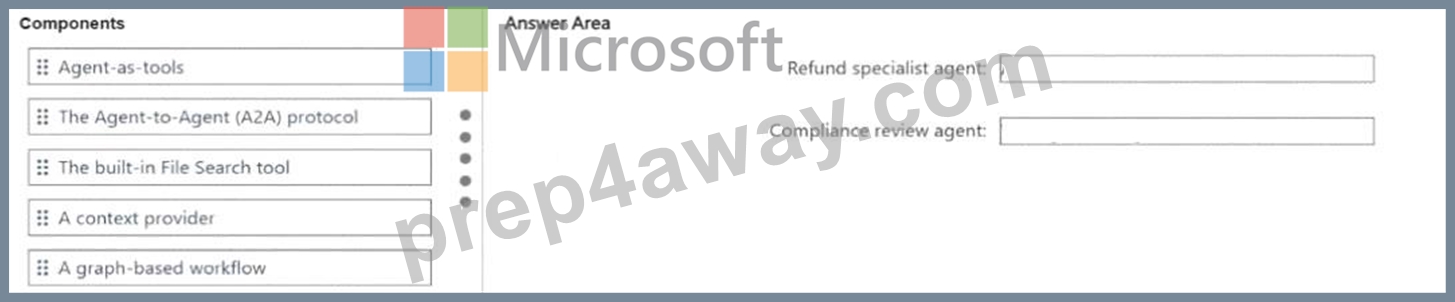
Answer:
Explanation: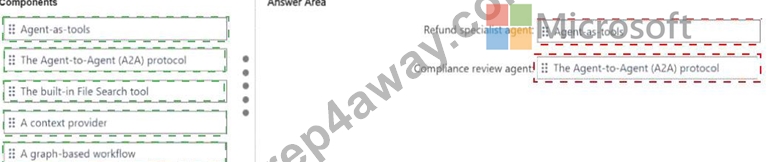
Explanation:
Refund specialist agent: Agent-as-tools; Compliance review agent: Agent-to-Agent (A2A) protocol.
The refund specialist runs in the same process as the triage agent, so exposing it as an agent-as-tool is the lightweight composition pattern. The outer triage agent can decide when to invoke the specialist while retaining overall task ownership. The compliance reviewer is different: it is a remote service owned by a partner team. Agent-to-Agent (A2A) is the interoperable protocol intended for independently hosted agents that may use a different runtime or framework. It supports capability discovery and remote task interaction without coupling the caller to the partner ' s implementation. Using A2A for the in-process specialist would add unnecessary network/protocol complexity, while treating the partner agent as an in-process tool would not match the deployment boundary. The two selections therefore reflect Microsoft ' s distinction between local agent composition and remote agent interoperability. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - agents as tools and A2A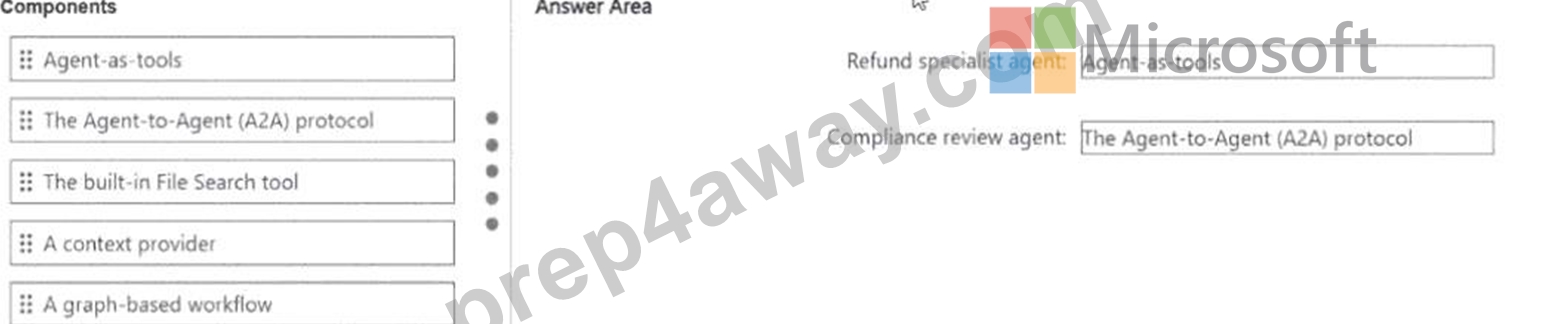
NEW QUESTION # 62
......
Those who are ambitious to obtain Designing and Implementing Multi-Agent AI Solutions certification mainly include office workers; they expect to reach a higher position and get handsome salary, moreover, a prosperous future. Through our AI-500 test torrent, we expect to design such an efficient study plan to help you build a high efficient learning attitude for your further development. Our study materials are cater every candidate no matter you are a student or office worker, a green hand or a staff member of many years' experience, AI-500 Certification Training is absolutely good choices for you. Therefore, you have no need to worry about whether you can pass the exam, because we guarantee you to succeed with our technology strength.
Valid AI-500 Test Sample: https://www.prep4away.com/Microsoft-certification/braindumps.AI-500.ete.file.html