BONUS!!! Download part of Test4Sure Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU
In today's society, everyone wants to find a good job and gain a higher social status. As we all know, the internationally recognized Databricks-Certified-Professional-Data-Engineer certification means that you have a good grasp of knowledge of certain areas and it can demonstrate your ability. This is a fair principle. But obtaining this Databricks-Certified-Professional-Data-Engineer certificate is not an easy task, especially for those who are busy every day. We do not charge extra service fees, but the service quality is high. Your satisfaction is the greatest affirmation for us and we sincerely serve you. Our Databricks-Certified-Professional-Data-Engineer Exam Guide deliver the most important information in a simple, easy-to-understand language that you can learn efficiently learn with high quality. Whether you are a student or an in-service person, our Databricks-Certified-Professional-Data-Engineer exam torrent can adapt to your needs.
| Section | Weight | Objectives |
|---|---|---|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Data Ingestion | 15-20% | - Streaming ingestion
|
| Delta Lake | 20-25% | - Delta Lake operations
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
>> Latest Databricks-Certified-Professional-Data-Engineer Mock Test <<
With Databricks-Certified-Professional-Data-Engineer guide torrent, you can easily pass professional qualification exams of various industries, even if you are not a college graduate, and you have never come into contact with this professional knowledge. With Databricks-Certified-Professional-Data-Engineer exam torrent, you can also quickly get started, easily grasp the key points of the exam, and gain access to well-known companies. Databricks-Certified-Professional-Data-Engineer Guide Torrent helps you to use the least time to get the maximum improvement. With our Databricks-Certified-Professional-Data-Engineer certification training, you pay for money, but you can get time and knowledge that money cannot buy.
NEW QUESTION # 35
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: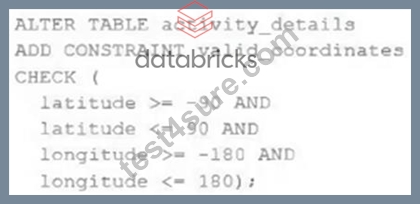
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: E
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 36
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: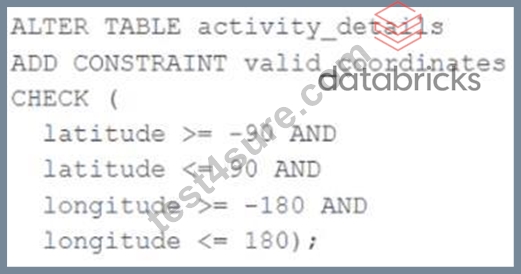
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
Answer: B
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints : https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions : https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 37
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats.
After converting a subset of data to Delta Lake , they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join , whereas queries on legacy formats used Sort Merge Joins . The queries reading Delta Lake data also scanned less data.
Which reason could be attributed to the difference in query performance?
Answer: D
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage , data skipping
, and file pruning . According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters , a process called data skipping and file pruning . Additionally, Delta uses a vectorized Parquet reader , which reduces I/O and CPU overhead.
Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 38
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id .
What should the data engineer do to ensure events are sequenced correctly?
Answer: A
Explanation:
When handling CDC data , sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built- in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration. Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
* Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
* Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
* Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
* Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support , making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
Reference: Databricks Lakeflow Declarative Pipelines - AUTO CDC APIs and Sequencing with SEQUENCE BY
NEW QUESTION # 39
Which of the following python statement can be used to replace the schema name and table name in the query statement?
Answer: D
Explanation:
Explanation
Answer is
table_name = "sales"
query = f"select * from {schema_name}.{table_name}"
f strings can be used to format a string. f" This is string {python variable}"
https://realpython.com/python-f-strings/
NEW QUESTION # 40
......
As we all know, in the highly competitive world, we have no choice but improve our software power, such as international Databricks-Certified-Professional-Data-Engineer certification, working experience, educational background and so forth. Therefore, it is of great significance to have a Databricks-Certified-Professional-Data-Engineer certificate in hand to highlight your resume, thus helping you achieve success in your workplace. So with our Databricks-Certified-Professional-Data-Engineer Preparation materials, you are able to pass the exam more easily in the most efficient and productive way and learn how to study with dedication and enthusiasm. There are many advantages of our Databricks-Certified-Professional-Data-Engineer guide torrent.
Databricks-Certified-Professional-Data-Engineer Reliable Mock Test: https://www.test4sure.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-vce.html
P.S. Free & New Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by Test4Sure: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU