그리고 KoreaDumps Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1h5TDtVHNU4N3BaSp8DLBrzLE8XdcJkXM
KoreaDumps의 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 선택하여Databricks인증 Databricks-Certified-Professional-Data-Engineer시험공부를 하는건 제일 현명한 선택입니다. 시험에서 떨어지면 덤프비용 전액을 환불처리해드리고Databricks인증 Databricks-Certified-Professional-Data-Engineer시험이 바뀌면 덤프도 업데이트하여 고객님께 최신버전을 발송해드립니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프뿐만아니라 IT인증시험에 관한 모든 덤프를 제공해드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Topic 2: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs |
| Topic 3: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 4: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Topic 5: Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
| Topic 6: Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Topic 7: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Topic 8: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Compliance standards implementation - Access control and permissions |
| Topic 9: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 10: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
>> Databricks-Certified-Professional-Data-Engineer퍼펙트 덤프 최신버전 <<
KoreaDumps의 Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프는 거의 모든 실제시험문제 범위를 커버하고 있습니다.Databricks인증 Databricks-Certified-Professional-Data-Engineer시험덤프를 구매하여 덤프문제로 시험에서 불합격성적표를 받을시KoreaDumps에서는 덤프비용 전액 환불을 약속드립니다.
질문 # 49
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB.
How should the data engineer meet this requirement?
정답:D
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation describes Liquid Clustering as the recommended data layout optimization for evolving workloads. Unlike traditional partitioning or Z-ordering, Liquid Clustering dynamically maintains data organization without rewriting existing files when clustering keys change. It handles data skew automatically and supports flexible re-clustering based on query patterns. Partitioning and Z-ordering require full data rewrites whenever key structures change, making them expensive for tables with frequently evolving access patterns. For tables under a few terabytes, Liquid Clustering offers the best balance between scalability, adaptability, and maintenance efficiency. Thus, option C aligns with Databricks' best practice for modern adaptive layout optimization.
질문 # 50
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
정답:A
설명:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column. When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Data skipping" section.
질문 # 51
Which of the following features of data lakehouse can help you meet the needs of both workloads?
정답:D
설명:
Explanation
The answer is A data lakehouse stores unstructured data and is ACID-compliant,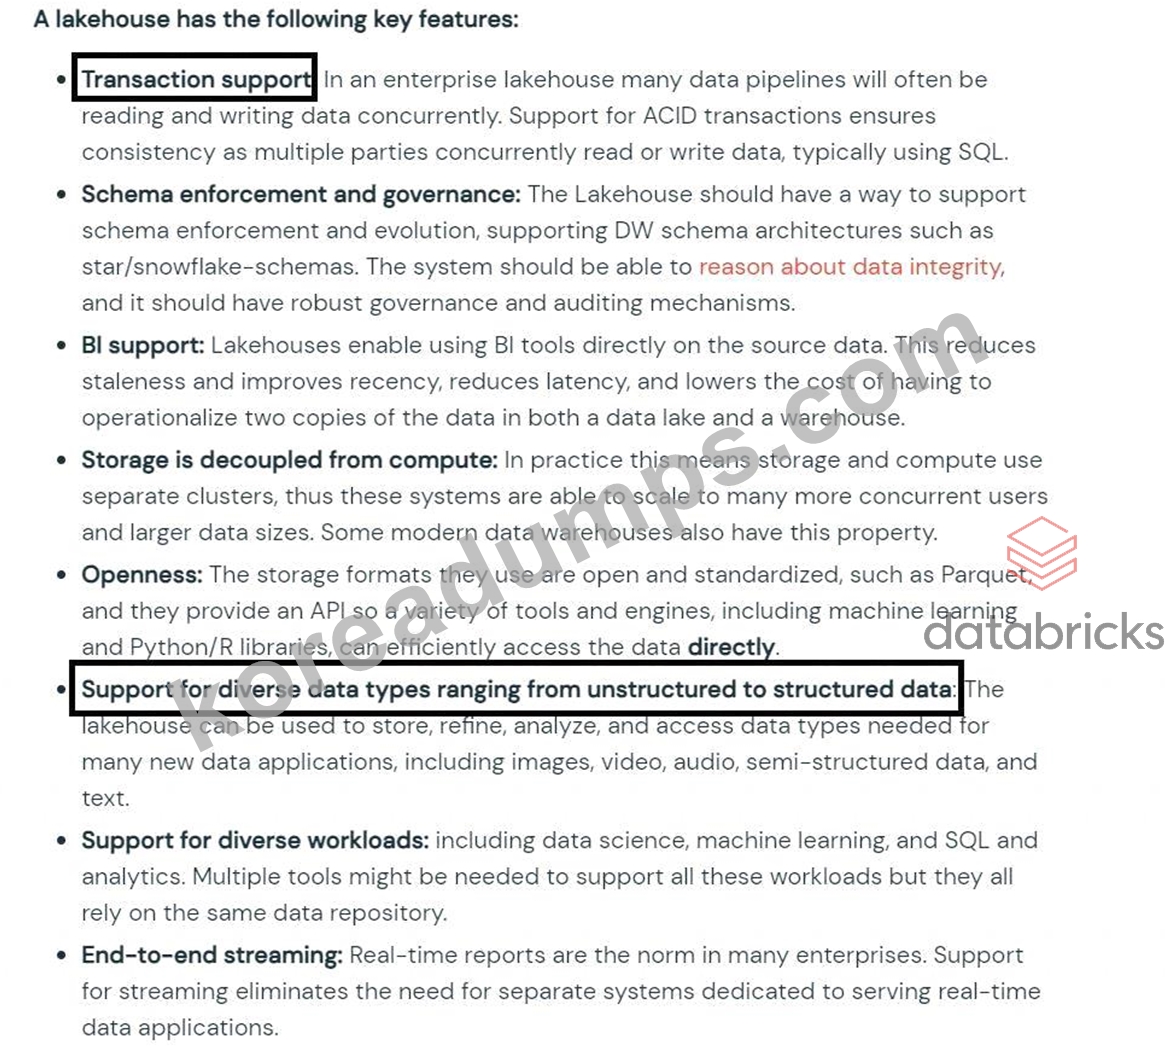
질문 # 52
If E1 and E2 are two events, how do you represent the conditional probability given that E2 occurs given that
E1 has occurred?
정답:D
질문 # 53
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:
For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:
Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
정답:B
질문 # 54
......
현재 많은 IT인사들이 같은 생각하고 잇습니다. 그것은 바로Databricks Databricks-Certified-Professional-Data-Engineer인증시험자격증 취득으로 하여 IT업계의 아주 중요한 한걸음이라고 말입니다.그만큼Databricks Databricks-Certified-Professional-Data-Engineer인증시험의 인기는 말 그대로 하늘을 찌르고 잇습니다,
Databricks-Certified-Professional-Data-Engineer최신버전 인기 덤프자료: https://www.koreadumps.com/Databricks-Certified-Professional-Data-Engineer_exam-braindumps.html
2026 KoreaDumps 최신 Databricks-Certified-Professional-Data-Engineer PDF 버전 시험 문제집과 Databricks-Certified-Professional-Data-Engineer 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1h5TDtVHNU4N3BaSp8DLBrzLE8XdcJkXM