Reliable Databricks Databricks-Certified-Professional-Data-Engineer Latest Test Pdf Are Leading Materials & Free PDF Databricks-Certified-Professional-Data-Engineer Valid Test Blueprint

BONUS!!! Download part of Prep4King Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=11qEFOFLRiFDWv659KBg_btolOzLObJSK
Everyone has the right to pursue happiness and wealth. You can rely on the Databricks-Certified-Professional-Data-Engineer certificate to support yourself. If you do not own one or two kinds of skills, it is difficult for you to make ends meet in the modern society. After all, you can rely on no one but yourself. At present, our Databricks-Certified-Professional-Data-Engineerstudy materials can give you a ray of hope. You can get the Databricks-Certified-Professional-Data-Engineer certification easily with our Databricks-Certified-Professional-Data-Engineer learning questions and have a better future.
| Section | Weight | Objectives |
|---|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
- Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Differences between data lake, data warehouse, and lakehouse
- 3. Bronze, silver, gold data layers
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. Integration with external systems
- 2. DBR autoloader
- 3. Spark APIs for ingestion
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. ACID transactions
- 2. Time travel and data versioning
- 3. Optimize and Z-order
- Delta Lake operations
- 1. Merge, update, delete operations
- 2. Schema evolution and enforcement
- 3. Delta Live Tables
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
>> Databricks-Certified-Professional-Data-Engineer Latest Test Pdf <<
Databricks-Certified-Professional-Data-Engineer Valid Test Blueprint & Valid Databricks-Certified-Professional-Data-Engineer Exam Notes
Compared with the book version, our Databricks-Certified-Professional-Data-Engineer exam dumps is famous for instant access to download, and if you receive your downloading link within ten minutes, and therefore you don’t need to spend extra time on waiting the arriving of the exam materials. Furthermore, Databricks-Certified-Professional-Data-Engineer training materials are edited and verified by professional experts, therefore the quality can be guaranteed. We offer you free update for one year for Databricks-Certified-Professional-Data-Engineer Study Materials, and the update version will be sent to your email automatically. If you choose us, you just choose to pass your exam just one time!
Databricks Certified Professional Data Engineer Exam Sample Questions (Q33-Q38):
NEW QUESTION # 33
A Delta Lake table was created with the below query:
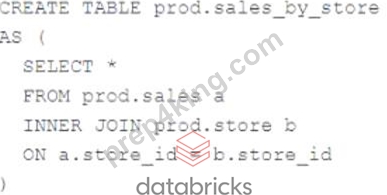
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
- A. Nothing will occur until a COMMIT command is executed.
- B. An error will occur because Delta Lake prevents the deletion of production data.
- C. Data will be marked as deleted but still recoverable with Time Travel.
- D. The table will be removed from the catalog and the data will be deleted.
- E. The table will be removed from the catalog but the data will remain in storage.
Answer: D
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. References:
* https://docs.databricks.com/delta/quick-start.html#drop-a-table
* https://docs.databricks.com/delta/delta-batch.html#drop-table
NEW QUESTION # 34
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
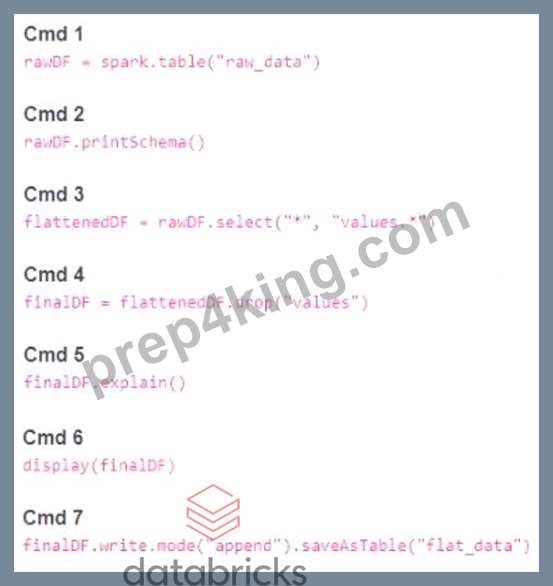
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 4
- B. Cmd 2
- C. Cmd 6
- D. Cmd 5
- E. Cmd 3
Answer: C
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 35
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production dat a. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
- A. Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.
- B. All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.
- C. In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.
- D. Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.
Answer: C
Explanation:
The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.
Reference:
Databricks best practices for securing data: https://docs.databricks.com/security/index.html
NEW QUESTION # 36
The business reporting team requires that data for their dashboards be updated every hour. The total processing time for the pipeline that extracts, transforms, and loads the data for their pipeline runs in 10 minutes. Assuming normal operating conditions, which configuration will meet their service-level agreement requirements with the lowest cost?
- A. Configure a job that executes every time new data lands in a given directory.
- B. Schedule a Structured Streaming job with a trigger interval of 60 minutes.
- C. Schedule a job to execute the pipeline once an hour on a new job cluster.
- D. Schedule a job to execute the pipeline once an hour on a dedicated interactive cluster.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "Job clusters are created for a job run and terminate when the job completes." Exact extract: "All-purpose (interactive) clusters are intended for interactive development and collaboration." An hourly batch that completes in ~10 minutes is best run on ephemeral job clusters so compute exists only during execution and auto-terminates afterward, minimizing cost while meeting the hourly SLA. Interactive clusters persist (incurring idle cost). Structured Streaming for an hourly refresh adds continuous compute cost with no benefit here. Event-driven triggers are unnecessary for a simple hourly SLA.
Reference:
NEW QUESTION # 37
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.
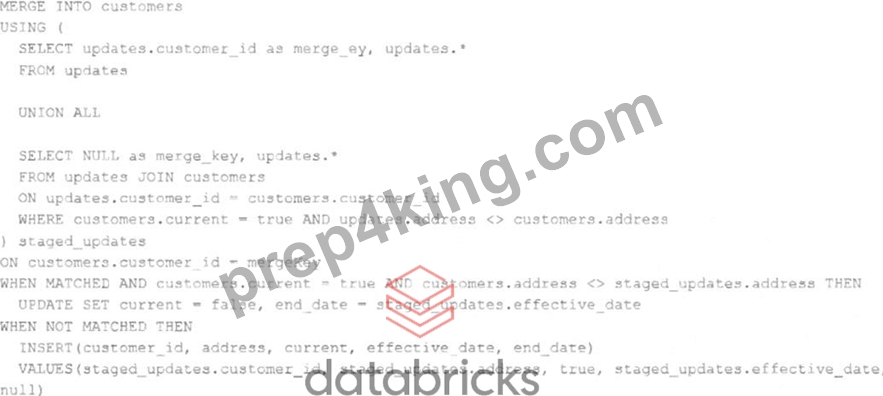
Which statement describes this implementation?
- A. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- B. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
Answer: C
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case,the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 38
......
Our product boosts many advantages and it is worthy for you to buy it. You can have a free download and tryout of our Databricks-Certified-Professional-Data-Engineer exam torrents before purchasing. After you purchase our product you can download our Databricks-Certified-Professional-Data-Engineer study materials immediately. We will send our product by mails in 5-10 minutes. We provide free update and the discounts for the old client. If you have any doubts or questions you can contact us by mails or the online customer service personnel and we will solve your problem as quickly as we can. Our Databricks-Certified-Professional-Data-Engineer Exam Materials boost high passing rate and if you are unfortunate to fail in exam we can refund you in full at one time immediately. The learning costs you little time and energy and you can commit yourself mainly to your jobs or other important things.
Databricks-Certified-Professional-Data-Engineer Valid Test Blueprint: https://www.prep4king.com/Databricks-Certified-Professional-Data-Engineer-exam-prep-material.html
- Free Databricks-Certified-Professional-Data-Engineer Practice 💥 Free Databricks-Certified-Professional-Data-Engineer Practice 🍵 Databricks-Certified-Professional-Data-Engineer Useful Dumps 🐭 Download { Databricks-Certified-Professional-Data-Engineer } for free by simply entering ➥ www.examdiscuss.com 🡄 website 🐑Databricks-Certified-Professional-Data-Engineer Test King
- Test Databricks-Certified-Professional-Data-Engineer Guide 🧿 Reliable Databricks-Certified-Professional-Data-Engineer Cram Materials 🐥 Databricks-Certified-Professional-Data-Engineer Valid Dumps Questions 📗 Search on ⏩ www.pdfvce.com ⏪ for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to obtain exam materials for free download ⭕Practice Databricks-Certified-Professional-Data-Engineer Engine
- Pass Guaranteed 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Fantastic Latest Test Pdf 🕐 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ on ⇛ www.prepawaypdf.com ⇚ immediately to obtain a free download 😘Free Databricks-Certified-Professional-Data-Engineer Practice
- Databricks-Certified-Professional-Data-Engineer Pass4sure Dumps Pdf 🦅 Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 😺 Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 🕺 The page for free download of ▶ Databricks-Certified-Professional-Data-Engineer ◀ on ➤ www.pdfvce.com ⮘ will open immediately 🚥Databricks-Certified-Professional-Data-Engineer Useful Dumps
- Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 🕜 Databricks-Certified-Professional-Data-Engineer Valid Dumps Questions 🙈 Databricks-Certified-Professional-Data-Engineer Latest Exam Registration 🏅 Search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ on ➡ www.exam4labs.com ️⬅️ immediately to obtain a free download 🌀Databricks-Certified-Professional-Data-Engineer Useful Dumps
- Free PDF 2026 Efficient Databricks Databricks-Certified-Professional-Data-Engineer Latest Test Pdf 🚼 Search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ on ➠ www.pdfvce.com 🠰 immediately to obtain a free download ⏹Databricks-Certified-Professional-Data-Engineer Useful Dumps
- Databricks Databricks-Certified-Professional-Data-Engineer PDF Dumps - Study Whenever You Want 👎 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on ➥ www.easy4engine.com 🡄 immediately to obtain a free download 👒Databricks-Certified-Professional-Data-Engineer Useful Dumps
- Free PDF 2026 Reliable Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Latest Test Pdf 🚵 Download 【 Databricks-Certified-Professional-Data-Engineer 】 for free by simply searching on 【 www.pdfvce.com 】 🌍Free Databricks-Certified-Professional-Data-Engineer Practice
- Actual Databricks-Certified-Professional-Data-Engineer Test Answers 🎐 Latest Databricks-Certified-Professional-Data-Engineer Test Questions 🐑 Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Sheet 🔊 Go to website ➽ www.vce4dumps.com 🢪 open and search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ to download for free ⏪Databricks-Certified-Professional-Data-Engineer Useful Dumps
- Databricks-Certified-Professional-Data-Engineer Valid Dumps Questions 📭 Useful Databricks-Certified-Professional-Data-Engineer Dumps 📜 Databricks-Certified-Professional-Data-Engineer Pass4sure Dumps Pdf 🦜 「 www.pdfvce.com 」 is best website to obtain ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free download 🏕Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Sheet
- Pass Guaranteed 2026 Databricks-Certified-Professional-Data-Engineer: Newest Databricks Certified Professional Data Engineer Exam Latest Test Pdf 👪 Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on ▶ www.prepawayexam.com ◀ immediately to obtain a free download ⏪Databricks-Certified-Professional-Data-Engineer Valid Dumps Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myspace.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=11qEFOFLRiFDWv659KBg_btolOzLObJSK