順便提一下,可以從雲存儲中下載KaoGuTi DAA-C01考試題庫的完整版:https://drive.google.com/open?id=18-bl4Ux5jRZiq9q87iE9HHycOLEzmzKx
KaoGuTi可以為你提供捷徑,給你節約好多時間和精力換。KaoGuTi會為你的Snowflake DAA-C01認證考試提供很好的培訓工具,有效的幫助你通過Snowflake DAA-C01認證考試。如果你在其他網站也看到了可以提供相關資料,你可以繼續往下看,你會發現其實資料主要來源於KaoGuTi,而且KaoGuTi提供的資料最全面,而且更新得最快。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and Load Data | 15–20% | - File formats: CSV, JSON, Parquet, Avro - External tables and data validation - Data ingestion methods: COPY INTO, stages, Snowpipe |
| Topic 2: Prepare and Present Data | 10–15% | - Snowsight dashboards and sharing results - Data visualization and reporting - Align outputs with business requirements |
| Topic 3: Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Topic 4: Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Topic 5: Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Anomaly detection and root cause analysis - Statistical summarization and trend analysis |
| Topic 6: Perform Simple Data Transformations for Analysis | 15–20% | - Views, materialized views, CTEs - Handling NULLs and structuring datasets - Data cleansing, standardization, type conversion |
| Topic 7: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Query optimization and troubleshooting - Complex joins, subqueries, window functions |
我們KaoGuTi Snowflake的DAA-C01考題按照相同的教學大綱,其次是實際的DAA-C01認證考試,我們也在不斷升級我們的培訓資料,使你在第一時間得到最好和最新的資訊。當你購買我們DAA-C01的考試培訓材料,你所得到的培訓資料有長達一年的免費更新期,你可以隨時延長更新訂閱時間,讓你有更久的時間來準備考試。
問題 #25
You are tasked with aggregating website clickstream data in Snowflake to identify the most popular product categories per region on a daily basis. The clickstream data is stored in a table named 'clickstream eventS with columns: 'event_time', 'user id', 'product id', 'region', and 'category'. You need to create a solution that efficiently identifies the top 3 categories for each region on each day. Which approach offers the best performance and scalability considering the dataset size is expected to grow significantly?
答案:A
解題說明:
Option D is the most efficient and scalable because it leverages Snowflake's built-in window functions (DENSE_RANK) for efficient ranking within partitions (region and day). Window functions are optimized for parallel processing. DENSE RANK handles ties appropriately (assigning the same rank to tied categories). Options A is similar but DENSE_RANK is better for the case of ties. Option B would be slow and not scalable due to the iterative nature of stored procedures. Option C is inefficient due to the creation of temporary tables and JOIN operations. Option E offloads the crucial filtering to external tools, impacting performance.
問題 #26
When implementing data processing solutions, how does aggregating and enriching data contribute to the overall data analysis process?
答案:C
解題說明:
Aggregating and enriching data enhances data granularity by providing more detailed and comprehensive insights into datasets, enabling better analysis and correlation of information.
問題 #27
In Snowflake, how does the implementation of primary keys for tables contribute to data integrity?
答案:C
解題說明:
Primary keys enforce uniqueness in table rows, ensuring data integrity by preventing duplicate entries within a table.
問題 #28
You have a Snowflake table 'CUSTOMER ORDERS with columns 'CUSTOMER ID', 'ORDER DATE, and 'ORDER AMOUNT. You need to calculate the cumulative sum of 'ORDER AMOUNT' for each customer, ordered by 'ORDER DATE. However, due to potential late-arriving data, you also need to implement a windowing function that resets the cumulative sum if there's a gap of more than 30 days between consecutive orders for a customer. Which SQL query best accomplishes this?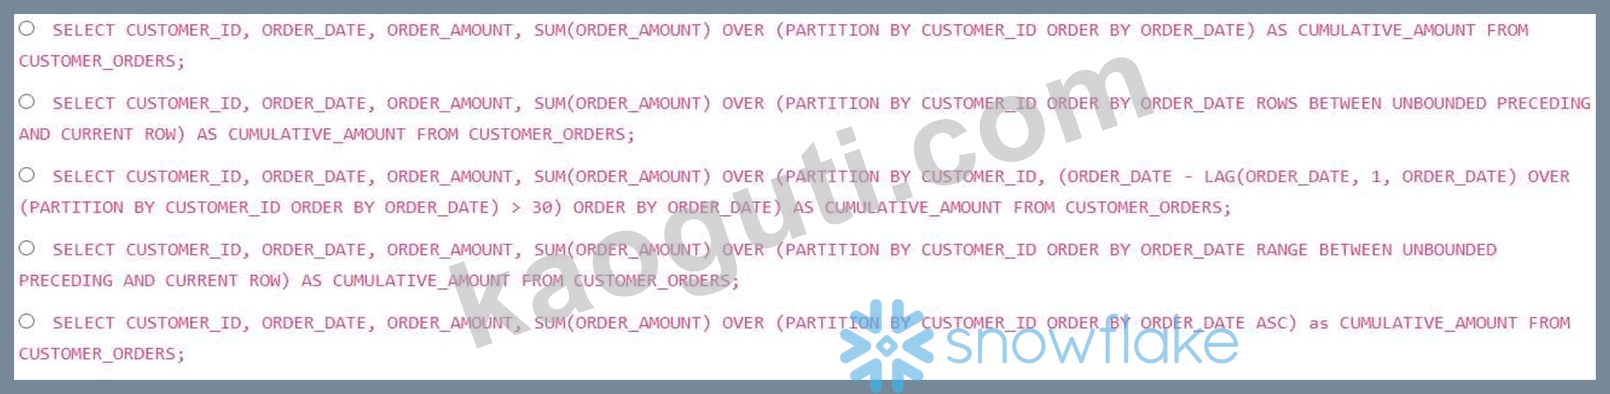
答案:A
解題說明:
Option C correctly uses a conditional partitioning approach. UG(ORDER DATE, 1, ORDER DATE) OVER (PARTITION BY CUSTOMER_ID ORDER BY ORDER_DATE)' calculates the previous order date for each customer. (ORDER_DATE - 1, ORDER DATE) OVER (PARTITION BY CUSTOMER ID ORDER BY ORDER DATE) > 30)' creates a boolean expression that is true when the difference between consecutive order dates exceeds 30 days. This boolean expression is then used as a secondary partition key, effectively restarting the cumulative sum whenever a gap of more than 30 days occurs. The primary partition is still 'CUSTOMER ID' , ensuring sums are calculated within each customer's order history. The ordering of 'ORDER_DATE is essential for the cumulative sum to be calculated chronologically.
問題 #29
How do stored procedures contribute to data analysis efficiency in SQL compared to UDFs?
答案:A
解題說明:
Stored procedures enhance efficiency by enabling the execution of repetitive tasks.
問題 #30
......
KaoGuTi是一個對Snowflake DAA-C01 認證考試提供針對性培訓的網站。KaoGuTi也是一個不僅能使你的專業知識得到提升,而且能使你一次性通過Snowflake DAA-C01 認證考試的網站。KaoGuTi提供的培訓資料是由很多IT資深專家不斷利用自己的經驗和知識研究出來的,品質很好,準確性很高。一旦你選擇了我們KaoGuTi,不僅能夠幫你通過Snowflake DAA-C01 認證考試和鞏固自己的IT專業知識,還可以享用一年的免費售後更新服務。
DAA-C01熱門考題: https://www.kaoguti.com/DAA-C01_exam-pdf.html
P.S. KaoGuTi在Google Drive上分享了免費的2026 Snowflake DAA-C01考試題庫:https://drive.google.com/open?id=18-bl4Ux5jRZiq9q87iE9HHycOLEzmzKx