P.S. Free & New NCA-GENM dumps are available on Google Drive shared by PassTorrent: https://drive.google.com/open?id=1aAKHRm64LHsnPRt6tCqzZE9KKOFNb8HU
Obtaining valid training materials will accelerate the way of passing NVIDIA NCA-GENM actual test in your first attempt. It will just need to take one or two days to practice NVIDIA NCA-GENM Test Questions and remember answers. You will free access to our test engine for review after payment.
| Section | Objectives |
|---|---|
| Topic 1: Core AI and Machine Learning Fundamentals | - Machine learning basics
|
| Topic 2: Multimodal AI Systems | - Multimodal model design - Cross-modal learning
|
| Topic 3: NVIDIA AI Ecosystem | - NVIDIA tools and frameworks
|
| Topic 4: Responsible and Trustworthy AI | - Ethical AI principles - Bias and safety considerations |
| Topic 5: Generative AI Concepts | - Generative models
|
>> NVIDIA NCA-GENM Test Registration <<
New developments in the tech sector always bring new job opportunities. These new jobs have to be filled with the NVIDIA Generative AI Multimodal (NCA-GENM) certification holders. So to fill the space, you need to pass the NVIDIA Generative AI Multimodal (NCA-GENM) exam. Earning the NVIDIA Generative AI Multimodal (NCA-GENM) certification helps you clear the obstacles you face while working in the NVIDIA field. To get prepared for the NVIDIA Generative AI Multimodal (NCA-GENM) certification exam, applicants face a lot of trouble if the study material is not updated.
NEW QUESTION # 15
Which of the following best describes the role of machine learning in handling multimodal data?
Answer: A
Explanation:
Machine learning's role in multimodal contexts is to build models capable of jointly learning from, aligning, and interpreting heterogeneous data types - text, images, audio, video, time series, and beyond - extracting patterns and relationships that span modality boundaries rather than treating each stream in isolation. This is the general framing that unifies the more specific concepts tested elsewhere in this domain (fusion strategies, shared embedding spaces, cross-modal attention): all of them are mechanisms in service of this broader goal of learning from diverse data types jointly.
Option A incorrectly narrows the scope to text alone, contradicting the entire premise of multimodal learning.
Option B is not a defining characteristic - multimodal models often require *more*, not less, data to learn reliable cross-modal correspondences, though they can improve sample efficiency for a given task relative to a comparably-performing unimodal model by exploiting complementary signal across modalities; this is a possible benefit, not the defining role. Option C overstates ML's function; human oversight, labeling, validation, and bias auditing remain integral to responsible multimodal system development, particularly under Trustworthy AI principles - ML augments rather than eliminates human involvement in the broader data-analysis workflow.
Reference: Multimodal Data domain - foundational definition of multimodal machine learning.
NEW QUESTION # 16
Consider the following PyTorch code snippet used for training a Generative A1 model:
Answer: D,E
Explanation: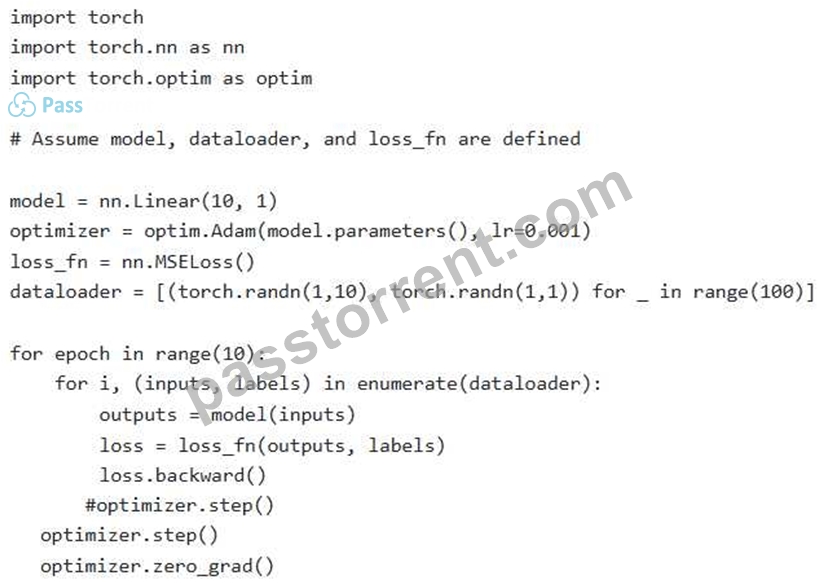
The code has two critical issues. First, 'optimizer.step()' is called only once per epoch after accumulating gradients from all batches. This is incorrect, as parameters aren't updated batch-wise. Second, is also called only once per epoch, meaning gradients from all batches accumulate. This will likely lead to a CUDAOOM error, especially for larger models.
NEW QUESTION # 17
You're training a multimodal model for image and text retrieval. Given an image, the model should retrieve the most relevant text description from a database, and vice-vers a. You're using a dual-encoder architecture, where one encoder processes images and the other processes text, projecting them into a shared embedding space. What is the most effective way to train the model to ensure that semantically similar images and texts have close embeddings, while dissimilar ones have distant embeddings?
Answer: B
Explanation:
Contrastive loss functions are specifically designed for learning embeddings where similarity is defined by distance. They directly encourage similar items to be close and dissimilar items to be far apart. Independent training doesn't enforce the multimodal relationship. Reconstruction loss focuses on regenerating the input, not similarity. Adversarial training aims for indistinguishability, not meaningful embeddings. L1 Loss is a basic distance metric but less effective than contrastive losses for learning semantic similarity
NEW QUESTION # 18
You are developing a multimodal model that combines text and tabular data for predicting customer churn. The text data consists of customer reviews, and the tabular data includes demographics and transaction history. You've preprocessed both datasets. Which of the following approaches would be the MOST effective for integrating these modalities?
Answer: B,E
Explanation:
Options C and D provides the most effective integration. Using a Transformer-based model for text allows it to capture complex relationships and dependencies in the text. A separate neural network handles tabular data effectively. Fusing the embeddings provides a unified representation. Option D is also valid because it allowst he model to incorporate the text and tabular data together as a single feature vector. Raw concatenation (A) is unlikely to work well. Averaging predictions (B) might not capture interactions between modalities.
NEW QUESTION # 19
You are developing a GenAI-Multimodal system that uses data from various sources. What is one potential issue you need to consider in relation to bias in data?
Answer: D
Explanation:
Representativeness bias occurs when a training dataset systematically over- or under-samples subpopulations relative to the population the deployed system will actually encounter - for example, a facial recognition dataset skewed toward lighter-skinned faces, or a multimodal medical dataset drawn predominantly from one demographic group. Because models learn statistical patterns from their training distribution, an unrepresentative dataset produces a model whose accuracy, calibration, and fairness properties degrade for underrepresented groups, even when aggregate accuracy metrics look acceptable.
This is precisely why aggregate accuracy is an insufficient safeguard: option B's framing - that bias doesn't matter "as long as predictions are accurate" - conflates overall accuracy with subgroup accuracy, and a model can post strong aggregate numbers while systematically failing specific populations. Option D is factually false; AI systems have no inherent neutrality - they inherit and can amplify whatever patterns (including societal biases) exist in their training data and objective function. Option C is also incorrect:
mitigating representativeness bias is significantly cheaper and more effective when addressed at the data- collection and curation stage - through stratified sampling, bias audits, and diverse data sourcing - than after deployment, when it becomes a retraining and remediation problem, and by then real-world harm may have already occurred.
Reference: Trustworthy AI domain - data representativeness, fairness, bias identification and mitigation.
NEW QUESTION # 20
......
We have professional IT workers to design the NVIDIA real dumps and they check the update of dump pdf everyday to ensure the NCA-GENM dumps latest to help people pass the exam with high score. So you can trust us about the valid and accuracy of NCA-GENM Exam Dumps. Our braindumps cover almost questions of the actual test.
NCA-GENM Online Version: https://www.passtorrent.com/NCA-GENM-latest-torrent.html
BONUS!!! Download part of PassTorrent NCA-GENM dumps for free: https://drive.google.com/open?id=1aAKHRm64LHsnPRt6tCqzZE9KKOFNb8HU