順便提一下,可以從雲存儲中下載PDFExamDumps MLA-C01考試題庫的完整版:https://drive.google.com/open?id=1NELp-SLUATWqs9pTu9yBN0lgKE6DAk83
什麼是PDFExamDumps Amazon的MLA-C01考試認證培訓資料?網上有很多網站提供PDFExamDumps Amazon的MLA-C01考試培訓資源,我們PDFExamDumps為你提供最實際的資料,我們PDFExamDumps專業的人才隊伍,認證專家,技術人員,以及全面的語言大師總是在研究最新的Amazon的MLA-C01考試,因此,真正相通過Amazon的MLA-C01考試認證,就請登錄PDFExamDumps網站,它會讓你靠近你成功的曙光,一步一步進入你的夢想天堂。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deployment and Orchestration of ML Workflows | 22% | - Choose deployment infrastructure and pattern
|
| Topic 2: ML Model Development | 26% | - Select appropriate modeling approach
|
| Topic 3: Data Preparation for Machine Learning | 28% | - Ensure data integrity and prepare for modeling
|
| Topic 4: ML Solution Monitoring, Maintenance, and Security | 24% | - Secure ML solutions and resources
|
根據過去的考試題和答案的研究,PDFExamDumps提供的Amazon MLA-C01練習題和真實的考試試題有緊密的相似性。PDFExamDumps是可以承諾您能100%通過你第一次參加的Amazon MLA-C01 認證考試。
問題 #220
A company is using ML to predict the presence of a specific weed in a farmer's field. The company is using the Amazon SageMaker linear learner built-in algorithm with a value of multiclass_dassifier for the predictorjype hyperparameter.
What should the company do to MINIMIZE false positives?
答案:B
問題 #221
An ML engineer is preparing a dataset that contains medical records to train an ML model to predict the likelihood of patients developing diseases.
The dataset contains columns for patient ID, age, medical conditions, test results, and a "Disease" target column.
How should the ML engineer configure the data to train the model?
答案:A
解題說明:
Patient ID is a unique identifier and does not contain predictive information. Including it can cause the model to overfit by memorizing records rather than learning meaningful patterns.
AWS ML best practices recommend removing identifiers that are not causally related to the target variable.
Age, medical conditions, and test results are clinically relevant features and should be retained. The target column must remain for supervised learning.
Therefore, Option A is the correct and AWS-aligned choice.
問題 #222
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.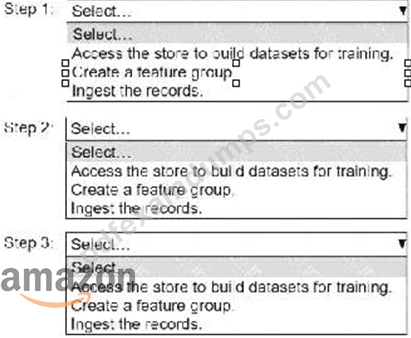
答案:
解題說明: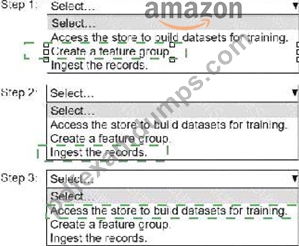
Explanation: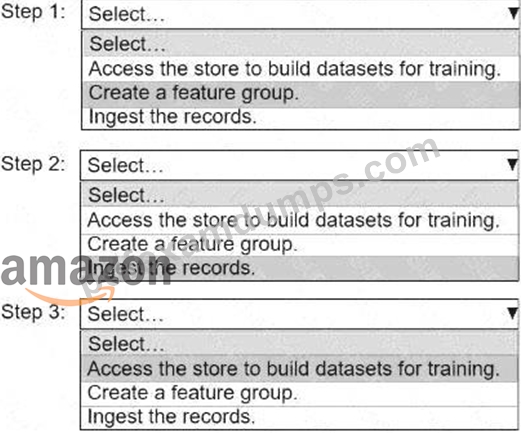
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
問題 #223
A company uses Amazon SageMaker AI to create ML models. The data scientists need fine-grained control of ML workflows, DAG visualization, experiment history, and model governance for auditing and compliance.
Which solution will meet these requirements?
答案:C
解題說明:
Amazon SageMaker Pipelines provides native orchestration of ML workflows with fine-grained control, DAG-based visualization, and seamless integration with SageMaker Studio. AWS documentation explicitly states that Pipelines is designed for end-to-end ML workflow automation and visualization.
SageMaker ML Lineage Tracking records relationships between datasets, models, training jobs, and endpoints, enabling full auditability and governance, which is essential for compliance.
SageMaker Experiments tracks experiment metrics but does not provide lineage-level governance.
CodePipeline is a general CI/CD service and lacks ML-specific DAG visualization and lineage tracking.
AWS best practices recommend combining SageMaker Pipelines + SageMaker Studio + ML Lineage Tracking for enterprise-grade ML workflow management.
Therefore, Option C is the correct and AWS-verified solution.
問題 #224
An ML engineer is developing a neural network to run on new user data. The dataset has dozens of floating- point features. The dataset is stored as CSV objects in an Amazon S3 bucket. Most objects and columns are missing at least one value. All features are relatively uniform except for a small number of extreme outliers.
The ML engineer wants to use Amazon SageMaker Data Wrangler to handle missing values before passing the dataset to the neural network.
Which solution will provide the MOST complete data?
答案:D
解題說明:
The primary goal is to produce the most complete dataset while handling missing values and extreme outliers appropriately. Dropping samples (Option A) or columns (Option D) would reduce data completeness and potentially remove valuable information, which contradicts the requirement.
Imputation is therefore the correct approach. Between mean and median imputation, AWS ML best practices recommend using the median when features contain outliers. The mean is sensitive to extreme values and can be skewed significantly, leading to imputed values that are not representative of the typical data distribution.
In contrast, the median is robust to outliers, making it a better statistical estimator for central tendency in such datasets.
Amazon SageMaker Data Wrangler supports median imputation as a built-in transformation, enabling ML engineers to handle missing values consistently across large tabular datasets without custom code. This approach preserves all rows and columns while minimizing distortion caused by extreme values, which is particularly important for neural networks that are sensitive to input distributions.
Therefore, imputing missing values with the median value provides the most complete and statistically appropriate dataset for training.
問題 #225
......
你想参加Amazon的MLA-C01认证考试吗?你身边肯定有很多人参加过这个考试了吧?因为这是一个很重要的考试,如果取得这个考试的认证资格,你将可以得到很多的好处。那麼,你想別人請教怎樣通過考試的方法了嗎?準備考試的方法有很多種,但是最高效的方法是用一個好的工具。那麼對你來說什麼才是好的工具呢?當然是PDFExamDumps的MLA-C01考古題了。
MLA-C01權威考題: https://www.pdfexamdumps.com/MLA-C01_valid-braindumps.html
順便提一下,可以從雲存儲中下載PDFExamDumps MLA-C01考試題庫的完整版:https://drive.google.com/open?id=1NELp-SLUATWqs9pTu9yBN0lgKE6DAk83