ちなみに、ShikenPASS Databricks-Certified-Data-Engineer-Associateの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1-i3osrO13RWdnS1nqfmegDU_svjyIXNb
なにごとによらず初手は难しいです、どのようにDatabricks Databricks-Certified-Data-Engineer-Associate試験への復習を始めて悩んでいますか。我々のDatabricks Databricks-Certified-Data-Engineer-Associate問題集を購買するのはあなたの試験に準備する第一歩です。我々の提供するDatabricks Databricks-Certified-Data-Engineer-Associate問題集はあなたの需要に満足できるだけでなく、試験に合格する必要があることです。あなたはまだ躊躇しているなら、ShikenPASSのDatabricks-Certified-Data-Engineer-Associate問題集デモを参考しましょ。
| Section | Objectives |
|---|---|
| Topic 1: Data Ingestion and ELT Development | - Data ingestion using Spark SQL and PySpark - ETL patterns and transformations - Handling structured and semi-structured data |
| Topic 2: Data Processing and Transformations | - User-defined functions (UDFs) - PySpark DataFrame transformations - Delta Lake fundamentals (tables, transactions, optimization) - Apache Spark SQL operations (joins, aggregations, filtering) |
| Topic 3: Databricks Lakehouse Platform Fundamentals | - Workspace, architecture, and core platform concepts - Clusters, notebooks, and basic Databricks environment usage |
| Topic 4: Productionizing Data Pipelines | - Scheduling and monitoring jobs - Pipeline deployment and operationalization - Databricks Workflows / Jobs orchestration |
| Topic 5: Data Governance and Quality | - Data quality concepts and management - Data access control and governance - Unity Catalog basics |
>> Databricks Databricks-Certified-Data-Engineer-Associate日本語 <<
いろいろな人はDatabricksのDatabricks-Certified-Data-Engineer-Associateを長い時間で復習して試験の模式への不適応で失敗することを心配していますから、我々ShikenPASSはあなたに試験の前に試験の真実な模式を体験させます。DatabricksのDatabricks-Certified-Data-Engineer-Associate試験のソフトは問題数が豊富であなたに大量の練習で能力を高めさせます。そのほかに、専門家たちの解答への詳しい分析があります。あなたにDatabricksのDatabricks-Certified-Data-Engineer-Associate試験に自信を持たせます。
質問 # 23
A data engineer needs to combine sales data from an on-premises PostgreSQL database with customer data in Azure Synapse for a comprehensive report. The goal is to avoid data duplication and ensure up-to-date information. How should the data engineer achieve this using Databricks?
正解:C
解説:
Lakehouse Federation allows Databricks to directly query external data sources like PostgreSQL and Azure Synapse without duplicating data. This ensures the report always uses up-to-date information while avoiding the overhead and cost of data movement.
質問 # 24
A new data engineering team has been assigned to work on a project. The team will need access to database customers in order to see what tables already exist. The team has its own group team.
Which of the following commands can be used to grant the necessary permission on the entire database to the new team?
正解:C
解説:
The correct command to grant the necessary permission on the entire database to the new team is to use the GRANT USAGE command. The GRANT USAGE command grants the principal the ability to access the securable object, such as a database, schema, or table. In this case, the securable object is the database customers, and the principal is the group team. By granting usage on the database, the team will be able to see what tables already exist in the database. Option E is the only option that uses the correct syntax and the correct privilege type for this scenario. Option A uses the wrong privilege type (VIEW) and the wrong securable object (CATALOG). Option B uses the wrong privilege type (CREATE), which would allow the team to create new tables in the database, but not necessarily see the existing ones. Option C uses the wrong securable object (CATALOG) and the wrong principal (customers). Option D uses the wrong securable object (team) and the wrong principal (customers). References: GRANT, Privilege types, Securable objects, Principals
質問 # 25
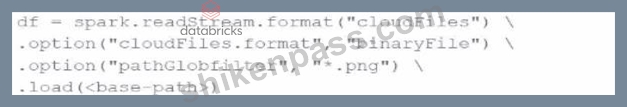
A data engineer needs to parse only png files in a directory that contains files with different suffixes. Which code should the data engineer use to achieve this task?


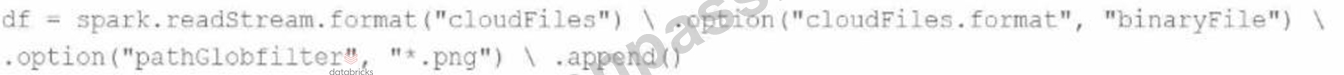
正解:A
質問 # 26
A data analyst has created a Delta table sales that is used by the entire data analysis team. They want help from the data engineering team to implement a series of tests to ensure the data is clean. However, the data engineering team uses Python for its tests rather than SQL.
Which of the following commands could the data engineering team use to access sales in PySpark?
正解:A
質問 # 27
A data engineer has developed a data pipeline to ingest data from a JSON source using Auto Loader, but the engineer has not provided any type inference or schema hints in their pipeline. Upon reviewing the data, the data engineer has noticed that all of the columns in the target table are of the string type despite some of the fields only including float or boolean values.
Which of the following describes why Auto Loader inferred all of the columns to be of the string type?
正解:E
解説:
JSON data is a text-based format that represents data as a collection of name-value pairs. By default, when Auto Loader infers the schema of JSON data, it treats all columns as strings. This is because JSON data can have varying data types for the same column across different files or records, and Auto Loader does not attempt to reconcile these differences. For example, a column named "age" may have integer values in some files, but string values in others. To avoid data loss or errors, Auto Loader infers the column as a string type. However, Auto Loader also provides an option to infer more precise column types based on the sample data. This option is called cloudFiles.inferColumnTypes and it can be set to true or false. When set to true, Auto Loader tries to infer the exact data types of the columns, such as integers, floats, booleans, or nested structures. When set to false, Auto Loader infers all columns as strings. The default value of this option is false. Reference: Configure schema inference and evolution in Auto Loader, Schema inference with auto loader (non-DLT and DLT), Using and Abusing Auto Loader's Inferred Schema, Explicit path to data or a defined schema required for Auto loader.
質問 # 28
......
当社ShikenPASSのすべての専門家および教授の唯一の目標は、すべての人々に最適で適切なDatabricks-Certified-Data-Engineer-Associate学習教材を設計することです。多くの顧客のさまざまな要求に応じて、彼らはすべての顧客向けに3つの異なるバージョンのDatabricks-Certified-Data-Engineer-Associate認定試験ガイド資料を設計しました:PDF、ソフト、およびAPPバージョン。弊社のDatabricks-Certified-Data-Engineer-Associate試験問題を使用するすべての人がDatabricks-Certified-Data-Engineer-Associate試験に合格し、関連する認定資格を取得できることを心から願っています。そして、Databricks-Certified-Data-Engineer-Associate試験問題の合格率は98%以上です。
Databricks-Certified-Data-Engineer-Associate復習解答例: https://www.shikenpass.com/Databricks-Certified-Data-Engineer-Associate-shiken.html
P.S.ShikenPASSがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Associateダンプ:https://drive.google.com/open?id=1-i3osrO13RWdnS1nqfmegDU_svjyIXNb