퍼펙트한Microsoft DP-750시험대비덤프자료는 Fast2test가 전문입니다. Microsoft DP-750덤프를 다운받아 가장 쉬운 시험준비를 하여 한방에 패스가는것입니다. 다같이 Microsoft DP-750덤프로 시험패스에 주문걸어 보아요. 마술처럼Microsoft DP-750시험합격이 실현될것입니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
Fast2test의 Microsoft인증 DP-750덤프를 구매하시고 공부하시면 밝은 미래를 예약한것과 같습니다. Fast2test의 Microsoft인증 DP-750덤프는 고객님이 시험에서 통과하여 중요한 IT인증자격증을 취득하게끔 도와드립니다. IT인증자격증은 국제적으로 인정받기에 취직이나 승진 혹은 이직에 힘을 가해드립니다. 학원공부나 다른 시험자료가 필요없이Fast2test의 Microsoft인증 DP-750덤프만 공부하시면Microsoft인증 DP-750시험을 패스하여 자격증을 취득할수 있습니다.
질문 # 48
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
정답:B
설명:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
질문 # 49
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
정답:A,B
설명:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
질문 # 50
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.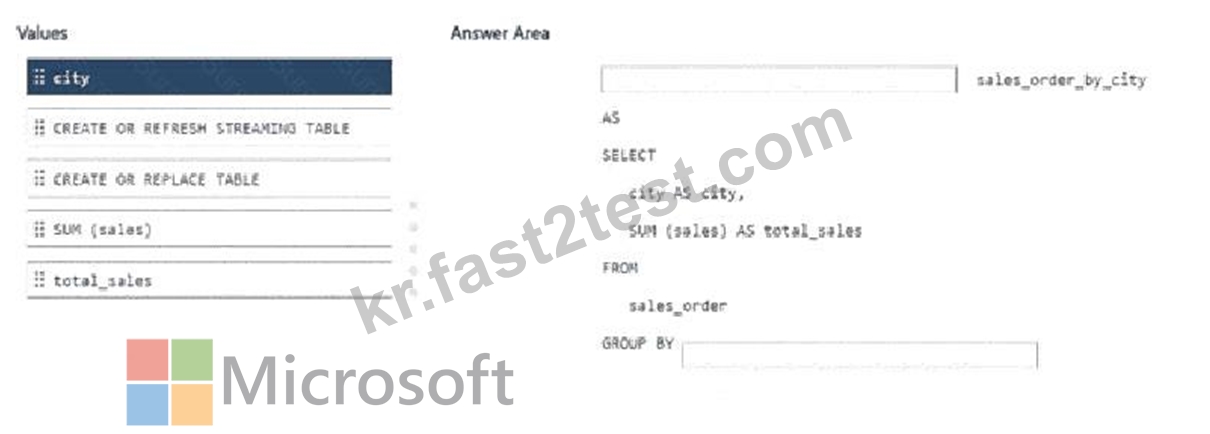
정답:
설명: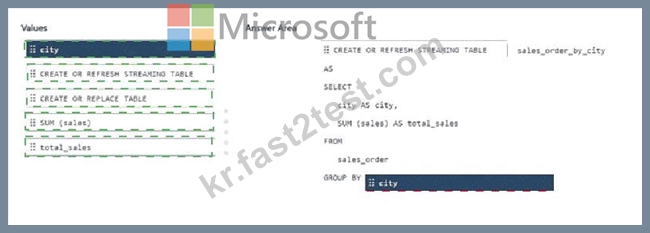
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
질문 # 51
What improves join performance for small lookup tables?
정답:D
질문 # 52
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.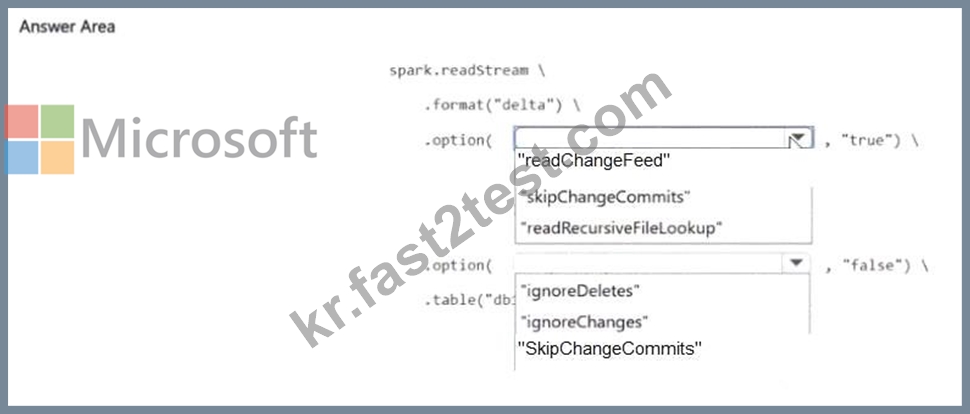
정답:
설명: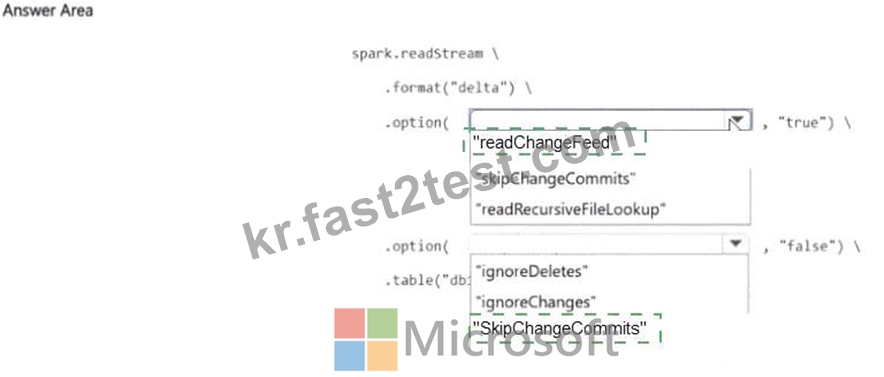
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
질문 # 53
......
인터넷에는Microsoft인증 DP-750시험대비공부자료가 헤아릴수 없을 정도로 많습니다.이렇게 많은Microsoft인증 DP-750공부자료중 대부분 분들께서 저희Fast2test를 선택하는 이유는 덤프 업데이트가 다른 사이트보다 빠르다는 것이 제일 큰 이유가 아닐가 싶습니다. Fast2test의 Microsoft인증 DP-750덤프를 구매하시면 덤프가 업데이트되면 무료로 업데이트된 버전을 제공받을수 있습니다.
DP-750최신 덤프자료: https://kr.fast2test.com/DP-750-premium-file.html