The Anthropic CCAR-P certification exam is not only validate your skills but also prove your expertise. It can prove to your boss that he did not hire you in vain. The current IT industry needs a reliable source of Anthropic CCAR-P Certification Exam, Exam4Labs is a good choice. Select Exam4Labs CCAR-P exam material, so that you do not need yo waste your money and effort. And it will also allow you to have a better future.
| Section | Weight | Objectives |
|---|---|---|
| Evaluation, Testing & Optimization | 16% | - Evaluation metrics and datasets - Cost and performance optimization - Evaluation framework design - System issue diagnosis - A/B testing - Production monitoring and optimization |
| Stakeholder Communication & Lifecycle Management | 14% | - Communicating architectural decisions - Solution lifecycle management - Stakeholder management - Architecture documentation - Discovery and requirements gathering - Service-level agreements |
| Solution Design & Architecture | 17% | - Translating business problems into Claude-based AI solutions - Architectural patterns
- End-to-end architecture design - Alignment with business value, cost, performance, and SLAs - Multi-agent systems and orchestration |
| Integration | 19% | - Claude integration mechanisms
- Authentication and authorization analysis |
| Claude Models, Prompting & Context Engineering | 13% | - Claude model selection and trade-offs - System prompts and prompt templates - Prompt reuse and context engineering strategies - Guardrails - Context window optimization |
| Governance, Safety & Risk Management | 14% | - AI safety and guardrails - Security and risk management - Ethical AI considerations - Human-in-the-loop validation - Regulatory and compliance requirements |
| Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - Developer enablement - AI-assisted developer workflows - Debugging and operational issue resolution |
>> Test Certification CCAR-P Cost <<
Since the content of the examination is also updating daily, you will need real and latest Anthropic CCAR-P Exam Dumps to prepare successfully for the CCAR-P certification exam in a short time. People who don't study from updated Claude Certified Architect - Professional (CCAR-P) questions fail the examination and loss time and money.
NEW QUESTION # 27
You are a solution architect designing a Claude-based assistant with access to 60 internal tools across multiple business domains. Loading every tool definition on every request increases token usage and time to first response.
Which design pattern best addresses this issue without sacrificing capability breadth?
Answer: A
Explanation:
Progressive tool discovery preserves the complete capability catalog while limiting initial context to a curated set of common tools and a discovery mechanism. When the task requires an additional capability, Claude searches the catalog and loads only the relevant tool definitions.
Anthropic's Tool Search mechanism implements this pattern through deferred loading. The context initially contains the search tool and any deliberately non-deferred tools; relevant definitions are expanded only when discovered. This reduces token consumption and helps maintain tool-selection accuracy in large catalogs.
Tool Search Tool
Option B adds a model call and still repeatedly processes all definitions, increasing latency and cost while potentially losing important schema details. Option C treats a larger context window as permission to waste context and does not address time-to-first-response overhead. Option D reduces capability breadth because the fixed five tools may be irrelevant to a given task.
The architect should provide clear tool and server descriptions, define which high-frequency tools remain immediately available, and evaluate discovery recall, selection accuracy, latency, and context savings across representative workflows.
Study Guide references/topics: Progressive discovery; deferred tool loading; MCP scaling; context optimization; tool-selection accuracy; on-demand capability loading.
NEW QUESTION # 28
An operations engineer reports that a Claude-based pipeline began returning malformed JSON responses after a scheduled maintenance window, causing downstream processing failures.
Which two investigative steps most directly isolate the root cause? (Select two.)
Answer: C,D
Explanation:
The strongest investigation combines configuration comparison with controlled replay. Comparing the current system prompt and output-schema settings against the last known good version identifies maintenance-related configuration drift. Relevant differences include removed formatting instructions, altered schema requirements, incompatible parser expectations, changed stop sequences, or a disabled structured-output mechanism.
Replaying known premaintenance requests against the current configuration creates a controlled test set.
Inspecting the raw response before parsing then establishes whether malformed JSON originates in model generation or is introduced by streaming assembly, transport handling, post-processing, or the downstream parser. If the raw response is valid but the pipeline rejects it, the fault lies after generation. If the raw response is malformed, the prompt, schema enforcement, stop reason, and request configuration become the primary investigation targets.
Clearing the prompt cache assumes cache corruption without evidence. Changing model tiers introduces another variable and weakens causal attribution. Raising `max_tokens` is appropriate only when raw responses show truncation and the returned stop reason indicates the token limit was reached; it is not the most direct initial test.
Study Guide references/topics: [Increasing output consistency](https://docs.anthropic.com/en/docs/test-and- evaluate/strengthen-guardrails/increase-consistency); [agent evaluation methodology] (https://www.anthropic.
com/engineering/demystifying-evals-for-ai-agents); regression replay; last-known-good comparison; raw- output inspection.
NEW QUESTION # 29
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.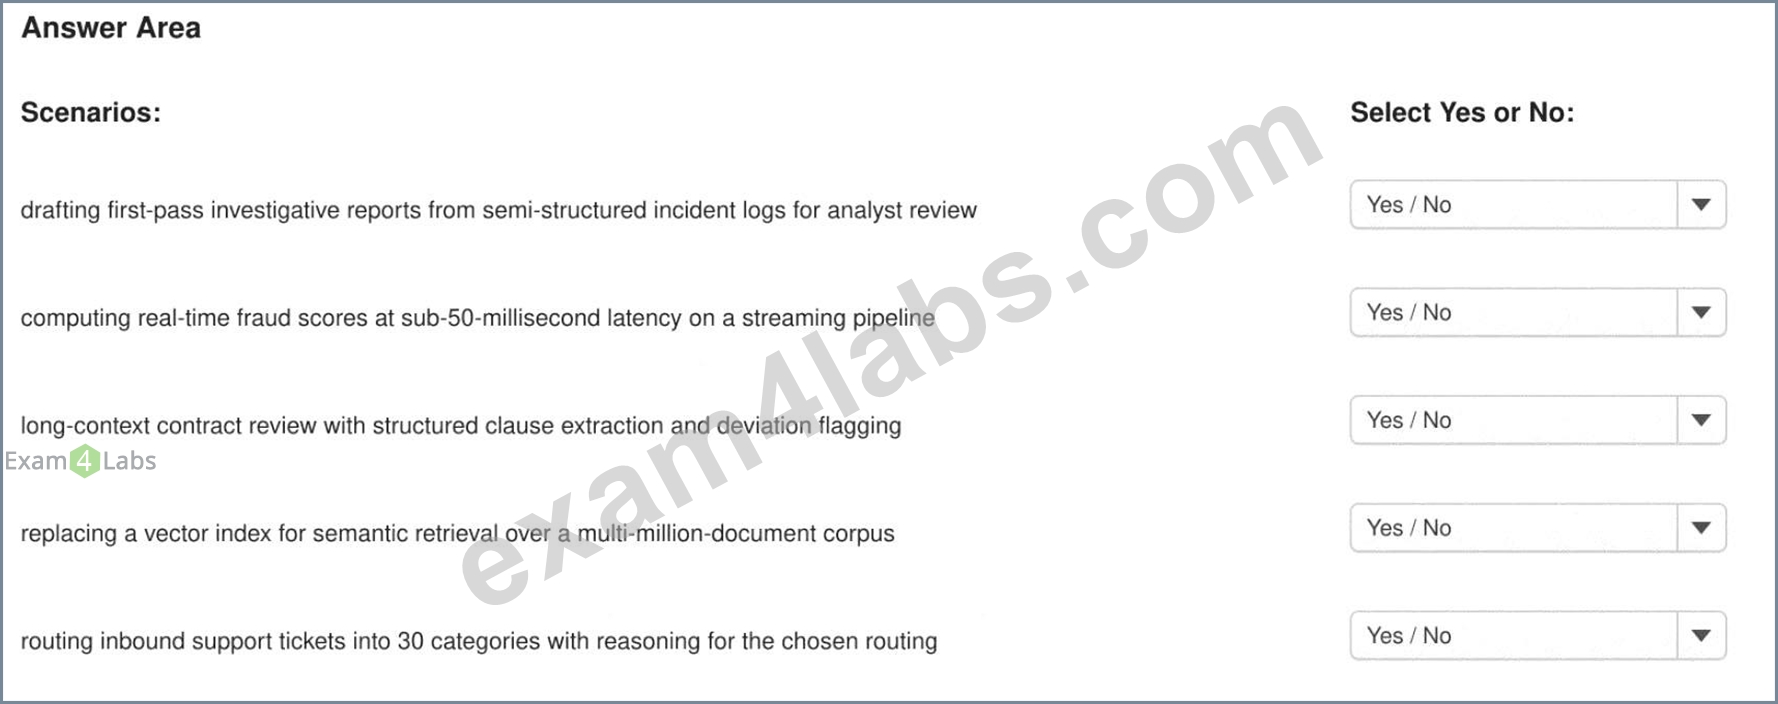
Answer:
Explanation: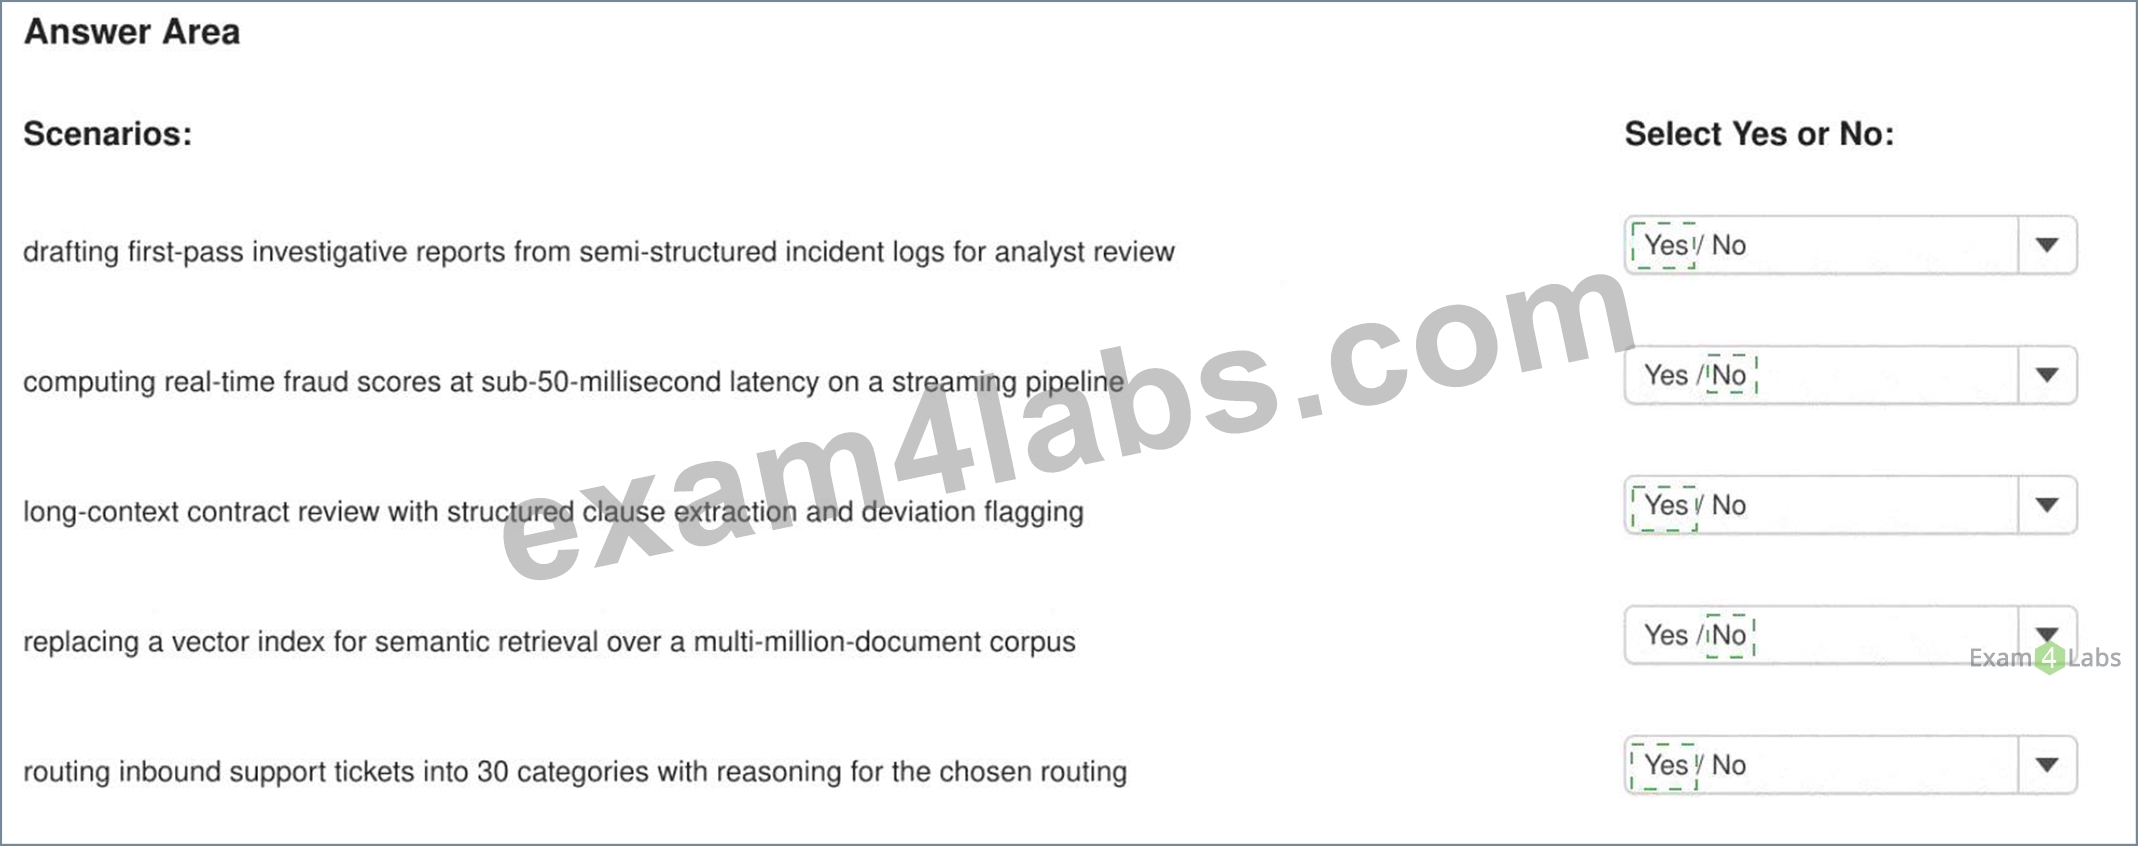
Explanation:
* Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes
* Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No
* Long-context contract review with structured clause extraction and deviation flagging - Yes
* Replacing a vector index for semantic retrieval over a multi-million-document corpus - No
* Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 30
You are compiling a diagnostic toolkit for Claude Code operational issues.
Which two diagnostic actions belong in the toolkit? (Select two.)
Each correct answer presents a complete solution.
Answer: A,C
Explanation:
A minimal reproduction and MCP status inspection are foundational diagnostic actions because they produce direct, interpretable evidence. A minimal reproduction removes unrelated prompts, tools, settings, hooks, and repository state while changing one variable at a time. This determines whether the failure follows a particular configuration, server, command, model request, or project artifact. It also creates a reproducible evidence package if escalation later becomes necessary.
MCP inspection addresses a common Claude Code failure domain. `claude mcp list` displays configured servers and their health states, including connected, authentication-required, pending-approval, and failed-to- connect conditions. `claude mcp get < name > ` provides server-specific details, while `/mcp` exposes status within an interactive session. These checks distinguish model behavior from transport, authentication, configuration, and workspace-trust failures.
Increasing temperature reduces repeatability and introduces additional variation, making root-cause isolation more difficult. Filing a support ticket before collecting local evidence reverses the appropriate diagnostic sequence. An immediate rollback may eventually be used as a controlled version comparison, but it changes the environment before a baseline has been captured and is therefore not a primary toolkit action.
Study Guide references/topics: [Managing and diagnosing MCP servers](https://docs.anthropic.com/en/docs
/claude-code/mcp); minimal reproducible cases; controlled-variable troubleshooting; authentication and connection-state diagnostics.
NEW QUESTION # 31
A managed agent deployment for claims triage has grown from 6 tools to 34 tools over 18 months as product teams added capabilities. Triage accuracy has declined from 91 percent to 78 percent, and average tool- selection latency has increased by 2.3 seconds. A junior engineer has proposed adding a tool-router agent in front of the current agent to filter the tool list per request.
Which two findings should you present to justify capability decomposition before adding the router? (Select two.) Each correct answer presents part of the solution.
Answer: A,C
Explanation:
Four distinct workflow domains indicate that the agent's responsibilities have expanded beyond a cohesive capability boundary. Decomposing the deployment into domain-focused agents reduces each agent's tool- selection space and produces clearer prompts, permissions, evaluations, and ownership. Option E strengthens this conclusion because placing a model-based router before the existing overloaded agent adds latency, cost, and another failure point without correcting the underlying capability sprawl. Overlapping descriptions should be clarified, while unused tools may simply be removed; neither finding alone proves that separate domain agents are required. Public documentation of a pattern is not evidence that it fits this workload. Anthropic emphasizes simple composable patterns, clearly differentiated tools, and empirical evaluation before adding orchestration complexity. Building Effective Agents
NEW QUESTION # 32
......
For candidates who are going to buying CCAR-P training materials online, you may pay more attention to the privacy protection. We respect the private information of you. If you choose us, we can ensure you that your personal information such as your name and email address will be protected well. Once the order finishes, your personal information will be concealed. Besides, CCAR-P Exam Materials contain both questions and answers, and it’s convenient for you to have a check of answers. We have online and offline chat service for CCAR-P exam materials, if you have any questions, you can have a conversation with them.
CCAR-P Actual Dump: https://www.exam4labs.com/CCAR-P-practice-torrent.html