P.S. Free & New DP-600 dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1ctUi9xLR_Ta2hWpsDl2IV8KYFAOzCri8
During these years, our PDF version of our Microsoft DP-600 study engine stays true to its original purpose to pursue a higher pass rate that has never been attained in the past. And you will be content about our considerate service on our Microsoft DP-600 training guide. If you have any question, you can just contact us!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-600 Braindumps <<
The DP-600 Exam is one of the best platforms that have been helping the Microsoft DP-600 exam candidates in their preparation. Several Microsoft DP-600 exam candidates have already passed their Implementing Analytics Solutions Using Microsoft Fabric exam with good scores. They all used the Exams. DP-600 Exam Questions and got success in the final Microsoft DP-600 exam easily.
NEW QUESTION # 20
You have a Fabric tenant that contains a workspace named Workspace1.
You plan to deploy a semantic model named Model1 by using the XMLA endpoint.
You need to optimize the deployment of Model1. The solution must minimize how long it takes to deploy Model1.
What should you do in Workspace1?
Answer: A
NEW QUESTION # 21
You have a Fabric tenant that contains a workspace named Workspace! Workspace1 uses the Pro license mode and contains a semantic model named Model1.
You have an Azure DevOps organization.
You need to enable version control for Workspace1. The solution must ensure that Model 1 is added to the repository.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation:
We need to enable version control for a Fabric workspace (Workspace1) and ensure that Model1 (a semantic model) is added to an Azure DevOps repository.
Key facts:
Workspace1 is in Pro mode. To enable Git integration, the workspace must be assigned to a Fabric capacity.
Git integration steps in Fabric:
Assign the workspace to a Fabric capacity.
Connect the workspace to a Git provider (e.g., Azure DevOps or GitHub).
Sync the workspace with the repository (to push artifacts like semantic models).
Branch policies and deployment pipelines are not needed for simply enabling version control.
Correct Sequence:
Assign Workspace1 to a Fabric capacity.
Connect Workspace1 to a Git provider.
Sync Workspace1 with the repository.
Final Answer:
Step 1 # Assign Workspace1 to a Fabric capacity
Step 2 # Connect Workspace1 to a Git provider
Step 3 # Sync Workspace1 with the repository
References:
Microsoft Fabric Git integration
Enable Git in Fabric workspace
This ensures Model1 will be version-controlled in the linked DevOps repository.
NEW QUESTION # 22
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.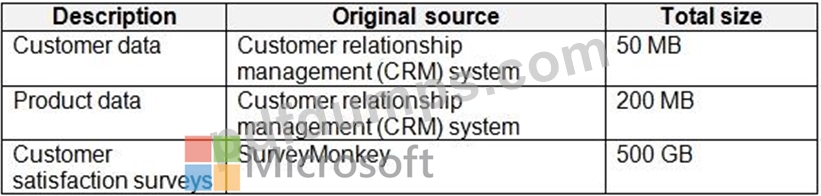
The Product data contains a single table and the following columns.
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
You need to ensure the data loading activities in the AnalyticsPOC workspace are executed in the appropriate sequence. The solution must meet the technical requirements.
What should you do?
Answer: C
Explanation:
Pipeline can ensure the activities follow the required sequence.
https://learn.microsoft.com/en-us/fabric/data-factory/activity-overview#data-transformation- activities
NEW QUESTION # 23
You have a Fabric warehouse that contains a table named SalesOrderDetail. SalesOrderDetail contains three columns named OrderQty, ProductID and SalesOrderlD. SalesOrderDetail contains one row per combination of SalesOrderlD and ProductID.
You need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Which T-SQL statement should you run?


Answer: D
Explanation:
Comprehensive Detailed Explanation
We need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order .
Step 1: Analyze the requirement
Table: SalesOrderDetail
Columns: OrderQty , ProductID , SalesOrderID
Each row = one product in a sales order.
Requirement: For each SalesOrderID , calculate what percentage each product contributes to the total order quantity.
This means we must:
Calculate the total order quantity per SalesOrderID .
Divide each product's OrderQty by that total.
Express it as a percentage.
Step 2: Evaluate the options
A). Uses OVER(ORDER BY ProductID)
Wrong: ORDER BY does not segment data, it only defines sequence. We need grouping by sales order.
B). Uses OVER(PARTITION BY ProductID)
Wrong: This would calculate percentages per product across all sales orders, not per sales order.
C). Uses OVER(PARTITION BY SalesOrderID)
Correct: This computes the total OrderQty per SalesOrderID and divides each product's quantity by that total.
Exactly what the requirement asks.
D). Uses OVER(ORDER BY SalesOrderID)
Wrong: Again, ORDER BY just sequences rows, does not group them.
Step 3: Correct Query
SELECT
SalesOrderID,
ProductID,
OrderQty,
CAST ( 1. * OrderQty / SUM (OrderQty)
OVER ( PARTITION BY SalesOrderID) * 100 AS DECIMAL ( 5 , 2 ))
AS PercentByProductID
FROM Sales.SalesOrderDetail;
Why Option C is Correct
PARTITION BY SalesOrderID ensures the denominator is the total quantity for the current order .
This produces the correct percentage breakdown of each product inside its sales order.
References
T-SQL Window Functions
Aggregate Functions with PARTITION BY
Microsoft Fabric Warehouse T-SQL Support
NEW QUESTION # 24
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
Answer: B
NEW QUESTION # 25
......
Hence, memorizing them will help you get prepared for the Microsoft DP-600 examination in a short time. The product of PDFDumps comes in PDF, desktop practice exam software, and Implementing Analytics Solutions Using Microsoft Fabric (DP-600) web-based practice test. To give you a complete understanding of these formats, we have discussed their features below.
DP-600 Exams Training: https://www.pdfdumps.com/DP-600-valid-exam.html
BONUS!!! Download part of PDFDumps DP-600 dumps for free: https://drive.google.com/open?id=1ctUi9xLR_Ta2hWpsDl2IV8KYFAOzCri8