Databricks-Certified-Data-Engineer-Professional復習解答例 & Databricks-Certified-Data-Engineer-Professionalテスト参考書

無料でクラウドストレージから最新のIt-Passports Databricks-Certified-Data-Engineer-Professional PDFダンプをダウンロードする:https://drive.google.com/open?id=126d9NJVp5okuvkZmt3Srce03z10r4Sjs
人々は常に、特定の分野で有能で熟練していることを証明したいと考えています。能力を証明する方法はさまざまですが、最も直接的で便利な方法は、Databricks-Certified-Data-Engineer-Professional認定試験に参加し、認定証を取得することです。 Databricks-Certified-Data-Engineer-Professional認定に合格すると、非常に有能で優秀であることを証明できます。また、Databricks-Certified-Data-Engineer-Professionalテストに合格することで有用な知識とスキルを習得できます。 Databricks-Certified-Data-Engineer-Professionalガイドトレントを購入すると、It-PassportsのDatabricks-Certified-Data-Engineer-Professional試験に合格するのに役立ちます。時間と労力はほとんどかかりません。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion and Processing | - Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Time travel and versioning
- Delta Lake transactions and ACID properties
|
| Data Modeling and Transformation | - Spark SQL transformations
- Dimensional modeling concepts
- Performance optimization techniques
|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
| Production Pipelines and Orchestration | - Databricks Workflows
- Error handling and recovery strategies
- Job scheduling and monitoring
|
>> Databricks-Certified-Data-Engineer-Professional復習解答例 <<
Databricks-Certified-Data-Engineer-Professionalテスト参考書、Databricks-Certified-Data-Engineer-Professional試験関連情報
あなたの人生に残念と後悔を残しないように、私たちはできるだけ人生を変えるあらゆるチャンスをつかむ必要があります。あなたはそれをやったことができましたか。It-PassportsのDatabricksのDatabricks-Certified-Data-Engineer-Professional試験トレーニング資料は成功したいIT職員のために作成されたのです。あなたがDatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験に合格することを助けます。成功と擦れ違うことを避けるように速く行動しましょう。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q144-Q149):
質問 # 144
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
- A. validateSchema = false
- B. mergeSchema = true
- C. overwriteSchema = true
- D. ignoreChanges = false
正解:B
解説:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
質問 # 145
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- B. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
- C. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- D. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- E. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
正解:D
質問 # 146
A data governance team at a large enterprise is improving data discoverability across its organization. The team has hundreds of tables in their Databricks Lakehouse with thousands of columns that lack proper documentation. Many of these tables were created by different teams over several years, with missing context about column meanings and business logic. The data governance team needs to quickly generate comprehensive column descriptions for all existing tables to meet compliance requirements and improve data literacy across the organization. They want to leverage modern capabilities to automatically generate meaningful descriptions rather than manually documenting each column, which would take months to complete. Which approach should the team use in Databricks to automatically generate column comments and descriptions for existing tables?
- A. Write custom PySpark code using df.describe() and df.schema to programmatically generate basic statistical descriptions for each column.
- B. Navigate to the table in Databricks Catalog Explorer, select the table schema view, and use the AI Generate option which leverages artificial intelligence to automatically create meaningful column descriptions based on column names, data types, sample values, and data patterns.
- C. Use Delta Lake's DESCRIBE HISTORY command to analyze table evolution and infer column purposes from historical changes.
- D. Use the DESCRIBE TABLE command to extract existing schema information and manually write descriptions based on column names and data types.
正解:B
解説:
The Catalog Explorer provides an AI-powered "AI Generate" capability that automatically creates intelligent column descriptions by analyzing column names, data types, sample values, and observed data patterns. This approach enables rapid, scalable documentation of existing tables, significantly improving data discoverability and compliance without manual effort.
質問 # 147
A data engineer is working in an interactive notebook with many transformations before outputting the result from display(df.collect() ). The notebook includes wide transformations and a cross join.
The data engineer is getting the following error: "The spark driver has stopped unexpectedly and is restarting. Your notebook will be automatically reattached." Which action should the data engineer take?
- A. Check into the Spark UI to see how many jobs are assigned to each stage as they are employing fewer executors.
- B. Rewrite their code to avoid putting memory pressure on the driver node.
- C. Run the notebook on a single node cluster to keep driver from falling.
- D. Look at the compute metrics UI to see if the executors have higher than 90% memory utilization.
正解:B
解説:
Calling df.collect() on a large DataFrame forces all data to be loaded into the driver's memory.
With wide transformations and a cross join, this can easily exceed the driver's capacity, causing it to crash. The data engineer should rewrite the code to avoid collecting large datasets on the driver, using operations like display(df) or writing to storage instead.
質問 # 148
The following code has been migrated to a Databricks notebook from a legacy workload:
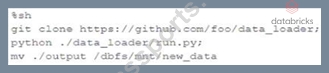
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- B. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- E. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
正解:C
解説:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
質問 # 149
......
試験を受けることでDatabricks認定を取得することを期待する人が増えています。ただし、多くの人にとって試験は非常に困難です。特に正しい学習教材を選択せずに適切な方法を見つけた場合、Databricks-Certified-Data-Engineer-Professional試験に合格して関連する認定を取得することはより困難になります。関連する認定を効率的な方法で取得したい場合は、当社のDatabricks-Certified-Data-Engineer-Professional学習教材を選択してください。弊社のDatabricks-Certified-Data-Engineer-Professional学習教材が試験に合格し、簡単に認定を取得するのに役立ちます。
Databricks-Certified-Data-Engineer-Professionalテスト参考書: https://www.it-passports.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional資格取得 🏌 Databricks-Certified-Data-Engineer-Professional試験参考書 🕞 Databricks-Certified-Data-Engineer-Professionalシュミレーション問題集 🪓 ➥ www.jptestking.com 🡄には無料の➠ Databricks-Certified-Data-Engineer-Professional 🠰問題集がありますDatabricks-Certified-Data-Engineer-Professional認定資格試験問題集
- Databricks-Certified-Data-Engineer-Professional日本語試験情報 🧙 Databricks-Certified-Data-Engineer-Professional学習範囲 🚆 Databricks-Certified-Data-Engineer-Professional日本語試験情報 🏈 検索するだけで▷ www.goshiken.com ◁から▶ Databricks-Certified-Data-Engineer-Professional ◀を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional資格関連題
- 信頼的なDatabricks-Certified-Data-Engineer-Professional復習解答例一回合格-効果的なDatabricks-Certified-Data-Engineer-Professionalテスト参考書 🚕 ☀ jp.fast2test.com ️☀️を入力して“ Databricks-Certified-Data-Engineer-Professional ”を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional関連試験
- Databricks-Certified-Data-Engineer-Professional認定内容 🍹 Databricks-Certified-Data-Engineer-Professional日本語認定対策 🧦 Databricks-Certified-Data-Engineer-Professional資格関連題 🦎 ➠ www.goshiken.com 🠰から▛ Databricks-Certified-Data-Engineer-Professional ▟を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional予想試験
- Databricks-Certified-Data-Engineer-Professional関連資格試験対応 🔹 Databricks-Certified-Data-Engineer-Professional日本語解説集 😉 Databricks-Certified-Data-Engineer-Professionalトレーニング ⛵ 「 Databricks-Certified-Data-Engineer-Professional 」を無料でダウンロード「 www.passtest.jp 」ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional予想試験
- Databricks-Certified-Data-Engineer-Professional専門知識 🛵 Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🙂 Databricks-Certified-Data-Engineer-Professionalテスト資料 🙉 ▶ www.goshiken.com ◀にて限定無料の⮆ Databricks-Certified-Data-Engineer-Professional ⮄問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professional関連資格試験対応
- 信頼的なDatabricks-Certified-Data-Engineer-Professional復習解答例 | 最初の試行で簡単に勉強して試験に合格する - よくできたDatabricks Databricks Certified Data Engineer Professional Exam 🐦 ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️の試験問題は▛ www.mogiexam.com ▟で無料配信中Databricks-Certified-Data-Engineer-Professional資格取得
- 信頼的なDatabricks-Certified-Data-Engineer-Professional復習解答例一回合格-効果的なDatabricks-Certified-Data-Engineer-Professionalテスト参考書 🕟 { www.goshiken.com }で⇛ Databricks-Certified-Data-Engineer-Professional ⇚を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格取得
- 完璧なDatabricks-Certified-Data-Engineer-Professional復習解答例試験-試験の準備方法-便利なDatabricks-Certified-Data-Engineer-Professionalテスト参考書 🗳 ( www.japancert.com )にて限定無料の☀ Databricks-Certified-Data-Engineer-Professional ️☀️問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professionalトレーニング
- Databricks Databricks-Certified-Data-Engineer-Professional復習解答例: Databricks Certified Data Engineer Professional Exam - GoShiken パスリーディングプロバイダー 🐘 今すぐ➽ www.goshiken.com 🢪で「 Databricks-Certified-Data-Engineer-Professional 」を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語試験情報
- Databricks-Certified-Data-Engineer-Professional試験参考書 🛸 Databricks-Certified-Data-Engineer-Professionalテスト資料 👙 Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🏨 検索するだけで▶ www.passtest.jp ◀から▛ Databricks-Certified-Data-Engineer-Professional ▟を無料でダウンロードDatabricks-Certified-Data-Engineer-Professionalシュミレーション問題集
- fortunetelleroracle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
ちなみに、It-Passports Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=126d9NJVp5okuvkZmt3Srce03z10r4Sjs