BONUS!!! Download part of Exam4Tests ARA-C01 dumps for free: https://drive.google.com/open?id=1NI2vlbfClG9XLEbxmWO8b33rL7NlnrAR
Some candidates say that they prepare for ARA-C01 exam using some exam materials from other site but fail. If you still do not know how to pass exam, our Snowflake ARA-C01 actual test will be a clever choice for you now. You will know both dump price and exam quantity should not take into key account. The most key consideration is the quality of ARA-C01 Actual Test. If you are afraid of failure please rest assured to purchase our exam questions, I am sure that our ARA-C01 actual test will help you pass exam.
Snowflake ARA-C01 (SnowPro Advanced Architect Certification) certification exam is an essential certification for professionals who work with Snowflake. It validates the expertise of an individual in designing, deploying, and managing complex Snowflake environments. SnowPro Advanced Architect Certification certification is recognized by industry leaders and is a valuable asset for professionals who want to advance their careers in cloud computing. Passing the exam requires a thorough understanding of Snowflake's advanced features and best practices, and candidates who achieve this certification demonstrate their commitment to staying up-to-date with the latest industry trends and technologies.
>> ARA-C01 Reliable Practice Questions <<
Once you start to become diligent and persistent, you will be filled with enthusiasms. Nothing can defeat you as long as you are optimistic. We sincerely hope that our ARA-C01 study materials can become your new purpose. Our ARA-C01 Exam Questions can teach you much practical knowledge, which is beneficial to your career development. And with the ARA-C01 certification, you are bound to have a bighter future.
Snowflake ARA-C01 (SnowPro Advanced Architect Certification) Certification Exam is a highly specialized certification program designed for professionals who want to demonstrate their advanced technical knowledge and skills in designing, deploying, and managing Snowflake solutions. SnowPro Advanced Architect Certification certification exam is designed to assess the knowledge and skills required to build, design, and manage a Snowflake architecture at an expert level.
Snowflake ARA-C01 Certification Exam is composed of two parts, the first being a multiple-choice exam that tests fundamental knowledge of Snowflake architecture and features. The second part of the exam is a hands-on lab where candidates are given a set of requirements and need to implement a Snowflake solution to meet those requirements. The lab is designed to test the candidate's ability to apply their knowledge in real-world scenarios.
NEW QUESTION # 106
You have created a TASK in snowflake.
How will you resume it?
Answer: C
NEW QUESTION # 107
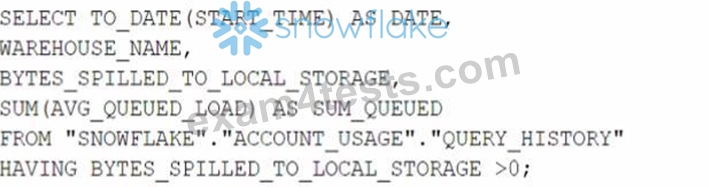
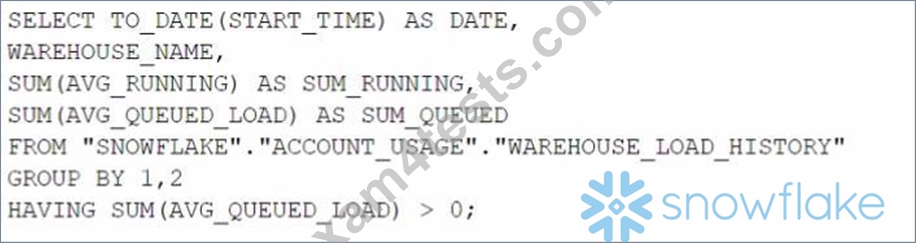
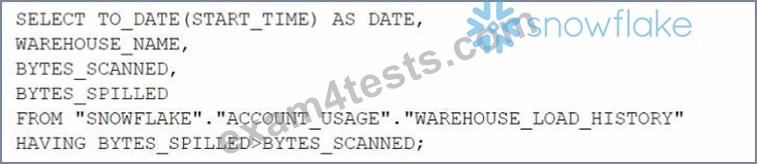
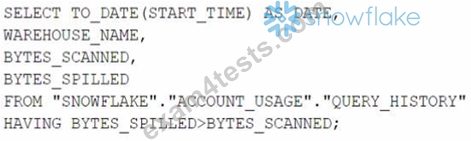
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: C
Explanation:
A multi-cluster warehouse is a virtual warehouse that can scale compute resources by adding or removing clusters based on the workload demand. A multi-cluster warehouse can improve the performance of a particular workload by reducing the query queue time and the data spillage to local storage. To identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse, you need to analyze the query history and look for the following indicators:
* High average queued load: This metric shows the average number of queries waiting in the queue for each warehouse cluster. A high value indicates that the warehouse is overloaded and cannot handle the concurrency demand.
* High bytes spilled to local storage: This metric shows the amount of data that was spilled from memory to local disk during query processing. A high value indicates that the warehouse size is too small and cannot fit the data in memory.
* High variation in workload: This metric shows the fluctuation in the number of queries submitted to the warehouse over time. A high variation indicates that the workload is unpredictable and dynamic, and requires a flexible scaling policy.
The query in option C is the best one to identify these indicators, as it selects the date, warehouse name, bytes spilled to local storage, and sum of average queued load from the query history table, and filters the results where bytes spilled to local storage is greater than zero. This query will show the days and warehouses that experienced data spillage and high queue time, and could benefit from a multi-cluster warehouse with auto-scale mode.
The query in option A is not correct, as it only selects the date and warehouse name, and does not include any metrics to measure the performance of the workload. The query in option B is not correct, as it selects the date, warehouse name, and average execution time, which is not a good indicator of the need for a multi-cluster warehouse. The query in option D is not correct, as it selects the date, warehouse name, and average credits used, which is not a good indicator of the need for a multi-cluster warehouse either.
References: Multi-cluster Warehouses, Query History View, Reducing Queues
NEW QUESTION # 108
How do Snowflake databases that are created from shares differ from standard databases that are not created from shares? (Choose three.)
Answer: A,C,F
NEW QUESTION # 109
A user is executing the following command sequentially within a timeframe of 10 minutes from start to finish: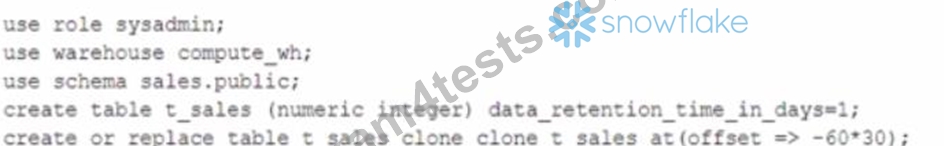
What would be the output of this query?
Answer: B
Explanation:
The query is executing a clone operation on an existing table t_sales with an offset to account for the retention time. The syntax used is correct for cloning a table in Snowflake, and the use of the at(offset => -60*30) clause is valid. This specifies that the clone should be based on the state of the table 30 minutes prior (60 seconds * 30). Assuming the table t_sales exists and has been modified within the last 30 minutes, and considering the data_retention_time_in_days is set to 1 day (which enables time travel queries for the past 24 hours), the table t_sales_clone would be successfully created based on the state of t_sales 30 minutes before the clone command was issued.
NEW QUESTION # 110
A retail company has over 3000 stores all using the same Point of Sale (POS) system. The company wants to deliver near real-time sales results to category managers. The stores operate in a variety of time zones and exhibit a dynamic range of transactions each minute, with some stores having higher sales volumes than others.
Sales results are provided in a uniform fashion using data engineered fields that will be calculated in a complex data pipeline. Calculations include exceptions, aggregations, and scoring using external functions interfaced to scoring algorithms. The source data for aggregations has over 100M rows.
Every minute, the POS sends all sales transactions files to a cloud storage location with a naming convention that includes store numbers and timestamps to identify the set of transactions contained in the files. The files are typically less than 10MB in size.
How can the near real-time results be provided to the category managers? (Select TWO).
Answer: A,E
Explanation:
To provide near real-time sales results to category managers, the Architect can use the following steps:
Create an external stage that references the cloud storage location where the POS sends the sales transactions files. The external stage should use the file format and encryption settings that match the source files2 Create a Snowpipe that loads the files from the external stage into a target table in Snowflake. The Snowpipe should be configured with AUTO_INGEST = true, which means that it will automatically detect and ingest new files as they arrive in the external stage. The Snowpipe should also use a copy option to purge the files from the external stage after loading, to avoid duplicate ingestion3 Create a stream on the target table that captures the INSERTS made by the Snowpipe. The stream should include the metadata columns that provide information about the file name, path, size, and last modified time. The stream should also have a retention period that matches the real-time analytics needs4 Create a task that runs a query on the stream to process the near real-time data. The query should use the stream metadata to extract the store number and timestamps from the file name and path, and perform the calculations for exceptions, aggregations, and scoring using external functions. The query should also output the results to another table or view that can be accessed by the category managers. The task should be scheduled to run at a frequency that matches the real-time analytics needs, such as every minute or every 5 minutes.
The other options are not optimal or feasible for providing near real-time results:
All files should be concatenated before ingestion into Snowflake to avoid micro-ingestion. This option is not recommended because it would introduce additional latency and complexity in the data pipeline. Concatenating files would require an external process or service that monitors the cloud storage location and performs the file merging operation. This would delay the ingestion of new files into Snowflake and increase the risk of data loss or corruption. Moreover, concatenating files would not avoid micro-ingestion, as Snowpipe would still ingest each concatenated file as a separate load.
An external scheduler should examine the contents of the cloud storage location and issue SnowSQL commands to process the data at a frequency that matches the real-time analytics needs. This option is not necessary because Snowpipe can automatically ingest new files from the external stage without requiring an external trigger or scheduler. Using an external scheduler would add more overhead and dependency to the data pipeline, and it would not guarantee near real-time ingestion, as it would depend on the polling interval and the availability of the external scheduler.
The copy into command with a task scheduled to run every second should be used to achieve the near-real time requirement. This option is not feasible because tasks cannot be scheduled to run every second in Snowflake. The minimum interval for tasks is one minute, and even that is not guaranteed, as tasks are subject to scheduling delays and concurrency limits. Moreover, using the copy into command with a task would not leverage the benefits of Snowpipe, such as automatic file detection, load balancing, and micro-partition optimization. Reference:
1: SnowPro Advanced: Architect | Study Guide
2: Snowflake Documentation | Creating Stages
3: Snowflake Documentation | Loading Data Using Snowpipe
4: Snowflake Documentation | Using Streams and Tasks for ELT
: Snowflake Documentation | Creating Tasks
: Snowflake Documentation | Best Practices for Loading Data
: Snowflake Documentation | Using the Snowpipe REST API
: Snowflake Documentation | Scheduling Tasks
: SnowPro Advanced: Architect | Study Guide
: Creating Stages
: Loading Data Using Snowpipe
: Using Streams and Tasks for ELT
: [Creating Tasks]
: [Best Practices for Loading Data]
: [Using the Snowpipe REST API]
: [Scheduling Tasks]
NEW QUESTION # 111
......
Real ARA-C01 Exam Dumps: https://www.exam4tests.com/ARA-C01-valid-braindumps.html
What's more, part of that Exam4Tests ARA-C01 dumps now are free: https://drive.google.com/open?id=1NI2vlbfClG9XLEbxmWO8b33rL7NlnrAR