VCETorrent is a good website for Microsoft certification DP-750 exams to provide short-term effective training. And VCETorrent can guarantee your Microsoft certification DP-750 exam to be qualified. If you don't pass the exam, we will take a full refund to you. Before you choose to buy the VCETorrent products before, you can free download part of the exercises and answers about Microsoft Certification DP-750 Exam as a try, then you will be more confident to choose VCETorrent's products to prepare your Microsoft certification DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
>> Test DP-750 Questions Answers <<
Although it is not an easy thing for somebody to pass the DP-750 exam, VCETorrent can help aggressive people to achieve their goals. More qualified DP-750 certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition. This is the reason why we need to recognize the importance of getting our DP-750 Quiz torrent. And with our DP-750 exam questions, you dream will be easy to come true.
NEW QUESTION # 51
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
Answer: B
Explanation:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
NEW QUESTION # 52
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: D
Explanation:
Schema evolution allows the target Delta table to incorporate compatible new source columns instead of failing when the incoming schema changes. This is the appropriate response to additive schema drift and avoids manually rebuilding tables whenever the source evolves. Creating a separate table for every schema version would fragment the dataset and increase operational effort. Disabling schema enforcement removes valuable protection against incompatible or corrupt data rather than handling legitimate evolution safely. Row filters operate on records and cannot remove an unexpected column from the incoming schema. With schema evolution enabled, the pipeline can detect new fields, update the target schema, and continue processing while retaining Delta Lake's transactional guarantees. The solution therefore supports changing source data without sacrificing the managed-table architecture.
NEW QUESTION # 53
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.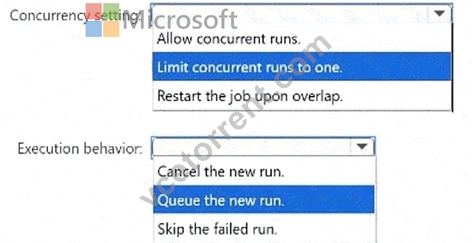
Answer:
Explanation: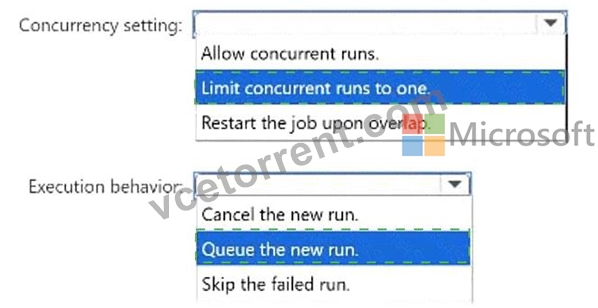
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 54
What improves join performance for small lookup tables?
Answer: D
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 55
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.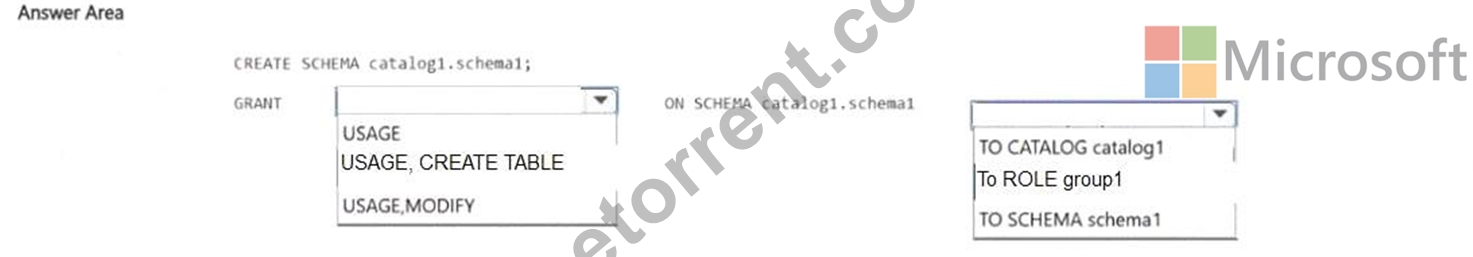
Answer:
Explanation: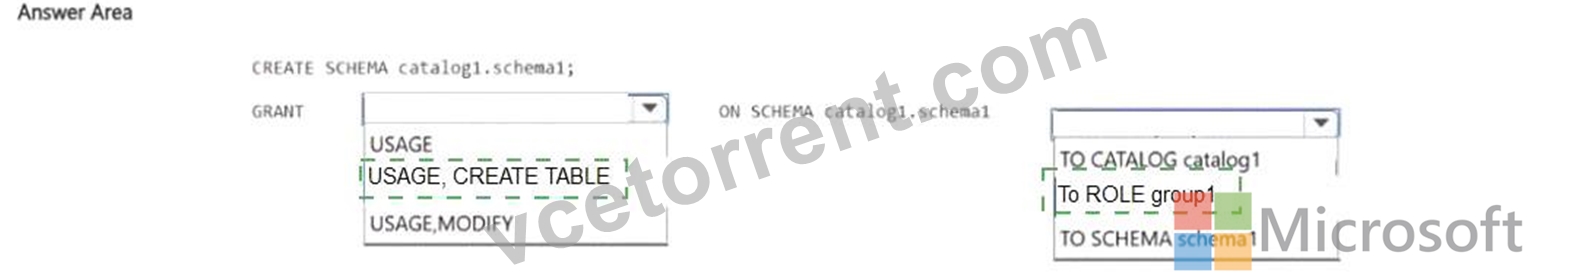
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 56
......
We take responses from thousands of experts globally while updating the DP-750 content of preparation material. Their feedback and reviews of successful applicants enable us to make our Microsoft DP-750 dumps material comprehensive for exam preparation purposes. This way we bring dependable and latest exam product which is enough to pass the Microsoft DP-750 certification test on the very first take.
Exam DP-750 Tests: https://www.vcetorrent.com/DP-750-valid-vce-torrent.html