高品質のAI-200の実際のテストと高い合格率のおかげで、当社はより速く、より速く開発され、世界で高い評価を得ています。教育の専門家は、試験問題とAI-200研究急流の回答の設計と研究に精通しています。さらに、最新のAI-200試験情報リソースをいつでも入手できます。学習ガイド資料には独自の利点があります。私たちの高い合格率は、この分野でトップの位置です。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 2: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 3: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 4: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
PassTestのMicrosoftのAI-200試験トレーニング資料を購入した後、君の受験のための知識をテストして、約束の時間での表現も評価します。PassTestの MicrosoftのAI-200試験トレーニング資料は高度に認証されたIT領域の専門家の経験と創造を含めているものです。そのけん異性は言うまでもありません。もし君はいささかな心配することがあるなら、あなたはうちの商品を購入する前に、PassTestは無料でサンプルを提供することができます。
質問 # 119
You develop an application that sells Al generated images based on user input. You recently started a marketing campaign that displays unique ads every second day.
Sales data is stored in Azure Cosmos 06 with the date of each sale being stored in a property named whenFinished ' . The marketing department requires a view that shows the number of sales grouped into two- day periods You need to implement the query for the view.
How should you complete the query? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point.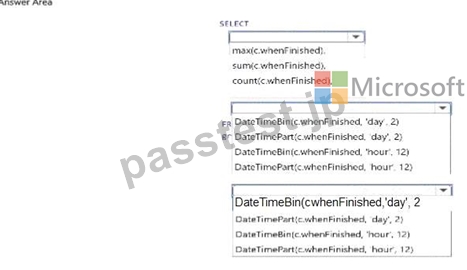
正解:
解説: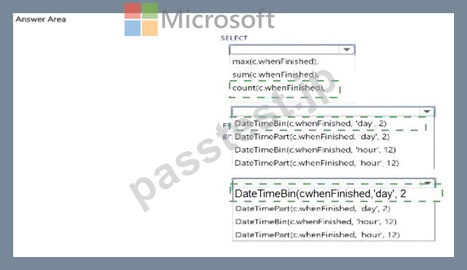
Explanation: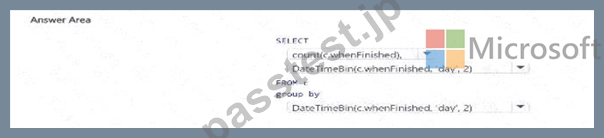
質問 # 120
Hotspot Question
You are implementing semantic retrieval in Redis.
The solution must support low-latency, approximate nearest neighbor (ANN) vector similarity search for large-scale AI retrieval workloads.
You need to select the appropriate vector schema settings.
Which configuration values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.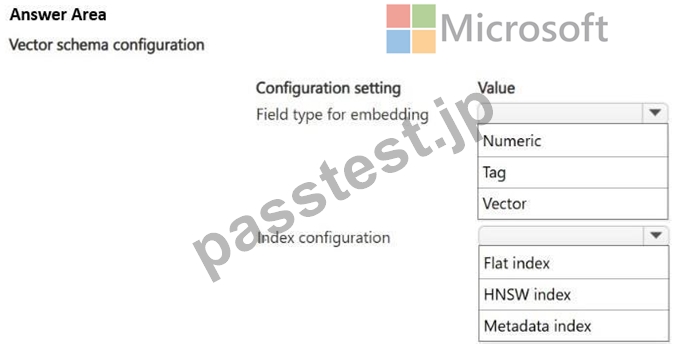
正解:
解説: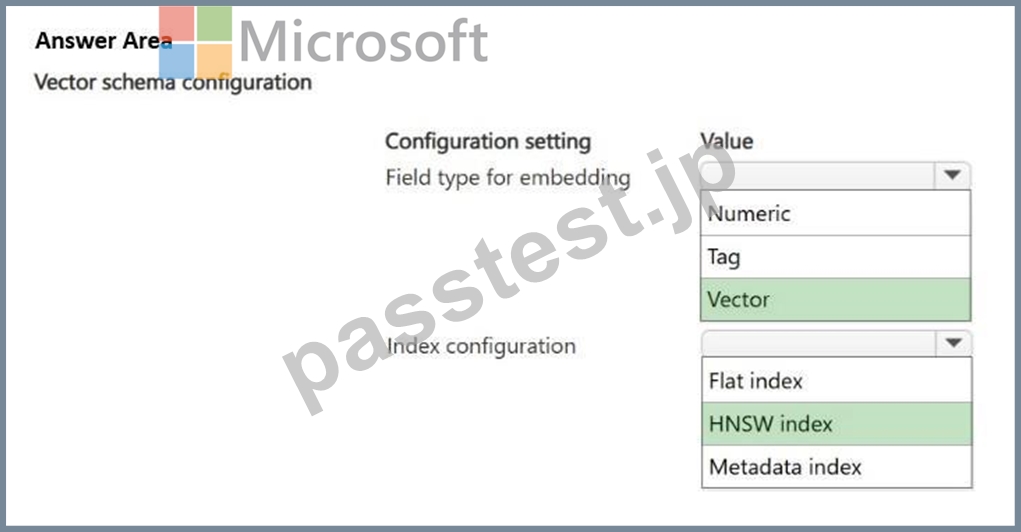
Explanation:
Box 1: Vector
The correct field type for storing and querying embeddings in Redis is VECTOR.
Box 2: HNSW index
To support low-latency, large-scale approximate nearest neighbor (ANN) vector search in Redis, you should use the HNSW (Hierarchical Navigable Small World) index type with Float32 data type.
Reference:
https://redis.io/docs/latest/develop/ai/search-and-query/vectors/
質問 # 121
You deploy a new revision of an app in Azure Container Apps.
You need to gradually shift production traffic to the revision while monitoring performance. In addition, you need to be able to quickly roll back. Which two actions should you perform?
Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
正解:C、D
解説:
Detailed Explanation: Gradual production rollout requires more than one revision to remain active and a mechanism to divide traffic between them. Multiple revision mode permits concurrent active revisions, and traffic splitting lets a specified percentage of requests flow to the new revision while the remainder stays on the proven revision. This also enables rapid rollback by returning traffic to the prior revision. Increasing replicas or restarting a revision changes capacity or process state, not release traffic distribution.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
質問 # 122
You are configuring an Azure-hosted AI application that uses Azure App Configuration to manage its runtime settings.
The application must provide the following functionality:
- Support percentage-based, targeted rollouts.
- Maximize token limits per request.
- Store a key that is retrieved securely at runtime.
- Reference a list of supported deployment regions.
You need to configure the App Configuration features for the app.
Which features should you configure? To answer, move the appropriate App Configuration features to the correct configuration items. You may use each App Configuration features once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.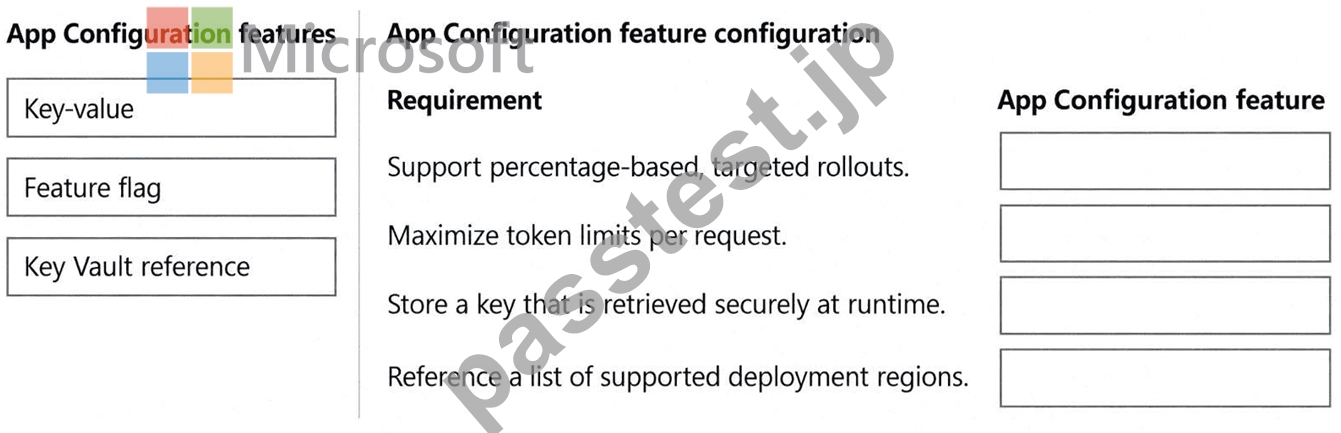
正解:
解説: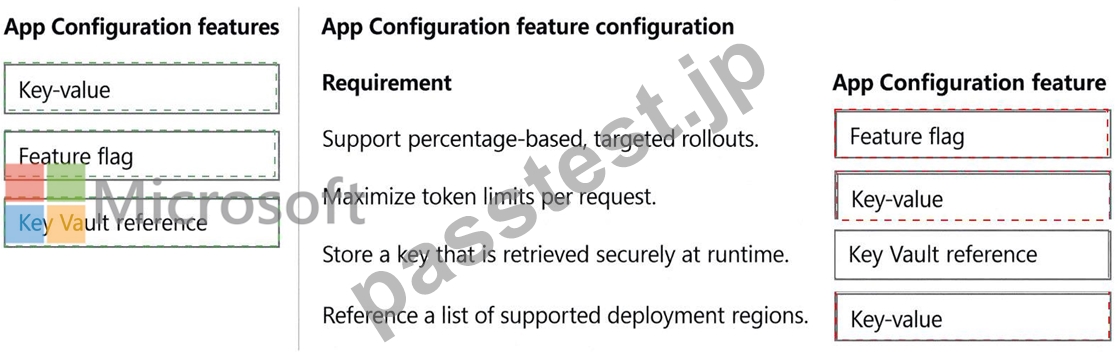
Explanation:
* Support percentage-based, targeted rollouts: Feature flag
* Maximize token limits per request: Key-value
* Store a key that is retrieved securely at runtime: Key Vault reference
* Reference a list of supported deployment regions: Key-value
Azure App Configuration provides three distinct mechanisms for these scenarios. A Feature flag is the correct choice for percentage-based and targeted rollouts. Feature Management supports conditional activation based on filters such as percentage allocation, users, groups, and other targeting criteria, making it appropriate for gradual deployment and controlled experimentation.
A Key-value is the correct mechanism for ordinary runtime configuration data such as a model token limit or a list of supported deployment regions. These values are application settings rather than secrets or feature- state controls. The application can retrieve and refresh them dynamically without redeployment. A token-limit setting such as MaxTokensPerRequest and a region list such as SupportedRegions fit naturally into App Configuration key-value entries.
For sensitive data, use a Key Vault reference . App Configuration stores only the reference to the Azure Key Vault secret rather than the secret value itself. At runtime, the application resolves the secret securely, typically by using a managed identity. This avoids embedding credentials or sensitive keys in configuration values.
Therefore, the correct mapping is Feature flag # Key-value # Key Vault reference # Key-value .
Study Guide references: Azure App Configuration # Feature Management; key-values; Key Vault references; dynamic application configuration.
質問 # 123
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.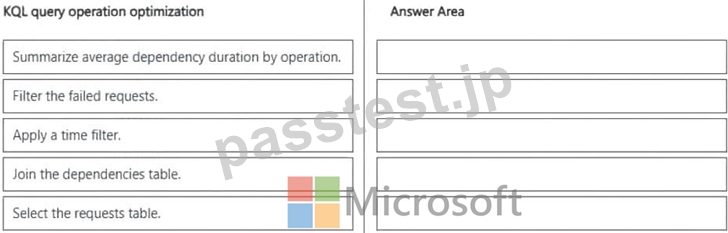
正解:
解説: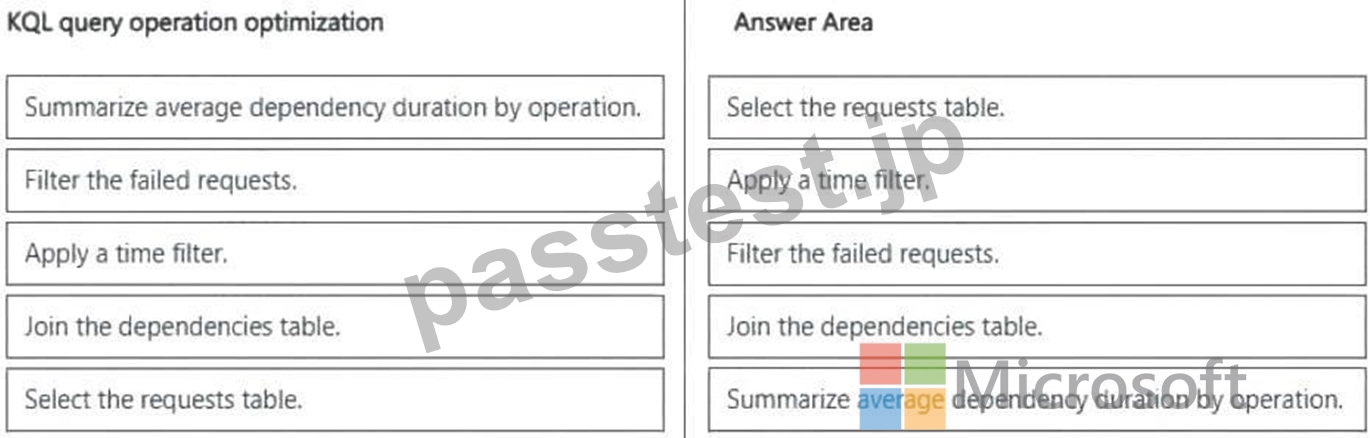
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
質問 # 124
......
献身と熱意を持ってAI-200ガイド資料を段階的に学習する場合、Microsoft必死に試験に合格することを保証します。学習資料の権威あるプロバイダーとして、潜在顧客からより多くの注目を集めるために、常に同等のテストと比較してAI-200模擬テストの高い合格率を追求しています。それ以外の場合、残念ながら、AI-200学習教材で試験に合格しなかった場合、製品費用はすぐに全額返金されます。 AI-200研究トレントは、高い合格率でより魅力的で素晴らしいものになります。
AI-200資格問題対応: https://www.passtest.jp/Microsoft/AI-200-shiken.html