BONUS!!! Download part of PracticeDump Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1cnM5LQxl7Q-OyR6-uU832IBCFTvxD6nL
Our Certified-Data-Engineer-Professional preparation exam can provide all customers with the After-sales service guarantee. The After-sales service guarantee is mainly reflected in our high-efficient and helpful service. We are glad to receive all your questions on our Certified-Data-Engineer-Professional Exam Dumps. If you have any questions about our Certified-Data-Engineer-Professional study questions, you have the right to answer us in anytime. Our online workers will solve your problem immediately after receiving your questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Topic 2: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 3: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
| Topic 4: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 5: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 6: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| Topic 7: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 8: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 9: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
>> Certified-Data-Engineer-Professional Reliable Dumps Ppt <<
PracticeDump has designed Databricks Certified-Data-Engineer-Professional pdf dumps format that is easy to use. Anyone can download the Databricks Certified-Data-Engineer-Professional pdf questions file and use it from any location or at any time. Databricks PDF Questions files can be used on laptops, tablets, and smartphones. Moreover, you will get actual Databricks Certified-Data-Engineer-Professional Pdf Dumps file.
NEW QUESTION # 189
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
Answer: D
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 190
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
Answer: E
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 191
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: D
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 192
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job: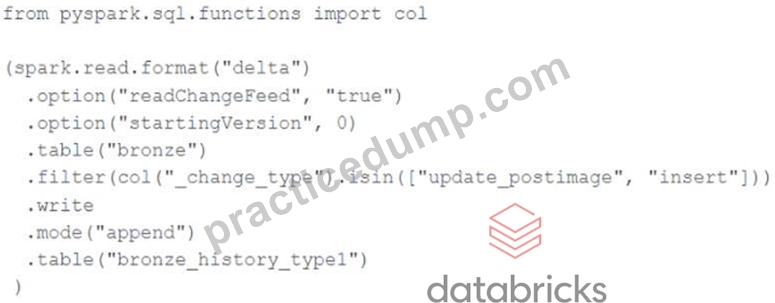
Which statement describes the execution and results of running the above query multiple times?
Answer: C
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 193
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights. Which privilege should be granted to the finance team lead?
Answer: A
Explanation:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs--far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 194
......
The development and progress of human civilization cannot be separated from the power of knowledge. You must learn practical knowledge to better adapt to the needs of social development. Now, our Certified-Data-Engineer-Professional learning materials can meet your requirements. You will have good command knowledge with the help of our study materials. The certificate is of great value in the job market. Our Certified-Data-Engineer-Professional Study Materials can exactly match your requirements and help you pass exams and obtain certificates. As you can see, our products are very popular in the market. Time and tides wait for no people.
Valid Certified-Data-Engineer-Professional Exam Pattern: https://www.practicedump.com/Certified-Data-Engineer-Professional_actualtests.html
BTW, DOWNLOAD part of PracticeDump Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1cnM5LQxl7Q-OyR6-uU832IBCFTvxD6nL