
BTW, DOWNLOAD part of TrainingDumps MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1U0q-lfNQowqC5pWTPjyzqHZCicakgYuA
TrainingDumps is a reputable and highly regarded platform that provides comprehensive preparation resources for the AWS Certified Machine Learning Engineer - Associate (MLA-C01). For years, TrainingDumps has been offering real, valid, and updated MLA-C01 Exam Questions, resulting in numerous successful candidates who now work for renowned global brands.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Reliable Exam Voucher <<
The best way of passing Amazon actual test is choosing accurate exam braindumps. TrainingDumps has latest test questions and accurate exam answers to ensure you clear MLA-C01 Real Exam. You just need spend your spare time to practice Amazon top questions and review the key points of study guide, it will be easy to clear exam.
NEW QUESTION # 98
A company wants to host an ML model on Amazon SageMaker. An ML engineer is configuring a continuous integration and continuous delivery (Cl/CD) pipeline in AWS CodePipeline to deploy the model. The pipeline must run automatically when new training data for the model is uploaded to an Amazon S3 bucket.
Select and order the pipeline's correct steps from the following list. Each step should be selected one time or not at all. (Select and order three.)
* An S3 event notification invokes the pipeline when new data is uploaded.
* S3 Lifecycle rule invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
* The pipeline deploys the model to SageMaker Model Registry.
Answer:
Explanation: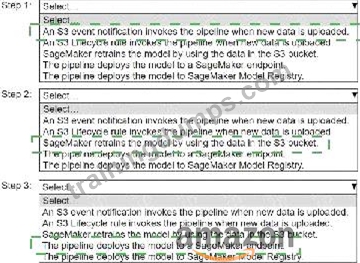
Explanation:
Step 1: An S3 event notification invokes the pipeline when new data is uploaded.Step 2: SageMaker retrains the model by using the data in the S3 bucket.Step 3: The pipeline deploys the model to a SageMaker endpoint.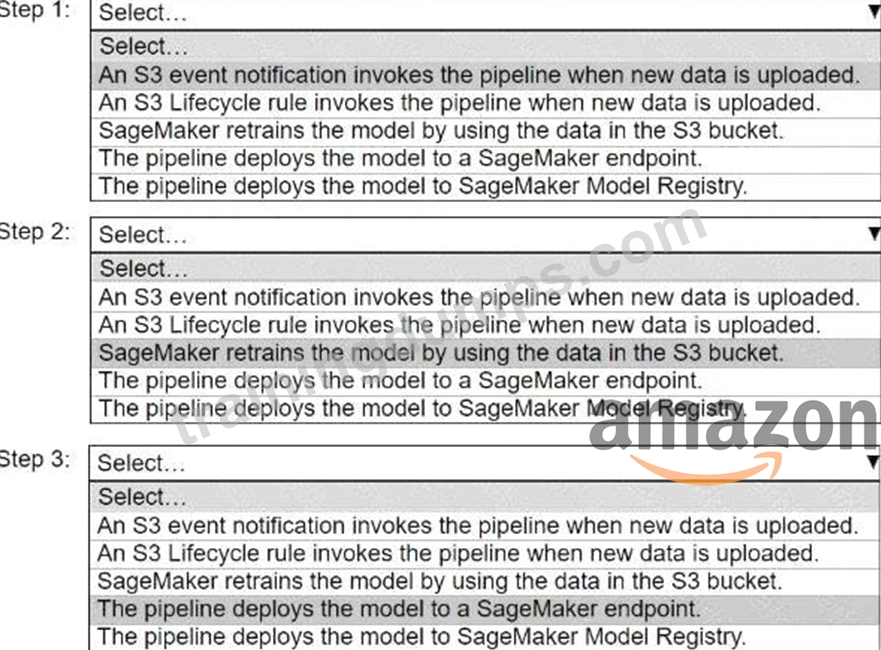
* Step 1: An S3 Event Notification Invokes the Pipeline When New Data is Uploaded
* Why?The CI/CD pipeline should be triggered automatically whenever new training data is uploaded to Amazon S3. S3 event notifications can be configured to send events to AWS services like Lambda, which can then invoke AWS CodePipeline.
* How?Configure the S3 bucket to send event notifications (e.g., s3:ObjectCreated:*) to AWS Lambda, which in turn triggers the CodePipeline.
* Step 2: SageMaker Retrains the Model by Using the Data in the S3 Bucket
* Why?The uploaded data is used to retrain the ML model to incorporate new information and maintain performance. This step is critical to updating the model with fresh data.
* How?Define a SageMaker training step in the CI/CD pipeline, which reads the training data from the S3 bucket and retrains the model.
* Step 3: The Pipeline Deploys the Model to a SageMaker Endpoint
* Why?Once retrained, the updated model must be deployed to a SageMaker endpoint to make it available for real-time inference.
* How?Add a deployment step in the CI/CD pipeline, which automates the creation or update of the SageMaker endpoint with the retrained model.
Order Summary:
* An S3 event notification invokes the pipeline when new data is uploaded.
* SageMaker retrains the model by using the data in the S3 bucket.
* The pipeline deploys the model to a SageMaker endpoint.
This configuration ensures an automated, efficient, and scalable CI/CD pipeline for continuous retraining and deployment of the ML model in Amazon SageMaker.
NEW QUESTION # 99
A company has an ML model in Amazon SageMaker AI. An ML engineer needs to implement a monitoring solution to automatically detect changes in the input data distribution of model features.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: B
Explanation:
Option A is correct because the requirement is to detect changes in the input data distribution of model features, which is a data quality / data drift monitoring problem. AWS documentation states that Amazon SageMaker Model Monitor uses rules to detect data drift and alerts you when it happens. The documented workflow is to enable data capture, create a baseline from training data, and then run monitoring jobs that compare incoming inference data against that baseline. That directly matches the need to automatically detect changes in feature distributions.
AWS also documents that Model Monitor can emit metrics to Amazon CloudWatch, and those metrics can be used with CloudWatch alarms to notify teams when data quality drifts beyond acceptable thresholds. That makes Option A the lowest-operational-overhead solution because it uses SageMaker's built-in monitoring capability plus managed alerting, rather than requiring custom drift logic. The inclusion of emit_metrics and CloudWatch alarming is consistent with the SageMaker monitoring pattern for automated notification.
The other options are weaker. Option B is for model quality monitoring, which focuses on prediction performance against ground truth, not shifts in the input feature distribution. Option C uses SageMaker Debugger, which is aimed at training-time debugging and custom rule analysis rather than managed production data drift monitoring. Option D relies on manual log analysis and endpoint performance metrics, which does not directly solve feature-distribution drift detection and adds more operational effort. Therefore, the best AWS-documented answer is A.
NEW QUESTION # 100
An ML engineer is setting up an Amazon SageMaker AI pipeline for an ML model. The pipeline must automatically initiate a re-training job if any data drift is detected.
How should the ML engineer set up the pipeline to meet this requirement?
Answer: B
Explanation:
AWS provides Amazon SageMaker Model Monitor as a native solution for detecting data drift and model quality issues in production ML pipelines. Model Monitor continuously analyzes incoming inference data and compares it with baseline training data to identify schema drift, feature distribution drift, and data quality anomalies.
When drift thresholds are violated, Model Monitor generates CloudWatch metrics and alerts. These alerts can directly trigger an AWS Lambda function, which can then programmatically initiate a SageMaker retraining job or start a SageMaker Pipeline execution. This design is explicitly documented by AWS as the recommended architecture for automated retraining workflows.
Option A is incorrect because AWS Glue is a data integration service and does not provide ML-specific drift detection capabilities.
Option B is incorrect because Apache Flink is designed for stream processing, not ML data drift detection.
Option D is incorrect because Amazon QuickSight anomaly detection is intended for business intelligence metrics, not ML feature drift.
Therefore, using SageMaker Model Monitor with AWS Lambda automation is the correct, AWS-native solution for drift-driven retraining.
NEW QUESTION # 101
A company is building a near real-time data analytics application to detect anomalies and failures for industrial equipment. The company has thousands of IoT sensors that send data every 60 seconds. When new versions of the application are released, the company wants to ensure that application code bugs do not prevent the application from running.
Which solution will meet these requirements?
Answer: C
Explanation:
For near real-time anomaly detection on streaming IoT data, AWS recommends Amazon Managed Service for Apache Flink. Flink is designed for stateful, low-latency stream processing and is well suited for time- series sensor analytics.
A key requirement is application resilience during deployments. Managed Flink supports system rollback, which automatically reverts to the last stable application version if a new deployment fails. This capability ensures uninterrupted processing even if application bugs are introduced, meeting the company's reliability requirement.
Manual rollback (Option B) introduces operational risk and delays. Amazon Data Firehose (Options C and D) is a delivery service and does not support complex anomaly detection logic or application version rollback.
Therefore, using Managed Flink with system rollback enabled is the correct solution.
NEW QUESTION # 102
A company has an ML model that is deployed to an Amazon SageMaker endpoint for real-time inference. The company needs to deploy a new model. The company must compare the new model's performance to the currently deployed model's performance before shifting all traffic to the new model. Which solution will meet these requirements with the LEAST operational effort?
Answer: B
Explanation:
SageMaker supports shadow variant deployments, which allow a new model to run alongside the current one on the same endpoint. A portion of live traffic is mirrored to the shadow model for evaluation, while only the current model's output is returned to users. This provides the required comparison with minimal operational effort, avoiding the need for custom traffic-splitting solutions.
NEW QUESTION # 103
......
With the high pass rate of our MLA-C01 exam questions as 98% to 100%, we can proudly claim that we are unmatched in the market for our accurate and latest MLA-C01 exam torrent. You will never doubt about our strength on bringing you success and the according certification that you intent to get. We have testified more and more candidates’ triumph with our MLA-C01 practice materials. We believe you will be one of the winners like them. Just buy our MLA-C01 study material and you will have a brighter future.
MLA-C01 Testking Exam Questions: https://www.trainingdumps.com/MLA-C01_exam-valid-dumps.html
BONUS!!! Download part of TrainingDumps MLA-C01 dumps for free: https://drive.google.com/open?id=1U0q-lfNQowqC5pWTPjyzqHZCicakgYuA