AI-200学習ツールの魂としての「信頼できる信用」、経営理念としての「最大限のサービス意識」により、高品質のサービスをお客様に提供するよう努めています。あなたの小さなヘルパーになり、AI-200認定テストに関するご質問にお答えするサービススタッフは、すべてのユーザーとの包括的で調整された持続可能な協力関係を目指します。 AI-200テストトレントに関するパズルは、タイムリーで効果的な応答を受け取ります。公式ウェブサイトにメッセージを残すか、都合の良いときにメールを送信してください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 2: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 3: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 4: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
当社Microsoftは、AI-200試験問題を編集するために、この分野で多くの主要な専門家を採用しています。 当社のチームベースの作業システムは、次世代の最高のAI-200試験トレントがTech4Exam最終的に形を成し遂げる精神と手を携える人材を最大限に引き出すように設計されています。 当社は、優れたアフターサービスを提供し、ガイドの急流に革新をもたらした実績があります。 当社の専門家がお客様に世界クラスのAI-200のDeveloping AI Cloud Solutions on Azureガイドトレントを作成できるため、お客様の成功が保証されます。 AI-200試験に合格する必要があります。
質問 # 87
You are developing an Azure Function that calls external APIs by providing an access token for the API. The access token is stored in a secret named token in an Azure Key Vault named mykeyvault. You need to ensure the Azure Function can access the token. Which value should you store in the Azure Functions app configuration?
正解:D
解説:
To securely provide the Azure Function with access to the secret without exposing it in the application code, you should store a Key Vault reference syntax in the Azure Functions app configuration settings.
The exact value you must store depends on whether you wish to target the latest version of the secret automatically or a specific, pinned version.
Target the latest version (Recommended)
Use this syntax to ensure your Function App always fetches the most recent version of the token:
@Microsoft.KeyVault(VaultName= mykeyvault;SecretName=token)
Reference:
https://learn.microsoft.com/en-us/azure/key-vault/general/apps-api-keys-secrets
質問 # 88
You deploy a new revision of an app in Azure Container Apps.
You need to gradually shift production traffic to the revision while monitoring performance. In addition, you need to be able to quickly roll back. Which two actions should you perform?
Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
正解:B、C
解説:
Detailed Explanation: Gradual production rollout requires more than one revision to remain active and a mechanism to divide traffic between them. Multiple revision mode permits concurrent active revisions, and traffic splitting lets a specified percentage of requests flow to the new revision while the remainder stays on the proven revision. This also enables rapid rollback by returning traffic to the prior revision. Increasing replicas or restarting a revision changes capacity or process state, not release traffic distribution.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
質問 # 89
You plan to deploy an Azure Container app.
You need to configure the container app to support session affinity.
Which ingress type and revision mode should you assign to the container app?
正解:B
解説:
Azure Container Apps session affinity, also called sticky sessions , routes requests from the same client to the same container-app replica. Microsoft documents that this functionality is implemented using HTTP cookies
, so it requires HTTP ingress rather than raw TCP ingress.
The second requirement is single revision mode . Microsoft explicitly states that session affinity is supported only when the container app is in single revision mode and HTTP ingress is enabled . In single revision mode, all traffic is directed to the latest active revision, allowing the ingress layer to consistently associate a client with a particular replica within that revision.
Multiple revision mode is designed for scenarios such as traffic splitting, blue-green deployments, and A/B testing, where inbound traffic can be distributed among multiple active revisions. That model is incompatible with the documented session-affinity restriction. TCP ingress is also incorrect because sticky-session behavior relies on HTTP cookie affinity rather than generic TCP connection routing.
Therefore, the required configuration is HTTP ingress with single revision mode .
Study Guide references: Azure Container Apps # ingress; sticky sessions/session affinity; revision modes; HTTP routing.
質問 # 90
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet. What should you configure?
正解:A
質問 # 91
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.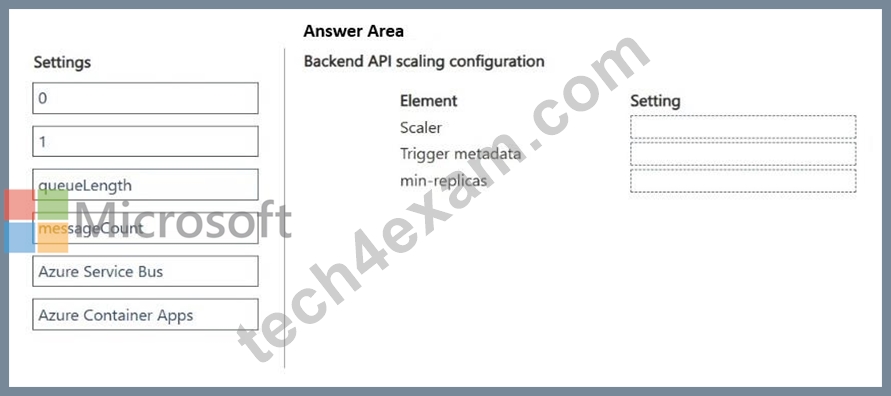
正解:
解説: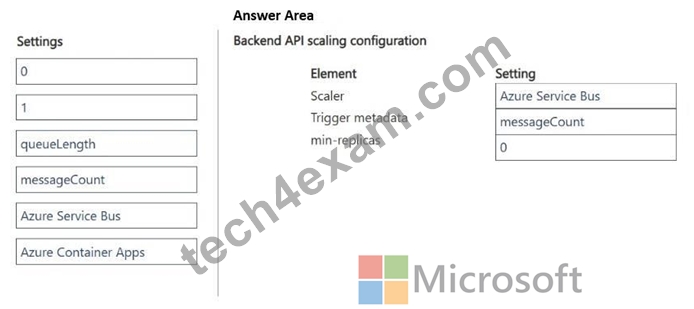
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
質問 # 92
......
まだどうのようにMicrosoft AI-200資格認定試験にパースすると煩悩していますか。現時点で我々サイトTech4Examを通して、ようやくこの問題を心配することがありませんよ。Tech4Examは数年にわたりMicrosoft AI-200資格認定試験の研究に取り組んで、量豊かな問題庫があるし、豊富な経験を持ってあなたが認定試験に効率的に合格するのを助けます。AI-200資格認定試験に合格できるかどうかには、重要なのは正確の方法で、復習教材の量ではありません。だから、Tech4ExamはあなたがMicrosoft AI-200資格認定試験にパースする正確の方法です。
AI-200問題数: https://www.tech4exam.com/AI-200-pass-shiken.html