P.S.JpexamがGoogle Driveで共有している無料の2026 Microsoft DP-600ダンプ:https://drive.google.com/open?id=1xRWCyPmQ3wN2-dZSoq2T-GHKsEgLdee4
Jpexam理想の仕事を見つけることができず、低賃金が得られないことをまだ心配していますか? DP-600認定の取得を試みることができます。DP-600試験に合格すると、高収入で良い仕事を見つける可能性が高くなります。トレントのDP-600の質問を購入すると、簡単かつ正常に試験に合格します。 DP-600学習教材は専門家によって編集され、長年の経験を持つ専門家によって承認されています。 DP-600試験問題の質が高いため、DP-600試験に簡単に合格できます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
第一に、当社は常に優秀なDP-600学習ガイドと卓越した技術で受験者にフィードバックし、最も専門的な試験教材を継続的に開発しています。第二に、当社のDP-600学習資料は、最新のサービス指向システムの作成に固執し、お客様の便宜のためにより優先的な活動を提供するよう努めています。最後になりましたが、以下のように、無料のデモがあります。次のように、どのDP-600試験資料デモをダウンロードして選択することができます。したがって、あなたは私たちのDP-600学習資料を愛するでしょう!
質問 # 11
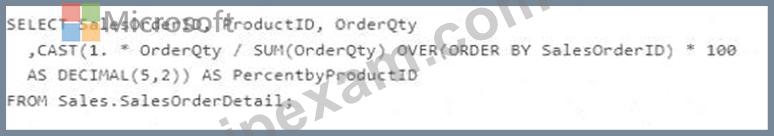
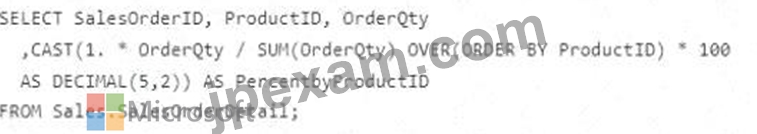
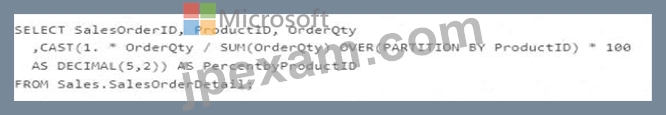
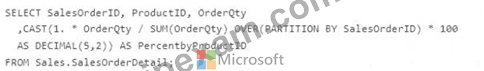
You have a Fabric warehouse that contains a table named SalesOrderDetail. SalesOrderDetail contains three columns named OrderQty, ProductID and SalesOrderlD. SalesOrderDetail contains one row per combination of SalesOrderlD and ProductID.
You need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Which T-SQL statement should you run?
正解:D
解説:
Comprehensive Detailed Explanation
We need to calculate the proportion of the total quantity of each sales order represented by each product within the sales order.
Step 1: Analyze the requirement
Table: SalesOrderDetail
Columns: OrderQty, ProductID, SalesOrderID
Each row = one product in a sales order.
Requirement: For each SalesOrderID, calculate what percentage each product contributes to the total order quantity.
This means we must:
Calculate the total order quantity per SalesOrderID.
Divide each product's OrderQty by that total.
Express it as a percentage.
Step 2: Evaluate the options
A). Uses OVER(ORDER BY ProductID)
Wrong: ORDER BY does not segment data, it only defines sequence. We need grouping by sales order.
B). Uses OVER(PARTITION BY ProductID)
Wrong: This would calculate percentages per product across all sales orders, not per sales order.
C). Uses OVER(PARTITION BY SalesOrderID)
Correct: This computes the total OrderQty per SalesOrderID and divides each product's quantity by that total.
Exactly what the requirement asks.
D). Uses OVER(ORDER BY SalesOrderID)
Wrong: Again, ORDER BY just sequences rows, does not group them.
Step 3: Correct Query
SELECT
SalesOrderID,
ProductID,
OrderQty,
CAST(1. * OrderQty / SUM(OrderQty)
OVER(PARTITION BY SalesOrderID) * 100 AS DECIMAL(5,2))
AS PercentByProductID
FROM Sales.SalesOrderDetail;
Why Option C is Correct
PARTITION BY SalesOrderID ensures the denominator is the total quantity for the current order.
This produces the correct percentage breakdown of each product inside its sales order.
References
T-SQL Window Functions
Aggregate Functions with PARTITION BY
Microsoft Fabric Warehouse T-SQL Support
質問 # 12
You have a Microsoft Power B1 Premium Per User (PPU) workspace that contains a semantic model.
You have an Azure App Service app named App1 that modifies row-level security (RLS) for the model by using the XMLA endpoint. App1 requires users to sign in by using their Microsoft Entra credentials to access the XMLA endpoint. You need to configure App1 to use a service account to access the model. What should you do first?
正解:D
解説:
Power BI Premium Per User (PPU) already supports XMLA read/write. You don't need to upgrade to Premium capacity.
The workspace itself does not get a managed identity; rather, App1 (Azure App Service) can be configured with a managed identity.
Once App1 has a managed identity, you grant it access to the Power BI model in the workspace via XMLA endpoint.
Modifying the XMLA endpoint setting is not sufficient; authentication must come from the service (App1).
Correct answer: B.
Reference: Service principals and managed identities for Power BI XMLA
質問 # 13
You have a Microsoft Power Bl semantic model that contains a single table named Orders. Orders contains the following columns:
* Product Name
* Order Date
* Quantity
You have a Power Bl report that contains a page named Inventory. Inventory contains a slicer for the Product Name column and a clustered column chart that shows Quantity by Order Date.
You need to ensure that users can select whether to display Quantity by Product Name or Quantity by Order Date in the chart. The solution must minimize development effort.
What should you create?
正解:B
質問 # 14
You have a Fabric tenant that contains lakehouse named Lakehousel. Lakehousel contains a Delta table with eight columns. You receive new data that contains the same eight columns and two additional columns.
You create a Spark DataFrame and assign the DataFrame to a variable named df. The DataFrame contains the new data. You need to add the new data to the Delta table to meet the following requirements:
* Keep all the existing rows.
* Ensure that all the new data is added to the table.
How should you complete the code? To answer, select the appropriate options in the answer area.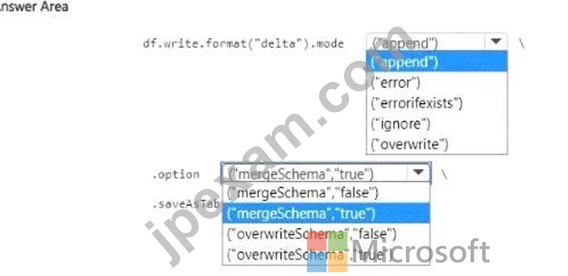
正解:
解説: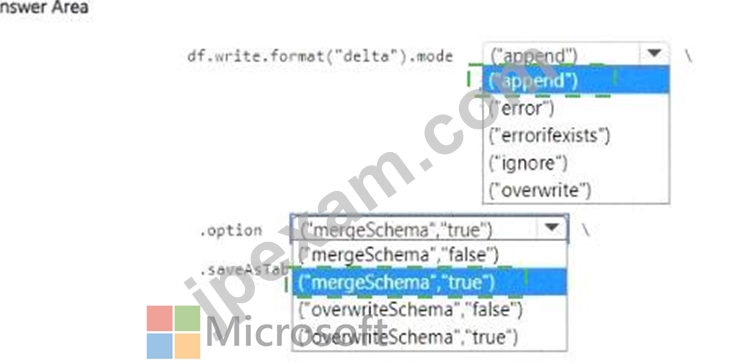
Explanation: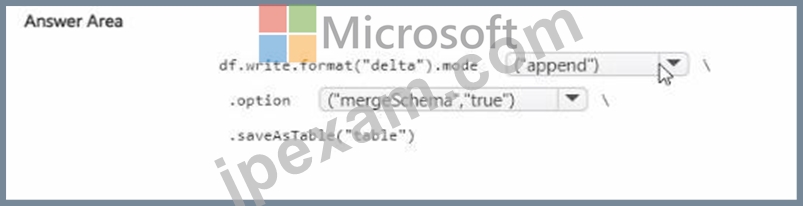
o add new data to the Delta table while meeting the specified requirements:
* You should use the append mode to ensure that all new data is added to the table without affecting the existing rows.
* You should set the mergeSchema option to true to allow the schema of the Delta table to be updated with the new columns found in the DataFrame.
The completed code would look like this:
df.write.format("delta").mode("append")
option("mergeSchema", "true")
saveAsTable("Lakehouse1.TableName")
質問 # 15
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.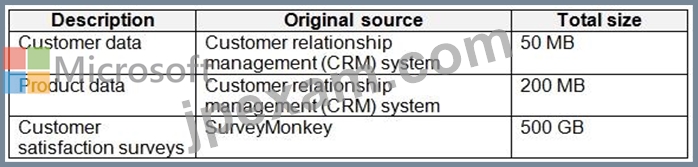
The Product data contains a single table and the following columns.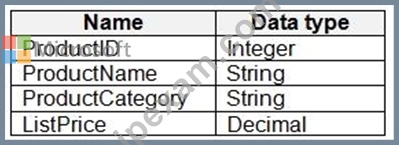
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
What should you recommend using to ingest the customer data into the data store in the AnalyticsPOC workspace?
正解:C
解説:
Even though the text reads "Data will be loaded without transformation in one area of the AnalyticsPOC data store": in general, dataflows are used when data transformations are involved after ingestion. As suggested by user BHARAT, the Copy Activity should be the optimal solution.
質問 # 16
......
献身と熱意を持ってDP-600ガイド資料を段階的に学習する場合、Microsoft必死に試験に合格することを保証します。学習資料の権威あるプロバイダーとして、潜在顧客からより多くの注目を集めるために、常に同等のテストと比較してDP-600模擬テストの高い合格率を追求しています。それ以外の場合、残念ながら、DP-600学習教材で試験に合格しなかった場合、製品費用はすぐに全額返金されます。 DP-600研究トレントは、高い合格率でより魅力的で素晴らしいものになります。
DP-600試験復習: https://www.jpexam.com/DP-600_exam.html
無料でクラウドストレージから最新のJpexam DP-600 PDFダンプをダウンロードする:https://drive.google.com/open?id=1xRWCyPmQ3wN2-dZSoq2T-GHKsEgLdee4