BTW, DOWNLOAD part of Pass4suresVCE Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1-5srqgXqTBYtKTCLAdl7XJUpud_fyN8G
We offer three different formats for preparing for the Google Professional-Machine-Learning-Engineer exam questions, all of which will ensure your definite success on your Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps. Pass4suresVCE is there with updated Professional-Machine-Learning-Engineer Questions so you can pass the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam and move toward the new era of technology with full ease and confidence.
| Section | Objectives |
|---|---|
| Monitoring ML solutions | - Performance monitoring and drift detection - Model retraining strategies - Logging and alerting (Cloud Monitoring) |
| Architecting low-code ML solutions | - AutoML capabilities and implementation - Implementing BigQuery ML for basic models - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) |
| Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) - Batch prediction |
| Scaling prototypes into ML models | - Training at scale (Distributed training, TPUs) - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Data management and governance |
>> Official Professional-Machine-Learning-Engineer Practice Test <<
Remember that this is a crucial part of your career, and you must keep pace with the changing time to achieve something substantial in terms of a certification or a degree. So do avail yourself of this chance to get help from our exceptional Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) dumps to grab the most competitive Google Professional-Machine-Learning-Engineer certificate. Pass4suresVCE has formulated the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) product in three versions. You will find their specifications below to understand them better.
NEW QUESTION # 279
You work for a food product company. Your company's historical sales data is stored in BigQuery You need to use Vertex Al's custom training service to train multiple TensorFlow models that read the data from BigQuery and predict future sales You plan to implement a data preprocessing algorithm that performs min- max scaling and bucketing on a large number of features before you start experimenting with the models. You want to minimize preprocessing time, cost and development effort How should you configure this workflow?
Answer: B
Explanation:
The best option for configuring the workflow is to add the transformations as a preprocessing layer in the TensorFlow models. This option allows you to leverage the power and simplicity of TensorFlow to preprocess and transform the data with simple Python code. TensorFlow is a framework for building and training machine learning models. TensorFlow provides various tools and libraries for data analysis and machine learning. A preprocessing layer is a type of layer in TensorFlow that can perform data preprocessing and feature engineering operations on the input data. A preprocessing layer can help you customize the data transformation and preprocessing logic, and handle complex or non-standard data formats. A preprocessing layer can also help you minimize the preprocessing time, cost, and development effort, as you only need to write a few lines of code to implement the preprocessing layer, and you do not need to create any intermediate data sources or pipelines. By adding the transformations as a preprocessing layer in the TensorFlow models, you can use Vertex AI's custom training service to train multiple TensorFlow models that read the data from BigQuery and predict future sales1.
The other options are not as good as option C, for the following reasons:
* Option A: Writing the transformations into Spark that uses the spark-bigquery-connector and using Dataproc to preprocess the data would require more skills and steps than using a preprocessing layer in TensorFlow. Spark is a framework for distributed data processing and machine learning. Spark can read and write data from BigQuery by using the spark-bigquery-connector, which is a library that allows Spark to communicate with BigQuery. Dataproc is a service that can create and manage Spark clusters on Google Cloud. Dataproc can help you run Spark jobs on Google Cloud, and scale the clusters according to the workload. However, writing the transformations into Spark that uses the spark- bigquery-connector and using Dataproc to preprocess the data would require more skills and steps than using a preprocessing layer in TensorFlow. You would need to write code, create and configure the Spark cluster, install and import the spark-bigquery-connector, load and preprocess the data, and write the data back to BigQuery. Moreover, this option would create an intermediate data source in BigQuery, which can increase the storage and computation costs2.
* Option B: Writing SQL queries to transform the data in-place in BigQuery would not allow you to use Vertex AI's custom training service to train multiple TensorFlow models that read the data from BigQuery and predict future sales. BigQuery is a service that can perform data analysis and machine learning by using SQL queries. BigQuery can perform data transformation and preprocessing by using SQL functions and clauses, such as MIN, MAX, CASE, and TRANSFORM. BigQuery can also perform machine learning by using BigQuery ML, which is a feature that can create and train machine learning models by using SQL queries. However, writing SQL queries to transform the data in-place in BigQuery would not allow you to use Vertex AI's custom training service to train multiple TensorFlow models that read the data from BigQuery and predict future sales. Vertex AI's custom training service is a service that can run your custom machine learning code on Vertex AI. Vertex AI's custom training service can support various machine learning frameworks, such as TensorFlow, PyTorch, and scikit- learn. Vertex AI's custom training service cannot support SQL queries, as SQL is not a machine learning framework. Therefore, if you want to use Vertex AI's custom training service, you cannot use SQL queries to transform the data in-place in BigQuery3.
* Option D: Creating a Dataflow pipeline that uses the BigQueryIO connector to ingest the data, process it, and write it back to BigQuery would require more skills and steps than using a preprocessing layer in TensorFlow. Dataflow is a service that can create and run data processing and machine learning pipelines on Google Cloud. Dataflow can read and write data from BigQuery by using the BigQueryIO connector, which is a library that allows Dataflow to communicate with BigQuery. Dataflow can perform data transformation and preprocessing by using Apache Beam, which is a framework for distributed data processing and machine learning. However, creating a Dataflow pipeline that uses the BigQueryIO connector to ingest the data, process it, and write it back to BigQuery would require more skills and steps than using a preprocessing layer in TensorFlow. You would need to write code, create and configure the Dataflow pipeline, install and import the BigQueryIO connector, load and preprocess the data, and write the data back to BigQuery. Moreover, this option would create an intermediate data source in BigQuery, which can increase the storage and computation costs4.
References:
* Preparing for Google Cloud Certification: Machine Learning Engineer, Course 3: Production ML Systems, Week 2: Serving ML Predictions
* Google Cloud Professional Machine Learning Engineer Exam Guide, Section 2: Developing ML models, 2.1 Developing ML models by using TensorFlow
* Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 4:
Developing ML Models, Section 4.1: Developing ML Models by Using TensorFlow
* TensorFlow Preprocessing Layers
* Spark and BigQuery
* Dataproc
* BigQuery ML
* Dataflow and BigQuery
* Apache Beam
NEW QUESTION # 280
You work for a large retailer, and you need to build a model to predict customer chum. The company has a dataset of historical customer data, including customer demographics purchase history, and website activity. You need to create the model in BigQuery ML and thoroughly evaluate its performance. What should you do?
Answer: B
NEW QUESTION # 281
You need to develop a custom TensorFlow model that will be used for online predictions. The training data is stored in BigQuery You need to apply instance-level data transformations to the data for model training and serving. You want to use the same preprocessing routine during model training and serving. How should you configure the preprocessing routine?
Answer: C
NEW QUESTION # 282
You need to develop a custom TensorRow model that will be used for online predictions. The training data is stored in BigQuery. You need to apply instance-level data transformations to the data for model training and serving. You want to use the same preprocessing routine during model training and serving. How should you configure the preprocessing routine?
Answer: B
NEW QUESTION # 283
You trained a text classification model. You have the following SignatureDefs: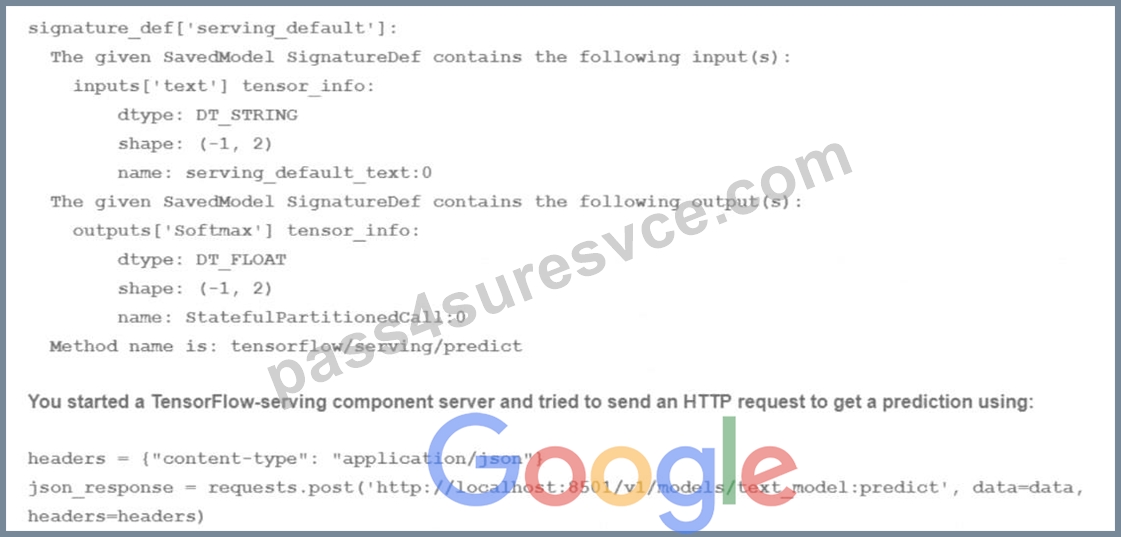
What is the correct way to write the predict request?
Answer: B
Explanation:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model.
A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
NEW QUESTION # 284
......
To ensure a more comfortable experience for users of Professional-Machine-Learning-Engineer test material, we offer a thoughtful package. Not only do we offer free demo services before purchase, we also provide three learning modes of Professional-Machine-Learning-Engineer learning guide for users. With easy payment and thoughtful, intimate after-sales service, believe that our Professional-Machine-Learning-Engineer Exam Guide Materials will not disappoint users. Last but not least, our worldwide service after-sale staffs will provide the most considerable and comfortable suggestion on Professional-Machine-Learning-Engineer study prep for you in twenty -four hours a day, as well as seven days a week incessantly.
Professional-Machine-Learning-Engineer Best Study Material: https://www.pass4suresvce.com/Professional-Machine-Learning-Engineer-pass4sure-vce-dumps.html
BTW, DOWNLOAD part of Pass4suresVCE Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1-5srqgXqTBYtKTCLAdl7XJUpud_fyN8G