What happens when you are happiest? It must be the original question! The hit rate of SPS-C01 study materials has been very high for several reasons. Our company has collected the most comprehensive data and hired the most professional experts to organize. They are the most authoritative in this career. At the same time, we are very concerned about social information and will often update the content of our SPS-C01 Exam Questions.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Window functions - Using built-in functions - Complex data pipelines |
| Snowpark Concepts | 15% | - Stored procedures and conditional logic - Client-side vs. Server-side execution - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Transformations vs. Actions |
| Performance Optimization and Best Practices | 20% | - Minimizing data transfer - Debugging and explain plans - Caching strategies - Query pushdown and optimization - Warehouse sizing for Snowpark - Vectorized UDFs |
| Snowpark API for Python | 30% | - Reading and writing data - Establishing connections and session management - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data |
In a rapidly growing world, it is immensely necessary to tag your potential with the best certifications, such as the SPS-C01 certification. But as you may be busy with your work or other matters, it is not easy for you to collect all the exam information and pick up the points for the SPS-C01 Exam. Our professional experts have done all the work for you with our SPS-C01 learning guide. You will pass the exam in the least time and with the least efforts.
NEW QUESTION # 95
You are developing a Snowpark Python application that needs to process large datasets. You want to optimize performance by leveraging user-defined functions (UDFs) to perform complex calculations in parallel across the Snowflake data warehouse. Which of the following statements regarding Snowpark UDFs are TRUE?
Answer: C,E
Explanation:
Snowpark UDFs can be either scalar or vectorized, offering different performance tradeoffs. Vectorized UDFs are generally more efficient for large datasets as they process batches of rows. Snowpark UDFs do distribute the data and computation across multiple nodes automatically; however, the distribution strategy, while not directly controlled, is influenced by how the UDF is applied to the data and the inherent distribution of the underlying data itself. Python is the primary UDF language. Option A is false because UDFs are designed for parallel processing. Option C is not always true; custom channels might be necessary for specific dependencies. Option E is partially correct in the older releases but Python is used primarily now.
NEW QUESTION # 96
You are tasked with optimizing a Snowpark application that performs sentiment analysis on customer reviews using a Python UDE The UDF uses a large pre-trained natural language processing (NLP) model stored in a file named 'sentiment_model.pkl'. The current implementation loads the model from the stage for each row of data processed, which is impacting performance. How can you optimize the application to load the model only once per worker process?
Answer: C
Explanation:
Option B offers the most straightforward and efficient solution. By utilizing a global variable and loading the model only if it's 'None' , the model is loaded only once per worker process. The 'imports' clause ensures the model file is accessible to the UDF. Caching via '@cache' (A) might not work correctly with serialization/deserialization across processes. (C) pre imports at the session level but cache control is still missing. passing as parameter (D) doesn't address model only loads once per worker. (E) This technique is not directly supported for achieving per-worker initialization in standard Snowpark UDFs, making B a better and more commonly used approach.
NEW QUESTION # 97
You are working with a Snowpark DataFrame containing customer data'. One of the columns, 'phone number', contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize all phone numbers to the format '+1-123-456-7890' using Snowpark for Python. You also want to handle cases where the phone number is NULL gracefully, replacing them with '+1-000-000-0000'. Which of the following Snowpark code snippets is the most efficient and correct way to achieve this?
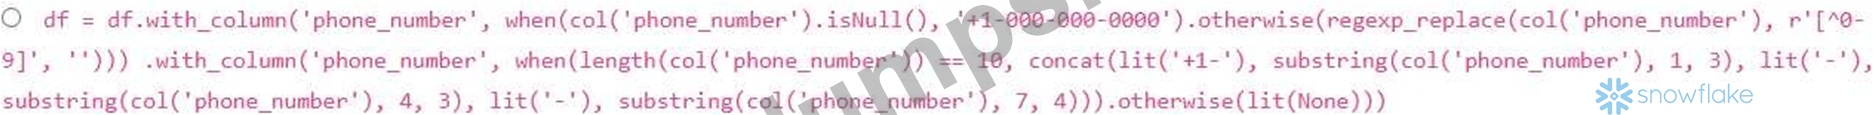


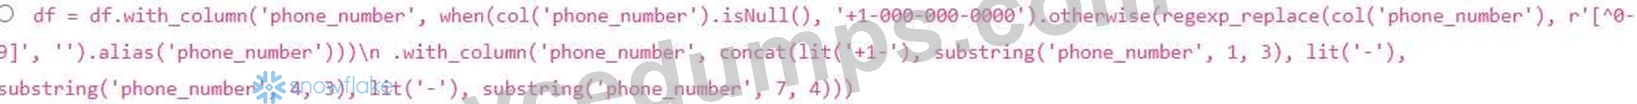

Answer: A
Explanation:
Option C is the most efficient because it uses built-in Snowpark functions (when, regexp_replace, substring, concat, length, and lit) to perform the transformation directly on the server-side. It first handles NULL values. It then removes non-numeric characters. Finally, it checks the length of the remaining digits before formatting, ensuring only valid 10-digit numbers are transformed, setting others to NULL. Options A, D, and E do not handle the case where after removing non-numeric characters, the length of phone number is not 10. Option B uses a UDF, which is generally less efficient than using built-in functions as it involves serialization/deserialization overhead .
NEW QUESTION # 98
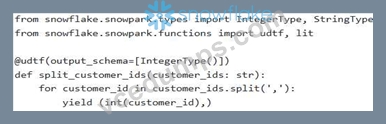
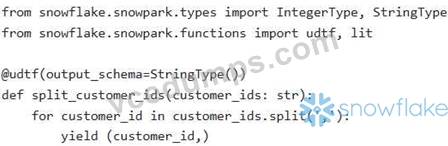
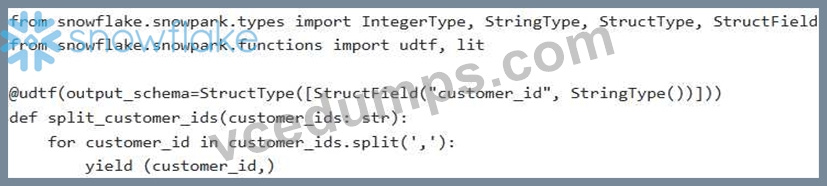
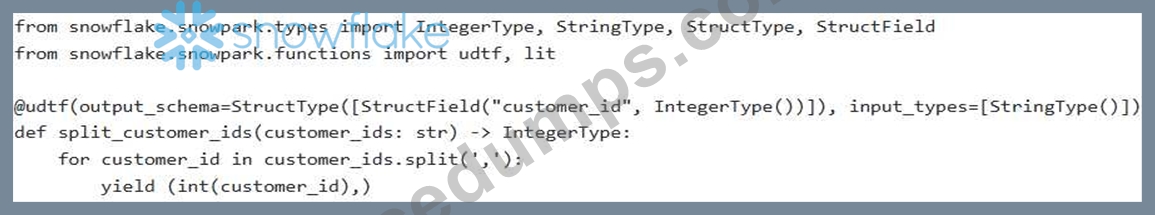
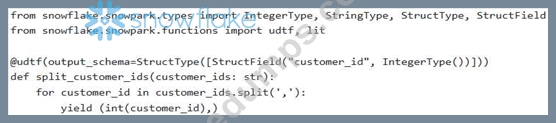
You are tasked with creating a UDTF using Snowpark Python that splits a comma-separated string of customer IDs into individual rows. The input is a string (VARCHAR) and the output should be a table with a single column named 'customer_id' of type INTEGER. Which of the following code snippets CORRECTLY defines and registers the UDTF, ensuring proper data type handling? Assume is a valid Snowpark Session object.
Answer: E
Explanation:
Option B correctly defines the UDTF. It uses 'StructType' and to define the output schema with a column named 'customer_id' of type "Integer Type'. The code also correctly converts the customer ID to an integer before yielding it. Option A defines the output schema as 'StringType' , which is incorrect. Option C does not correctly define a column name. Option D uses 'StringType' for the column, which violates the requirements. Option E adds and a return annotation which are valid, but the structure of the annotation is still not correct for a UDTF.
NEW QUESTION # 99
You have a DataFrame 'df containing user profile data'. A column named "profile" stores JSON objects with potentially missing fields. These objects might include 'name', 'age', 'location', and 'preferences'. You need to extract the user's name and age. If 'age' is missing, you want to default to 0. Furthermore, you want to filter out any rows where the 'location' field is an empty string. Which combination of Snowpark code snippets will achieve this? (Select all that apply)





Answer: A,B,C
Explanation:
Options A, B and C correctly address the requirements. They extract the name and handle the missing 'age' by defaulting to 0, and filter out rows with an empty string for 'location'. - Option A uses 'nvr to replace NULL 'age' values and ' to filter out empty locations. - Option B uses 'iff to achieve the same age default and sf.lit(")' for filtering. - Option C uses 'coalesce' to default 'age' and 'sf.lengtm to check if the location string has any characters. Option D will filter out all the rows where location is Null and option E uses zeroifnull function which is deprecated, and replaces age which is 0 if column is NULL. and option D wont filer empty string in location
NEW QUESTION # 100
......
VCEDumps serves as a most important source of IT certification information. You can find learning materials and study guides. If you are interesting in our VCEDumps Snowflake SPS-C01 exam dumps, you can depend on our VCEDumps to make a sound choice. VCEDumps Snowflake SPS-C01 test packed so much with the latest information about the certification training. By using our VCEDumps Snowflake SPS-C01 practice test, you have made preparations for the exam.
Sample SPS-C01 Questions Pdf: https://www.vcedumps.com/SPS-C01-examcollection.html