In the current market, there are too many products of the same type. It is actually very difficult to select the Databricks-Certified-Professional-Data-Engineer practice prep that you love the most with only product introduction. Our trial version of our Databricks-Certified-Professional-Data-Engineer Study Materials can be a good solution to this problem. For the trial versions are the free demos which are a small of the Databricks-Certified-Professional-Data-Engineer exam questions, they are totally free for our customers to download.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their expertise in using the Databricks platform. It provides employers with a way to identify and verify the skills of candidates and employees, and it can help data engineers advance their careers by demonstrating their proficiency in using the Databricks platform to build and maintain scalable and reliable data pipelines.
>> Databricks-Certified-Professional-Data-Engineer Exam Testking <<
Before you decide to get the Databricks-Certified-Professional-Data-Engineer exam certification, you may be attracted by the benefits of Databricks-Certified-Professional-Data-Engineer credentials. Get certified by Databricks-Certified-Professional-Data-Engineer certification means you have strong professional ability to deal with troubleshooting in the application. Besides, you will get promotion in your job career and obtain a higher salary. If you want to pass your Databricks Databricks-Certified-Professional-Data-Engineer Actual Test at first attempt, Databricks-Certified-Professional-Data-Engineer pdf torrent is your best choice. The high pass rate of Databricks-Certified-Professional-Data-Engineer vce dumps can give you surprise.
Databricks Certified Professional Data Engineer Exam is a certification program designed for data professionals who want to demonstrate their expertise in building, deploying, and maintaining data engineering solutions using Databricks. Databricks-Certified-Professional-Data-Engineer exam covers a wide range of topics related to data engineering and requires a thorough understanding of Databricks data engineering concepts and techniques. Databricks-Certified-Professional-Data-Engineer Exam is challenging and requires the candidate to demonstrate their ability to perform specific tasks using Databricks.
NEW QUESTION # 177
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date.
Which operation lacks support for cluster on write?
Answer: C
Explanation:
Delta Lake'sLiquid Clusteringis an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to aLiquid Clusteredtable, some write operations automatically maintain clustering, while othersdo not.
Explanation of Each Option:
* (A) spark.writestream.format('delta').mode('append') (Correct Answer)
* Reason:Streaming writes (writestream) donotsupportLiquid Clusteringbecause streaming data arrives in micro-batches.
* Since Liquid Clustering needs efficient global reorganization of files, streaming append operations don't provide sufficient data volume at a time to be effectively clustered.
* Delta Lake documentation states that Liquid Clustering is only supported for batch writes.
* (B) CTAS and RTAS statements
* Reason:CREATE TABLE AS SELECT (CTAS) and REPLACE TABLE AS SELECT (RTAS) are batch operationsand can enforce Liquid Clustering.
* These operations create or replace a table based on a query result, and since they are batch-based, Liquid Clustering applies.
* (C) INSERT INTO operations
* Reason:INSERT INTOis supportedfor Liquid Clustering because it is a batch operation.
* While it may not be as efficient as MERGE or COPY INTO, clustering is applied upon execution.
* (D) spark.write.format('delta').mode('append')
* Reason:Batch append operationsare supportedfor Liquid Clustering.
* Unlike streaming append, batch writes allow the optimizer to re-cluster data efficiently.
Conclusion:
Sincestreaming append operations do not support Liquid Clustering, option(A)is the correct answer.
References:
* Liquid Clustering in Delta Lake - Databricks Documentation
NEW QUESTION # 178
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.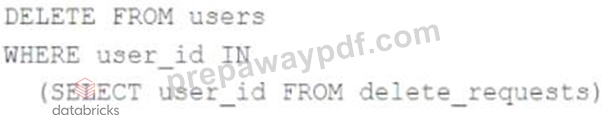
Assuming thatuser_idis a unique identifying key and thatdelete_requestscontains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: B
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under
"Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 179
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema: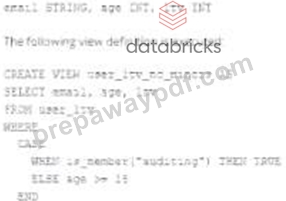
An analyze who is not a member of the auditing group executing the following query: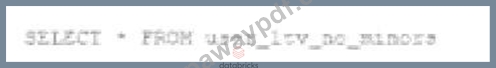
Which result will be returned by this query?
Answer: A
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 180
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: B
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data. Reference:
Optimizations: https://docs.delta.io/latest/optimizations-oss.html
Full-text search with Elasticsearch: https://docs.databricks.com/data/data-sources/elasticsearch.html Natural language processing: https://docs.databricks.com/applications/nlp/index.html
NEW QUESTION # 181
A data team is implementing an append-only Delta Lake pipeline that needs to handle both batch and streaming data. They want to ensure that schema changes in the source data can be automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
Answer: B
Explanation:
Databricks documents mergeSchema as the write option used to enable schema evolution when appending data to Delta tables. This allows new columns in the source to be automatically merged into the target schema rather than causing the write to fail. ( Databricks Documentation ) overwriteSchema is used with overwrite operations, not append-style schema evolution. validateSchema and ignoreChanges are not the correct configuration for this requirement. Because the pipeline is append-only and must tolerate source schema changes automatically, mergeSchema = true is the documented choice. ( Databricks Documentation )
======
NEW QUESTION # 182
......
Databricks-Certified-Professional-Data-Engineer Testking Exam Questions: https://www.prepawaypdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html