3V0-12.26トレーニングの質問のインストールまたは使用を懸念しているお客様がいるかもしれません。これについて心配する必要はありません。高品質と高効率に加えて、思いやりのあるサービスも当社の大きな利点です。 3V0-12.26学習教材の一貫した目的は、時間の節約と効率の向上です。これにより、レビュープロセスにプレッシャーや不安が充満することはなくなります。高品質と高効率に加えて、思いやりのあるサービスも当社の大きな利点です。すべてのお客様に24時間のオンラインアフターサービスを提供します。
| Section | Objectives |
|---|---|
| Topic 1: Install, Configure, and Administer VCF Design Elements | |
| Topic 2: VMware Cloud Foundation Products and Solutions | |
| Topic 3: IT Architectures, Technologies, Standards | |
| Topic 4: Troubleshoot and Optimize VMware Cloud Foundation Architecture | |
| Topic 5: Plan and Design VMware Cloud Foundation Solutions | - Translate business requirements into technical architecture - Design conceptual, logical, and physical solutions - Architect for availability, performance, security, and recoverability |
3V0-12.26試験に実際に参加して資料を選択する前に、このような証明書を保持することの重要性を思い出してください。このような3V0-12.26証明書を取得することで、昇給、昇進の機会、上司や同僚からの信頼など、将来の多くの同意結果を習得できます。これらすべての快い結果は、もはやあなたにとって夢ではありません。そして、3V0-12.26試験準備により、成績を改善し、生活の状態を変え、キャリアの驚くべき変化を得ることができ、すべてが可能になります。それはすべて、3V0-12.26学習の質問から始まります。
質問 # 42
An architect is designing the physical and host networking architecture for vSAN Express Storage Architecture (ESA) in a VMware Cloud Foundation (VCF) deployment.
The customer requires maximum storage performance for latency-sensitive, high-IOPS workloads in analytics, artificial intelligence (AI), and machine learning (ML). To achieve this, the design must incorporate Remote Direct Memory Access (RDMA) over Converged Ethernet (RoCE v2) for vSAN data traffic while maintaining a converged network for all other VCF traffic types.
During requirements gathering, the customer specified the following technical requirements:
* Ultra-low latency and maximum throughput for vSAN data traffic.
* Support for Priority Flow Control (PFC) to ensure lossless Ethernet for RoCE v2 traffic.
* Deterministic performance with no dynamic load balancing that could introduce variability in storage I
/O paths.
* End-to-end jumbo frame support across the fabric.
* High availability with tolerance to single NIC or switch failures.
* Converged design where RoCE v2 vSAN traffic is separated by the physical infrastructure with management, vMotion, and NSX overlay traffic traversing a secondary network.
Given these RDMA-enabled vSAN networking requirements in a multi-rack VMware Cloud Foundation (VCF) environment, what are the three key design decisions? (Choose three.)
正解:C、D、E
解説:
C, E, and F most directly satisfy the stated performance, isolation, lossless-fabric, and deterministic-failover requirements.
C provides the physical separation and bandwidth demanded by the scenario. VMware recommends high- bandwidth networking for demanding vSAN ESA workloads; 100 GbE is specifically recommended for performance-intensive ESA deployments , because high-performance NVMe devices can saturate lower- speed links. Dedicated RDMA-capable NIC ports also prevent TCP-based management, vMotion, and NSX traffic from competing with the RoCE storage path. ( VMware Blogs ) E addresses two explicit requirements. RoCE v2 requires correctly configured DCB/PFC to provide the lossless Ethernet behavior required by RDMA, and jumbo-frame configuration must remain consistent end-to- end through VMkernel adapters, NICs, and physical switching. Broadcom explicitly requires DCB and PFC configuration for vSAN RDMA. ( Support Portal ) F provides deterministic path selection and redundancy. vSAN RDMA does not support Load-Based Teaming , LACP, or IP-hash because an RDMA connection cannot dynamically spread across multiple RNICs. Broadcom supports explicit failover and recommends Active/Passive behavior for predictable vSAN networking. ( Support Portal ) D is therefore specifically inappropriate for RDMA. Although a leaf-spine topology in B is architecturally strong, it is not itself mandatory to satisfy these host/RDMA requirements; DCB/PFC and lossless behavior are already explicitly implemented by the selected fabric configuration.
Study Guide References/Topics: vSAN ESA Network Design; vSAN over RDMA/RoCE v2; DCB and PFC; Jumbo Frames; RDMA NIC Teaming Restrictions; Active/Standby Failover; High-Performance ESA Physical Networking.
the networking requirements
質問 # 43
Match the definitions to the terms for MoSCoW ratings by dragging and dropping the Term on the left to the Definition on the right.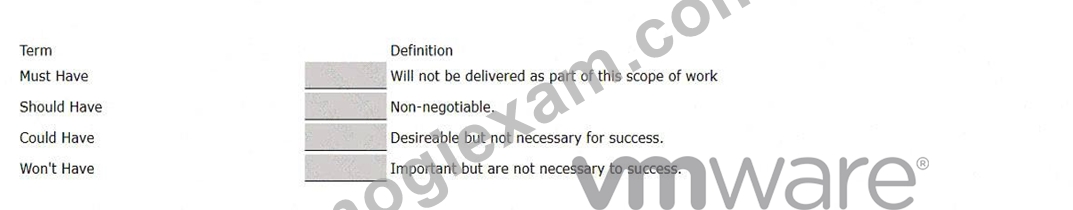
正解:
解説: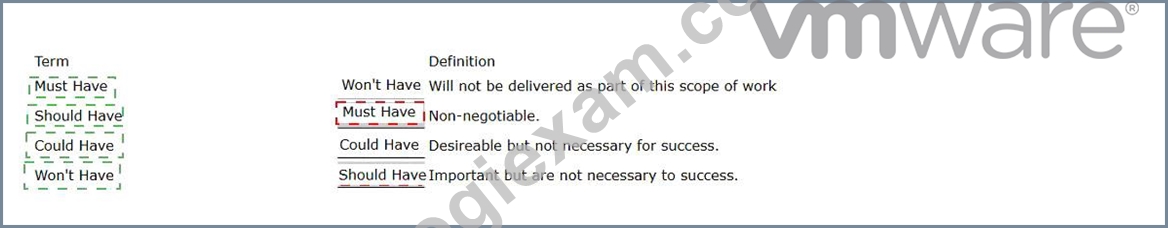
Explanation:
Term
Correct Definition
Must Have
Non-negotiable.
Should Have
Important but are not necessary to success.
Could Have
Desirable but not necessary for success.
Won ' t Have
Will not be delivered as part of this scope of work.
The MoSCoW prioritization method classifies requirements according to how critical they are to the success and scope of a solution.
A Must Have requirement is non-negotiable . Failure to satisfy it means the solution does not meet an essential business or technical requirement.
A Should Have requirement is important and normally expected, but the project can still succeed without it if necessary. Such requirements may be deferred when schedule, cost, or resource constraints demand prioritization.
A Could Have requirement is desirable but has lower business impact. These capabilities are implemented when time and resources permit and can be removed from the current delivery with comparatively little effect on overall success.
A Won ' t Have requirement is explicitly excluded from the current scope. It is not necessarily permanently rejected; it may be reconsidered in a later phase or release.
For VCF architecture work, MoSCoW helps convert workshop findings into prioritized requirements and prevents optional functionality from competing with mandatory architectural objectives.
Study Guide References/Topics: Requirements Gathering; MoSCoW Prioritization; Conceptual Design; Business and Technical Requirements; Scope Management.
質問 # 44
An architect is designing a VMware Cloud Foundation (VCF) infrastructure Virtual Private Cloud (VPC) IP Address Management (IPAM) Model. An architect recognizes a potential problem with maximum Private TGW blocks.
What is the maximum Private TGW IP blocks in a connectivity profile?
正解:A
解説:
The correct limit is up to five Private Transit Gateway (TGW) IP blocks per VPC Connectivity Profile .
In the VCF 9 Virtual Networking Technical Reference, the IPAM model defines how address pools are exposed to VPCs. A VPC Connectivity Profile can contain both External IP Blocks and Private TGW IP Blocks , with each category supporting up to five IP blocks . The guide states that Private TGW blocks are assigned through the connectivity profile and are then used to allocate address space for Private-TGW subnets. ( Higher Logic Download ) Private-TGW addressing is scoped to the Transit Gateway and is particularly useful when multiple VPCs within the same NSX Project need routed communication with each other while keeping that address space private from external networks. The block is shared at the project/TGW level, and individual VPC subnets consume CIDRs from the available Private TGW blocks.
Therefore, an architect must account for the five-block maximum when planning IP address hierarchy, future subnet growth, aggregation strategy, and multi-tenant VPC expansion. If more address space is anticipated, the architect should choose sufficiently large, non-overlapping blocks from the outset rather than assuming an unlimited number of blocks can later be attached.
Study Guide References/Topics: VCF VPC IPAM; VPC Connectivity Profiles; Private Transit Gateway IP Blocks; Transit Gateway Networking; NSX VPC Address Management; IP Block Scalability.
質問 # 45
A customer is planning to implement a VMware Cloud Foundation (VCF) environment to support a mix of production and development virtualized workloads. The customer intends to use vSAN as the principal storage solution for both environments. During the initial planning meeting, the following requirements were identified:
* The production environment requires high availability and fault tolerance, with at least 1 copy of each VM ' s data.
* The development environment needs to be able to tolerate availability, with 2 copies of each VM ' s data.
* The customer is planning to deploy 15 ESX hosts in the cluster.
* The customer expects to onboard 475 virtual machines in the production environment and 250 VMs in the development environment, with an average disk size of 275 GB per VM.
* The customer requires storage policies that provide redundancy and high performance in the development environment but can afford lower redundancy and performance in the production environment.
Given these requirements, which two factors will impact the storage design for this VCF implementation?
(Choose two.)
正解:A、D
解説:
C and D are the primary factors that directly determine the required vSAN storage capacity and its performance/redundancy characteristics.
C is correct because the selected vSAN storage policy determines how VM objects are placed and how much physical capacity they consume. Broadcom documents that Failures to Tolerate (FTT) controls redundancy, while the RAID method determines capacity efficiency and performance. For example, RAID-1 with FTT=1 creates mirrored data and consumes approximately 2× the logical data size, while FTT=2 mirroring consumes approximately 3× . Stripe width can also affect performance and component consumption.
D is correct because workload quantity and sizing establish the fundamental storage demand. The proposed
725 VMs (475 + 250) at an average 275 GB each represent approximately 199.4 TB of logical VM disk capacity before applying redundancy, metadata, operational reserve, and growth allowances. Storage policies then multiply or otherwise alter that physical-capacity requirement.
E affects cluster architecture and determines whether certain policies can be supported-for example, RAID-6 FTT=2 requires at least six hosts-but with 15 hosts already specified , host count is not the principal sizing factor among the choices. A concerns management-network redundancy, while B addresses workload networking rather than vSAN capacity design.
Study Guide References/Topics: vSAN Storage Policy-Based Management; Failures to Tolerate; RAID-1/5
/6; Stripe Width; Workload Profiling; Storage Capacity Planning; VCF Workload Domain Storage Design.
質問 # 46
An architect is responsible for designing a VMware Cloud Foundation (VCF) Private Cloud solution. During a requirements gathering workshop, the customer supplied the following information:
* The solution must support the monitoring of all existing workloads.
* There are currently 15,000 virtual machine workloads running within the existing environment.
* All infrastructure components will also be monitored by the solution.
The solution must ensure that the 99.9% uptime Service Level Agreement can be met.
The solution must be resilient to a single fault domain failure.
The following logical design decisions have been made within the design:
* Deploy the VCF Operations cluster following the High Availability Model.
The following table is from the VCF Operations sizing guide:
Small
Medium
Single-Node Object Maximum
10,000
30,000
Single-Node Max Collected Metrics
1,600,000
5,000,000
Maximum Nodes in a cluster
2
8
Multi-Node Object Maximum
6,000
17,000
Multi-Node Max Collected Metrics
1,400,000
4,000,000
Maximum Objects in a Cluster
12,000
136,000
Maximum Metrics in a Cluster
2,800,000
32,000,000
Maximum Nodes for Continuous Availability per Fault Domain
1
4
Given the information above, which three physical design decisions meet the stated requirements? (Choose three.)
正解:A、C、F
解説:
A, D, and E meet the availability, sizing, and fault-domain requirements.
A is required because Continuous Availability (CA), rather than standard HA, provides fault-domain resilience. Broadcom states that VCF Operations CA stretches cluster nodes across two fault domains and can tolerate the loss of an entire fault domain without cluster downtime. Standard VCF Operations HA protects only against one node failure , so C does not satisfy the stated requirement for a single fault domain failure. CA requires equal node distribution across the two fault domains and a witness in a third location.
E is correct because 15,000 VMs plus all monitored infrastructure objects exceed the practical capacity of the Small configuration. Two Small nodes support only 12,000 maximum cluster objects before CA replication considerations . Four Medium nodes provide sufficient capacity and can be distributed as two analytics nodes per fault domain. Broadcom also notes that CA replication effectively reduces available object capacity compared with a non-CA deployment.
D ensures Operations analytics nodes are separated across physical hosts rather than sharing a common failure point. Broadcom specifically recommends DRS anti-affinity to keep Operations nodes on separate hosts.
Study Guide References/Topics: VCF Operations Sizing; Continuous Availability; Fault Domains; Analytics Node Placement; DRS Anti-Affinity; High Availability versus Continuous Availability.
質問 # 47
......
ほかの人はあちこちVMwareの3V0-12.26試験の資料を探しているとき、あなたは問題集の勉強を始めました。準備の段階であなたはリーダーしています。我々MogiExamの提供するVMwareの3V0-12.26試験のソフトは豊富な試験に関する資源を含めてあなたに最も真実のVMwareの3V0-12.26試験環境で体験させます。
3V0-12.26認証資格: https://www.mogiexam.com/3V0-12.26-exam.html