NCP-AII Latest Exam Materials - Test NCP-AII Answers

What's more, part of that TorrentVCE NCP-AII dumps now are free: https://drive.google.com/open?id=1kAlAT52gKvA2NIao5z_L3VUDyOAZFuXs
We believe that every customer pays most attention to quality when he is shopping. Only high-quality goods can meet the needs of every customer better. And our NCP-AII training quiz has such high quality, because its hit rate of test questions is extremely high. Perhaps you will find in the examination that a lot of questions you have seen many times in our NCP-AII Real Exam. And you will find our NCP-AII practice questions are so popular that a lot of our candidates have bought them.
| Topic | Details |
|---|
| Topic 1 | - Control Plane Installation and Configuration: Covers deploying the software stack including Base Command Manager, OS, Slurm
- Enroot
- Pyxis, NVIDIA GPU and DOCA drivers, container toolkit, and NGC CLI.
|
| Topic 2 | - System and Server Bring-up: Covers end-to-end physical setup of GPU-based AI infrastructure, including BMC
- OOB
- TPM configuration, firmware upgrades, hardware installation, and power and cooling validation to ensure servers are workload-ready.
|
| Topic 3 | - Physical Layer Management: Covers configuring BlueField network platform devices and setting up Multi-Instance GPU (MIG) partitioning for AI and HPC workloads.
|
| Topic 4 | - Cluster Test and Verification: Covers full cluster validation through HPL and NCCL benchmarks, NVLink and fabric bandwidth tests, cable and firmware checks, and burn-in testing using HPL, NCCL, and NeMo.
|
| Topic 5 | - Troubleshoot and Optimize: Covers identifying and replacing faulty hardware components such as GPUs, network cards, and power supplies, along with performance optimization for AMD
- Intel servers and storage.
|
>> NCP-AII Latest Exam Materials <<
100% Pass Quiz NCP-AII - NVIDIA AI Infrastructure –Efficient Latest Exam Materials
The NCP-AII prep guide adopt diversified such as text, images, graphics memory method, have to distinguish the markup to learn information, through comparing different color font, as well as the entire logical framework architecture, let users of the NCP-AII training dump on the premise of grasping the overall layout, better clues to the formation of targeted long-term memory, and through the cycle of practice, let the knowledge more deeply printed in my mind. The NCP-AII Exam Questions are so scientific and reasonable that you can easily remember everything of the NCP-AII exam.
NVIDIA AI Infrastructure Sample Questions (Q100-Q105):
NEW QUESTION # 100
Which of the following statements are true regarding the use of Congestion Management (CM) and Congestion Avoidance (CA) techniques within an InfiniBand fabric using NVIDIA technology? (Select TWO)
- A. CM/CA mechanisms are primarily implemented at the IP layer and are independent of the InfiniBand transport layer.
- B. InfiniBand's Explicit Congestion Notification (ECN) is a CA mechanism that allows switches to signal congestion to endpoints before packet loss occurs.
- C. CM/CA are not relevant in InfiniBand fabrics because InfiniBand's lossless nature guarantees that no packets will ever be dropped due to congestion.
- D. CM aims to reduce the severity of congestion once it has already occurred, while CA aims to prevent congestion from happening in the first place.
- E. CM can include techniques like rate limiting to throttle traffic flows when congestion is detected.
Answer: B,D,E
Explanation:
CM and CA are crucial for maintaining performance in InfiniBand fabrics. CM addresses congestion that has already occurred, while CA tries to prevent it. ECN is a key CA mechanism in InfiniBand. InfiniBand is lossless but experiences performance degradation if congestion occurs; CM helps mitigate this. They are not implemented at the IP layer; they are integral parts of the InfiniBand transport. Rate limiting is a viable CM strategy.
NEW QUESTION # 101
You are tasked with designing a high-performance network for a large-scale recommendation system. The system requires low latency and high throughput for both training and inference. Which interconnect technology is MOST suitable for connecting the nodes within the cluster?
- A. InfiniBand
- B. Fibre Channel
- C. 100 Gigabit Ethernet
- D. Gigabit Ethernet
- E. 10 Gigabit Ethernet
Answer: A
Explanation:
InfiniBand is designed for high-performance computing and offers significantly lower latency and higher bandwidth compared to Ethernet or Fibre Channel, making it the most suitable choice for demanding workloads like recommendation systems. While 100 Gigabit Ethernet provides high bandwidth, InfiniBand generally offers lower latency.
NEW QUESTION # 102
Refer to the exhibit. What is the longest distance that DAC LinkX 25G-NRZ cables can cover?
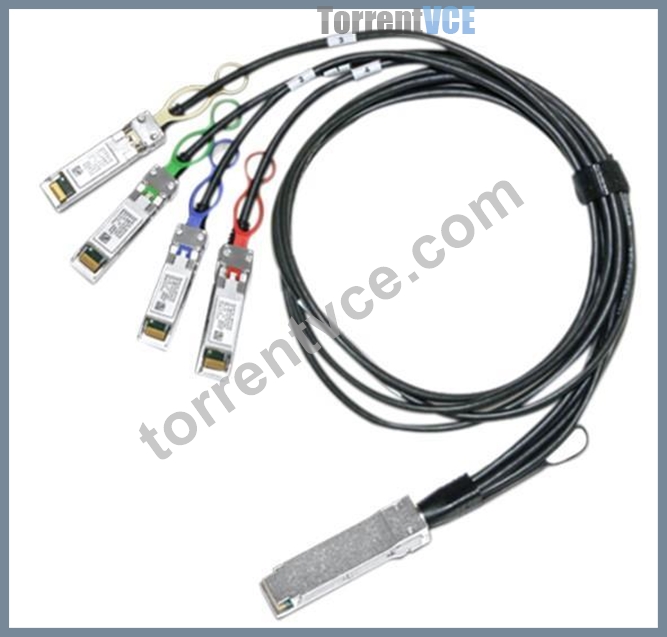
- A. 5 meters
- B. 1 meter
- C. 10 meters
- D. 3 meters
Answer: A
Explanation:
DAC LinkX 25G-NRZ copper cables support short-reach server and switch connections, with the longest supported cable length being 5 meters.
NEW QUESTION # 103
You are validating the environment of an NVIDIA GPU-accelerated data center during post-deployment checks. Which one action is essential to confirm that power and cooling are sufficient for the stable operation of NVIDIA DGX H100 systems?
- A. Verify that each DGX system is connected to redundant, properly rated PDUs and that all power supplies are reporting nominal input.
- B. Use NVSM to disable unused PCIe devices to reduce overall system heat output.
- C. Review the system BIOS to ensure GPU overclocking is enabled for maximum performance.
- D. Confirm the system fans are running at 100% under all workloads to prevent overheating.
Answer: A
Explanation:
Stable operation of high-density AI infrastructure like the DGX H100 requires strict adherence to power and thermal specifications. A single DGX H100 system can draw up to10.2kWunder peak load. Therefore, the most essential validation step is ensuring the electrical "infrastructure-to-server" handoff is healthy. This involves verifying that the system is connected to redundant PDUs (Power Distribution Units) capable of handling the amperage requirements without tripping breakers. UsingNVSM (NVIDIA System Management), an administrator must check that all six power supplies (PSUs) are functional and receiving nominal input voltage (typically 200V-240V). If a PSU reports sub-optimal input or a "Loss of Redundancy," the system may throttle performance or shut down unexpectedly during a heavy training run. Fans running at
100% (Option A) at all times would actually indicate an inefficient or failed cooling policy, as fans should dynamically scale based on thermals. Overclocking (Option B) is not supported or recommended for enterprise DGX systems, as they are already factory-tuned for the highest stable performance.
NEW QUESTION # 104
Why is it important to provide a large and high-performance local cache (using SSDs configured as RAID-0) for deep learning workloads on DGX systems?
- A. Local SSD cache allows users to increase the number of NFS threads on the server without impacting storage reliability.
- B. Local SSD cache in RAID-0 is necessary to provide redundancy in case one of the drives fails during long training runs.
- C. Using local SSD cache in RAID-0 enables direct GPU access to files without host CPU involvement, further boosting performance.
- D. A local SSD cache in RAID-0 ensures that most training data is read only once from the network, significantly reducing NFS traffic.
Answer: D
Explanation:
Deep learning training involves iterating over a dataset many times (epochs). If a 32-node cluster pulls the same dataset from a central NFS storage server for every epoch, the network and storage fabric quickly become a bottleneck due to " Incast " traffic. By using the high-speed NVMe drives internal to a DGX system (configured in RAID-0 for maximum performance, not redundancy), the system can implement a local cache.
During the first epoch, data is pulled from the remote storage and simultaneously written to the local SSDs.
For all subsequent epochs, the training framework reads the data directly from the local RAID-0 array. This significantly reduces NFS traffic and network congestion, allowing the training to proceed at the full speed of the local NVMe storage ($25\text{ GB/s}+$ on modern DGX systems). Option C is incorrect because RAID-
0 provides no redundancy; if a drive fails, the cache is lost, but since it is just a cache, the data still exists on the primary storage. Option B refers to GPUDirect Storage, which is a separate technology from local RAID-
0 caching.
NEW QUESTION # 105
......
Our NCP-AII exam guide is suitable for everyone whether you are a business man or a student, because you just need 20-30 hours to practice it that you can attend to your exam. There is no doubt that you can get a great grade. If you follow our learning pace, you will get unexpected surprises. Only when you choose our NCP-AII Guide Torrent will you find it easier to pass this significant examination and have a sense of brand new experience of preparing the NCP-AII exam.
Test NCP-AII Answers: https://www.torrentvce.com/NCP-AII-valid-vce-collection.html
- NCP-AII Reliable Test Sims 🚮 NCP-AII Valid Exam Format 🧆 NCP-AII Reliable Exam Book 🚋 Open ➠ www.prepawayexam.com 🠰 enter 《 NCP-AII 》 and obtain a free download 🔷Detailed NCP-AII Study Plan
- Interactive NCP-AII Questions 🐲 Exam NCP-AII Quizzes 🤦 NCP-AII Valid Exam Format 🌤 Download ▷ NCP-AII ◁ for free by simply searching on { www.pdfvce.com } 📏Mock NCP-AII Exam
- NCP-AII Practice Braindumps 🕦 NCP-AII Online Version 🥿 NCP-AII Reliable Test Questions ✳ Search for ▷ NCP-AII ◁ and easily obtain a free download on ⮆ www.prepawaypdf.com ⮄ 🌉NCP-AII Reliable Exam Online
- Free PDF NVIDIA - Professional NCP-AII Latest Exam Materials ⛑ Easily obtain free download of ➡ NCP-AII ️⬅️ by searching on { www.pdfvce.com } 🛸Valid NCP-AII Test Forum
- Official NCP-AII Practice Test 👖 NCP-AII Reliable Exam Book 📑 NCP-AII Reliable Exam Book 🚞 Download ✔ NCP-AII ️✔️ for free by simply entering ✔ www.validtorrent.com ️✔️ website 🕋Mock NCP-AII Exam
- 2026 NCP-AII Latest Exam Materials | Pass-Sure NCP-AII 100% Free Test Answers 🪐 Search for ⏩ NCP-AII ⏪ and download it for free immediately on ⏩ www.pdfvce.com ⏪ 🏬NCP-AII New Study Materials
- NCP-AII Latest Exam Materials – 100% Pass-Rate Test Answers Providers for NVIDIA NCP-AII: NVIDIA AI Infrastructure 🦲 Go to website ⇛ www.troytecdumps.com ⇚ open and search for ⏩ NCP-AII ⏪ to download for free ℹNCP-AII Reliable Exam Book
- NCP-AII Reliable Test Prep 📶 Valid NCP-AII Test Forum 🧃 Detailed NCP-AII Study Plan 🚈 Search on ☀ www.pdfvce.com ️☀️ for 【 NCP-AII 】 to obtain exam materials for free download 🩸NCP-AII Reliable Test Questions
- Quiz 2026 NVIDIA NCP-AII: The Best NVIDIA AI Infrastructure Latest Exam Materials 🚉 Download ▶ NCP-AII ◀ for free by simply entering ✔ www.dumpsmaterials.com ️✔️ website 🌲Exam NCP-AII Quizzes
- Perfect NCP-AII Latest Exam Materials, Test NCP-AII Answers ⏯ Search for ▷ NCP-AII ◁ and download it for free on ➥ www.pdfvce.com 🡄 website 🍖Mock NCP-AII Exam
- Interactive NCP-AII Questions 👔 Mock NCP-AII Exam 🍅 NCP-AII Exam Questions And Answers 🐍 Search for { NCP-AII } and download it for free immediately on ▶ www.testkingpass.com ◀ 🦦NCP-AII Learning Engine
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 NVIDIA NCP-AII dumps are available on Google Drive shared by TorrentVCE: https://drive.google.com/open?id=1kAlAT52gKvA2NIao5z_L3VUDyOAZFuXs