Our Certified-Data-Engineer-Professional study braindumps can be very good to meet user demand in this respect, allow the user to read and write in a good environment continuously consolidate what they learned. Our Certified-Data-Engineer-Professional prep guide has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit Certified-Data-Engineer-Professional Exam Questions. It points to the exam heart to solve your difficulty. So high quality materials can help you to pass your exam effectively, make you feel easy, to achieve your goal.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
>> Study Guide Certified-Data-Engineer-Professional Pdf <<
As we all know, it is difficult to prepare the Certified-Data-Engineer-Professional exam by ourselves. Excellent guidance is indispensable. If you urgently need help, come to buy our study materials. Our company has been regarded as the most excellent online retailers of the Certified-Data-Engineer-Professional exam question. So our assistance is the most professional and superior. You can totally rely on our study materials to pass the exam. In addition, all installed Certified-Data-Engineer-Professional study tool can be used normally. In a sense, our Certified-Data-Engineer-Professional Real Exam dumps equal a mobile learning device. We are not just thinking about making money. Your convenience and demands also deserve our deep consideration. At the same time, your property rights never expire once you have paid for money. So the Certified-Data-Engineer-Professional study tool can be reused after you have got the Certified-Data-Engineer-Professional certificate. You can donate it to your classmates or friends. They will thank you so much.
NEW QUESTION # 120
Which statement describes Delta Lake optimized writes?
Answer: C
Explanation:
Delta Lake optimized writes involve a shuffle operation before writing out data to the Delta table.
The shuffle operation groups data by partition keys, which can lead to a reduction in the number of output files and potentially larger files, instead of multiple smaller files. This approach can significantly reduce the total number of files in the table, improve read performance by reducing the metadata overhead, and optimize the table storage layout, especially for workloads with many small files.
NEW QUESTION # 121
A company wants to implement Lakehouse Federation across multiple data sources but is concerned about data consistency and ensuring that all teams access the same authoritative version of their data. Which statement is applicable for Lakehouse Federations to maintain data consistency?
Answer: A
Explanation:
Lakehouse Federation allows Databricks to query and manage external data sources through a single governance layer, without moving or copying data. The documentation specifies that
"Federated queries provide read-only access to data, reflecting the current state of the underlying source system." This ensures consistency across teams since all users access the same source of truth directly from the external system through Unity Catalog. Federation does not perform CDC replication or local caching; it queries live data on demand. Hence, option A accurately represents how Lakehouse Federation maintains consistency across federated sources.
NEW QUESTION # 122
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.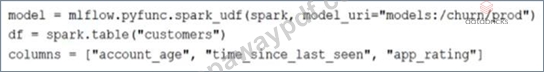
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
Answer: A
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 123
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
Answer: A
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 124
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
Answer: D
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 125
......
Thanks to our diligent experts, wonderful study tools are invented for you to pass the Certified-Data-Engineer-Professional exam. You can try the demos of our Certified-Data-Engineer-Professional exam questions first and find that you just can't stop studying. There are three kinds of the free demos according to the three versions of the Certified-Data-Engineer-Professional learning guide. Using our Certified-Data-Engineer-Professional study materials, you will just want to challenge yourself and get to know more.
Reliable Certified-Data-Engineer-Professional Test Blueprint: https://www.prepawaypdf.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html