試験の準備方法-真実的なDP-600模擬モード試験-効果的なDP-600日本語サンプル

P.S.GoShikenがGoogle Driveで共有している無料の2026 Microsoft DP-600ダンプ:https://drive.google.com/open?id=1j3yAa0VU6F_flyFleaelVCgaYPppO4pu
DP-600の調査の質問は高品質です。したがって、テストの準備をするためのすべての効果的かつ中心的なプラクティスがあります。専門的な能力を備えているため、DP-600試験問題を編集するために必要なテストポイントに合わせることができます。あなたの難しさを解決するために、試験の中心を指し示します。したがって、高品質の資料を使用すると、試験に効果的に合格し、安心して目標を達成できます。 DP-600テストガイドのフィードバックを使用すると、98%〜100%の合格率が得られます。それがお客様からの真実です。また、20時間から30時間の練習を経てDP-600試験に合格するのは簡単です。
Microsoft DP-600 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| トピック 2 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
| トピック 3 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
>> DP-600模擬モード <<
Microsoft DP-600日本語サンプル、DP-600専門知識訓練
現在の社会の中で優秀な人材が揃てIT人材も多く、競争もとても大きくて、だから多くのIT者はにIT関する試験に参加するIT業界での地位のために奮闘しています。DP-600試験はMicrosoftの一つ重要な認証試験で多くのIT専門スタッフが認証される重要な試験です。
Microsoft Implementing Analytics Solutions Using Microsoft Fabric 認定 DP-600 試験問題 (Q174-Q179):
質問 # 174
You have a Fabric tenant.
You are creating a Fabric Data Factory pipeline.
You have a stored procedure that returns the number of active customers and their average sales for the current month.
You need to add an activity that will execute the stored procedure in a warehouse. The returned values must be available to the downstream activities of the pipeline.
Which type of activity should you add?
- A. Get metadata
- B. Script
- C. Stored procedure
- D. Append variable
正解:C
質問 # 175
You have a Fabric tenant that contains a takehouse named lakehouse1. Lakehouse1 contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
DESCRIBE HISTORY customer
Does this meet the goal?
正解:A
質問 # 176
You are analyzing the data in a Fabric notebook.
You have a Spark DataFrame assigned to a variable named df.
You need to use the Chart view in the notebook to explore the data manually.
Which function should you run to make the data available in the Chart view?
- A. displayMTML
- B. write
- C. show
- D. display
正解:D
質問 # 177
You have a Fabric workspace that uses the default Spark starter pool and runtime version 1,2.
You plan to read a CSV file named Sales.raw.csv in a lakehouse, select columns, and save the data as a Delta table to the managed area of the lakehouse. Sales_raw.csv contains 12 columns.
You have the following code.
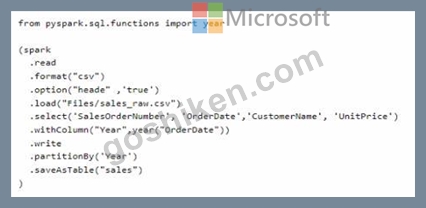
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
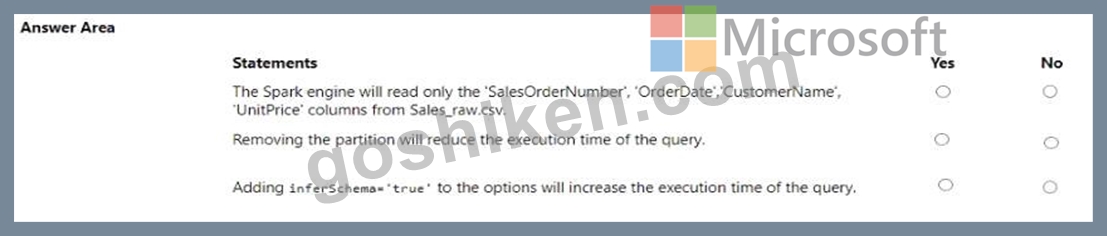
正解:
解説:
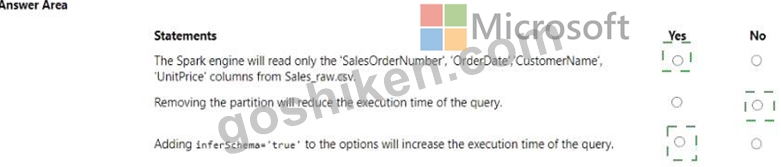
Explanation:
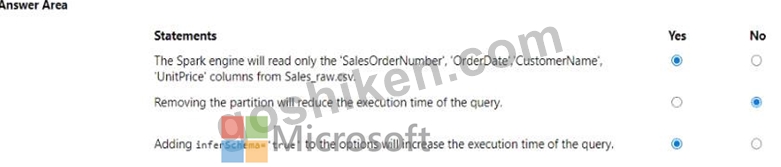
* The Spark engine will read only the 'SalesOrderNumber', 'OrderDate', 'CustomerName', 'UnitPrice' columns from Sales_raw.csv. - Yes
* Removing the partition will reduce the execution time of the query. - No
* Adding inferSchema='true' to the options will increase the execution time of the query. - Yes The code specifies the selection of certain columns, which means only those columns will be read into the DataFrame. Partitions in Spark are a way to optimize the execution of queries by organizing the data into parts that can be processed in parallel. Removing the partition could potentially increase the execution time because Spark would no longer be able to process the data in parallel efficiently. The inferSchema option allows Spark to automatically detect the column data types, which can increase the execution time of the initial read operation because it requires Spark to read through the data to infer the schema.
質問 # 178
You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements. What should you include in the solution?
- A. an Azure Data Factory pipeline that executes a Stored procedure activity to retrieve the minimum value of the OrderiD column m the destination lakehouse
- B. an Azure Data Factory pipeline that executes a dataflow to retrieve the maximum value of the OrderlD column in the destination lakehouse
- C. an Azure Data Factory pipeline that executes a Stored procedure activity to retrieve the maximum value of the OrderlD column in the destination lakehouse
- D. an Azure Data Factory pipeline that executes a dataflow to retrieve the minimum value of the OrderlD column in the destination lakehouse
正解:B
解説:
Requirement: "The number of rows added to the Orders table during refreshes must be minimized." The Orders table has a sequential OrderID.
To minimize refresh size, you must only import new rows, not the entire table.
This requires retrieving the maximum OrderID currently loaded, then only loading rows with a greater OrderID.
So, the correct solution is to use a pipeline (ADF) with a dataflow to retrieve the maximum OrderID.
The answer: C. an Azure Data Factory pipeline that executes a dataflow to retrieve the maximum value of
the OrderID column in the destination lakehouse
質問 # 179
......
DP-600試験ガイドの3つのバージョンはPDF版、PC版とAPPオンライン版を含め、当社のテストプラットフォーム上で利用可能です。その結果、携帯電話またはコンピューターでDP-600学習教材のオンラインテストエンジンを学習できます。また、自宅、会社、または地下鉄でDP-600実際の試験を勉強することもできます。ベテランであれば、DP-600試験の質問で勉強し、DP-600試験に合格するために、非常に効率的な方法で断片化時間を最大限に活用できます。
DP-600日本語サンプル: https://www.goshiken.com/Microsoft/DP-600-mondaishu.html
- DP-600試験の準備方法|ユニークなDP-600模擬モード試験|ハイパスレートのImplementing Analytics Solutions Using Microsoft Fabric日本語サンプル ⌚ ➥ www.xhs1991.com 🡄で使える無料オンライン版「 DP-600 」 の試験問題DP-600クラムメディア
- 最新DP-600|信頼的なDP-600模擬モード試験|試験の準備方法Implementing Analytics Solutions Using Microsoft Fabric日本語サンプル Ⓜ ✔ www.goshiken.com ️✔️から簡単に▛ DP-600 ▟を無料でダウンロードできますDP-600最新試験
- DP-600日本語版復習資料 🥃 DP-600合格記 ⚠ DP-600試験関連赤本 🥢 [ www.jpshiken.com ]の無料ダウンロード{ DP-600 }ページが開きますDP-600試験番号
- Microsoft DP-600認定試験の受験に対する対策 😄 ▷ www.goshiken.com ◁は、“ DP-600 ”を無料でダウンロードするのに最適なサイトですDP-600日本語版サンプル
- DP-600関連問題資料 🏊 DP-600日本語版対応参考書 🦲 DP-600試験解説問題 😿 ⏩ www.japancert.com ⏪は、▶ DP-600 ◀を無料でダウンロードするのに最適なサイトですDP-600ミシュレーション問題
- DP-600試験の準備方法|ユニークなDP-600模擬モード試験|ハイパスレートのImplementing Analytics Solutions Using Microsoft Fabric日本語サンプル ☃ Open Webサイト▷ www.goshiken.com ◁検索➤ DP-600 ⮘無料ダウンロードDP-600日本語版復習資料
- DP-600最新日本語版参考書 🍼 DP-600ミシュレーション問題 🪁 DP-600模試エンジン 🏕 ⇛ www.xhs1991.com ⇚の無料ダウンロード➥ DP-600 🡄ページが開きますDP-600勉強時間
- 認定する-権威のあるDP-600模擬モード試験-試験の準備方法DP-600日本語サンプル 🍳 ( DP-600 )を無料でダウンロード➠ www.goshiken.com 🠰で検索するだけDP-600復習問題集
- DP-600試験番号 🛹 DP-600日本語版サンプル ✏ DP-600クラムメディア 😢 ⮆ DP-600 ⮄を無料でダウンロード➠ www.passtest.jp 🠰で検索するだけDP-600合格記
- DP-600関連問題資料 💷 DP-600最新試験 ⚡ DP-600合格記 🥓 ➠ www.goshiken.com 🠰サイトにて「 DP-600 」問題集を無料で使おうDP-600ミシュレーション問題
- 最新DP-600|信頼的なDP-600模擬モード試験|試験の準備方法Implementing Analytics Solutions Using Microsoft Fabric日本語サンプル 📓 ▛ www.shikenpass.com ▟を入力して➤ DP-600 ⮘を検索し、無料でダウンロードしてくださいDP-600最新日本語版参考書
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, quay.io, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.longisland.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, app.intigriti.com, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! GoShiken DP-600ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1j3yAa0VU6F_flyFleaelVCgaYPppO4pu