Pdf Databricks-Certified-Data-Engineer-Professional Format - Pass Databricks-Certified-Data-Engineer-Professional Guarantee

If our Databricks Certified Data Engineer Professional Exam guide torrent can’t help you pass the exam, we will refund you in full. If only the client provide the exam certificate and the scanning copy or the screenshot of the failure score of Databricks-Certified-Data-Engineer-Professional Exam, we will refund the client immediately. The procedure of refund is very simple. The client can contact us by sending mails or contact us online. We will solve your problem as quickly as we can and provide the best service. Our after-sales service is great as we can solve your problem quickly and won’t let your money be wasted.
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Delta Lake
- Data Management
- Unity Catalog
|
| Data Quality and Governance | 12% | - Governance
- Data Quality
- Data Lineage
|
| Data Processing | 28% | - Data Transformation
- Spark SQL
- ETL Pipelines
- Structured Streaming
|
| Data Modeling and Storage | 20% | - Data Modeling
- Storage Optimization
- File Formats
|
| Monitoring and Troubleshooting | 16% | - Troubleshooting
- Performance Optimization
- Monitoring
|
>> Pdf Databricks-Certified-Data-Engineer-Professional Format <<
Pass Databricks Databricks-Certified-Data-Engineer-Professional Guarantee, Databricks-Certified-Data-Engineer-Professional Pass Guarantee
Do you often feel that the product you have brought is not suitable for you? I would like to tell you that you will never meet the problem when you decide to use our Databricks-Certified-Data-Engineer-Professional learning guide. Our Databricks-Certified-Data-Engineer-Professional study materials have a high quality that you can't expect. If you do experience by the guidance of our Databricks-Certified-Data-Engineer-Professional Study Materials, you will spend less time than you did before, you will obviously feel your progress, and you will find our Databricks-Certified-Data-Engineer-Professional test quiz are so useful to help you make progress.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q171-Q176):
NEW QUESTION # 171
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- B. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
- C. With Open Sharing, recipients cannot access Volumes, Models, or notebooks -- only static Delta tables are supported.
- D. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
Answer: C
Explanation:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 172
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
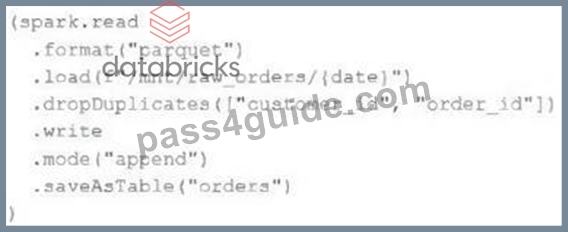
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- D. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- E. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
Answer: A
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
NEW QUESTION # 173
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- B. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- C. When a database is being created, make sure that the LOCATION keyword is used.
- D. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- E. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
Answer: A
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 174
A data engineer is implementing liquid clustering on a Delta Lale table and needs to understand how it affects data management operations. The table will be updated frequently with new data.
The table is an external table and not managed by Unity Catalog. How does liquid clustering in Delta Lake handle new data that is inserted after the initial table creation?
- A. New data remains unclustered until the next OPTIMIZE operation.
- B. New data is automatically clustered during write operations.
- C. New data is rejected if it doesn't match the clustering pattern.
- D. New data is written to a staging area and clustered during scheduled maintenance.
Answer: A
Explanation:
With liquid clustering, newly inserted data is written without being immediately reclustered. The clustering layout is applied incrementally during subsequent OPTIMIZE operations, which reorganize both existing and newly added data to maintain an efficient data layout as the table evolves.
NEW QUESTION # 175
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Which statement describes what the number alongside this field represents?
- A. The total number of jobs that have been run in the workspace.
- B. The job_id is returned in this field.
- C. The job_id and number of times the job has been are concatenated and returned.
- D. The number of times the job definition has been run in the workspace.
- E. The globally unique ID of the newly triggered run.
Answer: E
Explanation:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
NEW QUESTION # 176
......
Our qualified team of Databricks Databricks Certified Data Engineer Professional Exam study material to improve the quality and to match the changes in the syllabus and pattern shared by Databricks-Certified-Data-Engineer-Professional. Our desktop Databricks Databricks-Certified-Data-Engineer-Professional Practice Exam software is designed for all those candidates who want to learn and practice in the actual Databricks Databricks-Certified-Data-Engineer-Professional exam environment.
Pass Databricks-Certified-Data-Engineer-Professional Guarantee: https://www.pass4guide.com/Databricks-Certified-Data-Engineer-Professional-exam-guide-torrent.html
- Real and Error Free www.vce4dumps.com Databricks Databricks-Certified-Data-Engineer-Professional Exam Practice Test 🎹 Immediately open ⮆ www.vce4dumps.com ⮄ and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to obtain a free download 🔈Databricks-Certified-Data-Engineer-Professional Exams Torrent
- Valid Test Databricks-Certified-Data-Engineer-Professional Vce Free 🦧 Valid Dumps Databricks-Certified-Data-Engineer-Professional Pdf 🤽 New Databricks-Certified-Data-Engineer-Professional Exam Prep 🏌 Download ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free by simply entering 【 www.pdfvce.com 】 website 🌮Databricks-Certified-Data-Engineer-Professional Valid Test Bootcamp
- Databricks-Certified-Data-Engineer-Professional Latest Exam Pdf 🎱 Top Databricks-Certified-Data-Engineer-Professional Dumps ⛴ Databricks-Certified-Data-Engineer-Professional Latest Braindumps Free 🔁 Go to website 《 www.pass4test.com 》 open and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download for free ⤵Valid Dumps Databricks-Certified-Data-Engineer-Professional Pdf
- New Databricks-Certified-Data-Engineer-Professional Exam Prep ⚾ Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine 🤞 Latest Databricks-Certified-Data-Engineer-Professional Learning Materials 🔴 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ and easily obtain a free download on ➠ www.pdfvce.com 🠰 👝Databricks-Certified-Data-Engineer-Professional Latest Braindumps Free
- Real and Error Free www.pdfdumps.com Databricks Databricks-Certified-Data-Engineer-Professional Exam Practice Test 😃 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download on ➤ www.pdfdumps.com ⮘ 🩺Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine
- Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine 🥢 Databricks-Certified-Data-Engineer-Professional Latest Braindumps Free ⏬ Valid Databricks-Certified-Data-Engineer-Professional Exam Experience 🦨 Open [ www.pdfvce.com ] and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download exam materials for free ⚔Actual Databricks-Certified-Data-Engineer-Professional Test
- Latest Databricks-Certified-Data-Engineer-Professional VCE Torrent - Databricks-Certified-Data-Engineer-Professional Pass4sure PDF - Databricks-Certified-Data-Engineer-Professional Latest VCE 🥙 Go to website [ www.vceengine.com ] open and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download for free ♣Databricks-Certified-Data-Engineer-Professional Exams Torrent
- Databricks-Certified-Data-Engineer-Professional Dumps Free 🍔 Databricks-Certified-Data-Engineer-Professional Valid Test Bootcamp 🥞 Valid Dumps Databricks-Certified-Data-Engineer-Professional Pdf 🤤 Copy URL ▛ www.pdfvce.com ▟ open and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to download for free 🕓Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine
- Pass Guaranteed 2026 Databricks-Certified-Data-Engineer-Professional: The Best Pdf Databricks Certified Data Engineer Professional Exam Format 🪓 The page for free download of ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ on ⏩ www.verifieddumps.com ⏪ will open immediately ➖Valid Dumps Databricks-Certified-Data-Engineer-Professional Pdf
- Latest Databricks-Certified-Data-Engineer-Professional Test Cram 🍲 Databricks-Certified-Data-Engineer-Professional Valid Test Bootcamp 🌮 Databricks-Certified-Data-Engineer-Professional Intereactive Testing Engine 🗺 Simply search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free download on [ www.pdfvce.com ] 🏧Reliable Databricks-Certified-Data-Engineer-Professional Test Sims
- 100% Pass Quiz Pass-Sure Databricks - Databricks-Certified-Data-Engineer-Professional - Pdf Databricks Certified Data Engineer Professional Exam Format 🖤 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download on ▷ www.examcollectionpass.com ◁ 🥈New Databricks-Certified-Data-Engineer-Professional Exam Prep
- devfolio.co, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes