DOWNLOAD the newest Prep4sures SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI
We have handled professional SPS-C01 practice materials for over ten years. Our experts have many years’ experience in this particular line of business, together with meticulous and professional attitude towards jobs. Their abilities are unquestionable, besides, SPS-C01 Exam Questions are priced reasonably with three kinds: the PDF, Software and APP online. Though the content is the same, but their displays are totally different and functionable.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 3: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 4: Performance and Best Practices | 10% | - Optimization techniques
|
>> Reliable SPS-C01 Practice Materials <<
For the office workers, they are both busy in their job and their family life; for the students, they possibly have to learn or do other things. Our SPS-C01 exam questions are aimed to help them who don’t have enough time to prepare their exam to save their time and energy, and they can spare time to do other things when they prepare the exam. You only need 20-30 hours to practice our software materials and then you can attend the exam. It costs you little time and energy. The SPS-C01 Exam Questions are easy to be mastered and simplified the content of important information. The Snowflake Certified SnowPro Specialty - Snowpark test guide conveys more important information with amount of answers and questions, thus the learning for the examinee is easy and highly efficient.
NEW QUESTION # 359
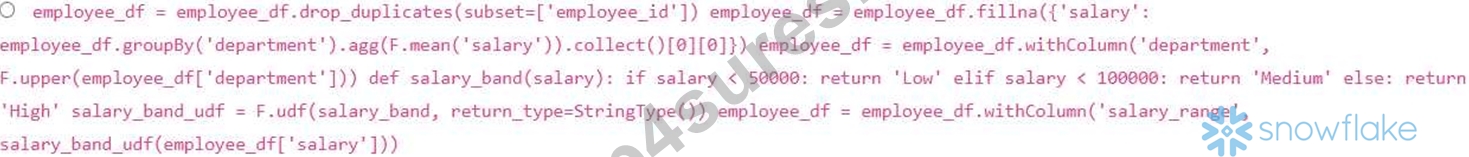
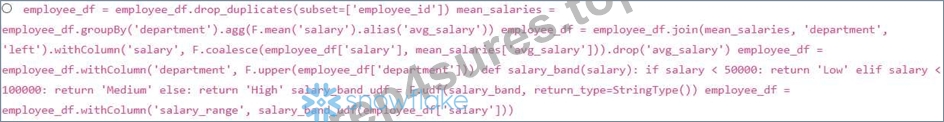
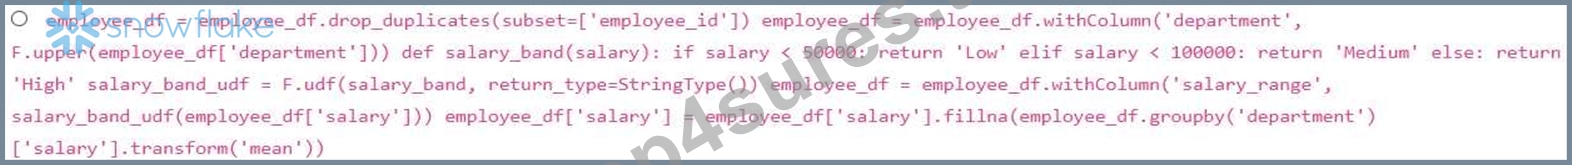
You are using Snowpark to process a DataFrame 'employee df containing employee data, including 'employee_id', 'name' , 'department' , and 'salary'. You need to implement a complex data cleaning and transformation pipeline that involves the following steps: 1. Remove duplicate rows based on 'employee id'. 2. Fill missing 'salary' values with the average salary for the employee's department. 3. Standardize department names by converting them to uppercase. 4. Create a new column 'salary_range' based on the salary. if Salary less than 50k 'Low', greater than 50k and less than 100k 'Medium', greater than 100k 'High'. Which of the following code snippets MOST effectively combines these transformations into a single, readable, and efficient Snowpark pipeline? Assume you have a session object available named 'session' and import necessary modules from 'snowflake.snowpark.functions as F'


Answer: A
Explanation:
Option E is the most efficient and recommended solution for the following reasons: Window Function for Filling Missing Salaries : It uses a window function ('Window.partitionBy('department')') to calculate the average salary for each department efficiently. This is more performant than joining with an aggregated DataFrame or collecting data to the client. No Client-Side Data Handling : All transformations are performed within Snowflake using Snowpark DataFrame operations. This avoids bringing data to the client, which is crucial for performance. Concise 'salary_range' Logic : It uses 'F.when' to define the 'salary_range' column in a concise and readable manner. The chained 'when' calls are a standard way to define conditional column values. Avoids UDF when not Necessary : It avoids using a UDF for calculating 'salary_range' , which generally has overhead compared to built-in functions. Option A computes the average salaries for each department and join again to the original dataframe, which requires more resources. Using UDF is also less performant when there is function available. Option B does not fill nulls before creating salary ranges. Option C collect data on Client side and is inefficient. Option D fillna method is not available and again, the UDF is less performant as it is not necessary.
NEW QUESTION # 360
You are using Snowpark Python to transform a large DataFrame containing customer transaction data'. You need to persist the resulting DataFrame as a new Snowflake table named 'CUSTOMER TRANSACTIONS AGGREGATED', replacing the existing table if it exists. You want to explicitly define the schema of the new table to ensure data types are correctly enforced. Which of the following code snippets achieves this most efficiently and correctly?





Answer: D
Explanation:
Option A is the simplest and most direct way to achieve the desired outcome using the method with the 'overwrite' mode. While defining the schema is important, Snowflake infers the schema from the DataFrame if not explicitly provided. If schema inference isn't working, it should be investigated as a separate issue. Option B requires an intermediary view, which is less efficient. Options C and D are not valid Snowpark options. While you can specify file format related options (e.g. CSV options when writing to cloud storage), 'table_type' isn't one of them. Option E introduces the concept of schema definition, which, while important in general, is unnecessary if Snowflake can infer the correct schema. The question asks for the most efficient and correct answer, which is A.
NEW QUESTION # 361
You're working with Snowpark and want to load data from a Pandas DataFrame into a Snowpark DataFrame. The Pandas DataFrame, 'customer_data' , contains columns with mixed data types (integers, strings, dates). Some columns also contain NULL values. You need to ensure that the data types are correctly inferred by Snowpark, NULL values are handled appropriately, and the resulting Snowpark DataFrame 'snowpark_customers' can be used for further transformations. What is the best approach to achieve this with minimal code and maximum performance?
Answer: C
Explanation:
Relying on schema inference (option C) might not always guarantee the correct data types, especially with dates or mixed-type columns. Explicitly defining the schema (option B) can be verbose and error-prone. Replacing NA/NaN with None and using 'createDataFrame' (option D) is a functional approach, but might not be as performant as the optimized method of 'write_pandaS. Inferring the schema (Option A) might not be fully accurate. Using session.write_pandas leverages internal Snowflake optimizations for data transfer and type handling from Pandas to Snowpark, making it the most efficient.
NEW QUESTION # 362
You have created a Snowpark UDF that uses a custom Python module 'my_module.py', containing a function 'process data'. This module is not available through Anaconda'. You've packaged the module into a zip file named 'my module.zip'. What steps are necessary to deploy this UDF in Snowflake so that it can correctly use the 'my_module'?
Answer: C
Explanation:
Option B is correct. You need to upload the zip file to an internal stage. The 'imports' argument during UDF creation tells Snowflake to unpack the zip and make the module available. Snowflake handles adding the necessary path to 'sys.path', so no manual modification is needed within the UDF. Specifying external stages is possible, but internal stages are preferred for security and performance. Option A is incomplete (doesn't specify how the import relates to the UDF), Option C is technically feasible with external stages but is less preferable. Option D is incorrect as it unnecessary to modify sys.path. Option E specifies 'packages' argument where you would normally include packages available through Anaconda.
NEW QUESTION # 363
You have a Snowpark DataFrame named containing daily sales transactions. The DataFrame includes columns like 'transaction_id' , 'product id', 'sale_date', and 'sale_amount'. You need to perform the following transformations and persist the results: (1) Calculate the total sales amount for each product on a daily basis. (2) Store the aggregated results into a new table named , partitioned by 'sale_date'. (3) Ensure that if the table already exists, the new data is appended to the existing table. Which of the following code blocks achieve these requirements in the most efficient and correct manner?





Answer: B
Explanation:
Option A is the most efficient and correct. It first aggregates the data as required, then uses 'mode('append')' to add new data without overwriting existing data, and for partitioning. Option B will overwrite existing data. Option C is equivalent to option A, but is a less common coding style. Option D renames the default aggregate column name which is less readable but also works correctly. Option E, 'mergeSchema' isn't a valid option to be passed.
NEW QUESTION # 364
......
As sometimes new domains and topics are added to the Prep4sures Snowflake Certified SnowPro Specialty - Snowpark exam syllabus, you’ll be able to get free updates of Snowflake SPS-C01 dumps for 365 days that cover all the latest exam topics. We provide customers instant access to all Snowflake Exams Dumps right after making the payment. Our customer support team is available 24/7 to assist you with all your issues regarding Snowflake SPS-C01 Exam Preparation material.
SPS-C01 Pdf Free: https://www.prep4sures.top/SPS-C01-exam-dumps-torrent.html
What's more, part of that Prep4sures SPS-C01 dumps now are free: https://drive.google.com/open?id=1EFN0mLSDd2K7Q5bTbUh1eZbMrDxownRI