
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by TroytecDumps: https://drive.google.com/open?id=1sXUXBK8VWhqo2E0Rz4nlL_ZYzKg9b0s4
All formats of TroytecDumps's products are immediately usable after purchase. We also offer up to 365 days of free updates so you can prepare as per the Amazon MLA-C01 Latest Exam content. TroytecDumps offers a free demo version of the Amazon Certification Exams so that you can assess the validity of the product before purchasing it.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Certificate Validity Period: | 3 years |
| Exam Format: | Multiple response, Multiple choice |
| Related Certifications: | AWS Certified Data Engineer - Associate AWS Certified Developer - Associate AWS Certified Solutions Architect - Associate |
| Exam Price: | 150 USD |
| Real Exam Qty: | 85 |
| Exam Duration: | 170 minutes |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Available Languages: | Japanese, Korean, Simplified Chinese, English, Traditional Chinese |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
“Quality First, Credibility First, and Service First” is our company’s purpose, we deeply hope our MLA-C01 Study Materials can bring benefits and profits for our customers. So we have been persisting in updating in order to help customers, who are willing to buy our test torrent, make good use of time and accumulate the knowledge. We will guarantee that you will have the opportunity to use the updating system for free.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 240
An ML engineer needs to use an ML model to predict the price of apartments in a specific location.
Which metric should the ML engineer use to evaluate the model ' s performance?
Answer: A
Explanation:
When predicting continuous variables, such as apartment prices, it ' s essential to evaluate the model ' s performance using appropriate regression metrics. The Mean Absolute Error (MAE) is a widely used metric for this purpose.
Understanding Mean Absolute Error (MAE):
MAE measures the average magnitude of errors in a set of predictions, without considering their direction. It calculates the average absolute difference between predicted values and actual values, providing a straightforward interpretation of prediction accuracy.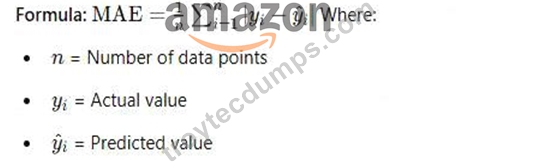
Advantages of MAE:
Interpretability: MAE is expressed in the same units as the target variable, making it easy to understand.
Robustness to Outliers: Unlike metrics that square the errors (e.g., Mean Squared Error), MAE does not disproportionately penalize larger errors, making it more robust to outliers.
Comparison with Other Metrics:
Accuracy, AUC, F1 Score: These metrics are designed for classification tasks, where the goal is to predict discrete labels. They are not suitable for regression problems involving continuous target variables.
Mean Squared Error (MSE): While MSE also measures prediction errors, it squares the differences, giving more weight to larger errors. This can be useful in certain contexts but may be sensitive to outliers.
Conclusion:
For evaluating the performance of a model predicting apartment prices-a continuous variable-MAE is an appropriate and effective metric. It provides a clear indication of the average prediction error in the same units as the target variable, facilitating straightforward interpretation and comparison.
References:
Regression Metrics - GeeksforGeeks
Evaluation Metrics for Your Regression Model - Analytics Vidhya
Regression Metrics for Machine Learning - Machine Learning Mastery
NEW QUESTION # 241
A company has AWS Glue data processing jobs that are orchestrated by an AWS Glue workflow.
The AWS Glue jobs can run on a schedule or can be launched manually.
The company is developing pipelines in Amazon SageMaker Pipelines for ML model development. The pipelines will use the output of the AWS Glue jobs during the data processing phase of model development. An ML engineer needs to implement a solution that integrates the AWS Glue jobs with the pipelines.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
NEW QUESTION # 242
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model ' s performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model ' s final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.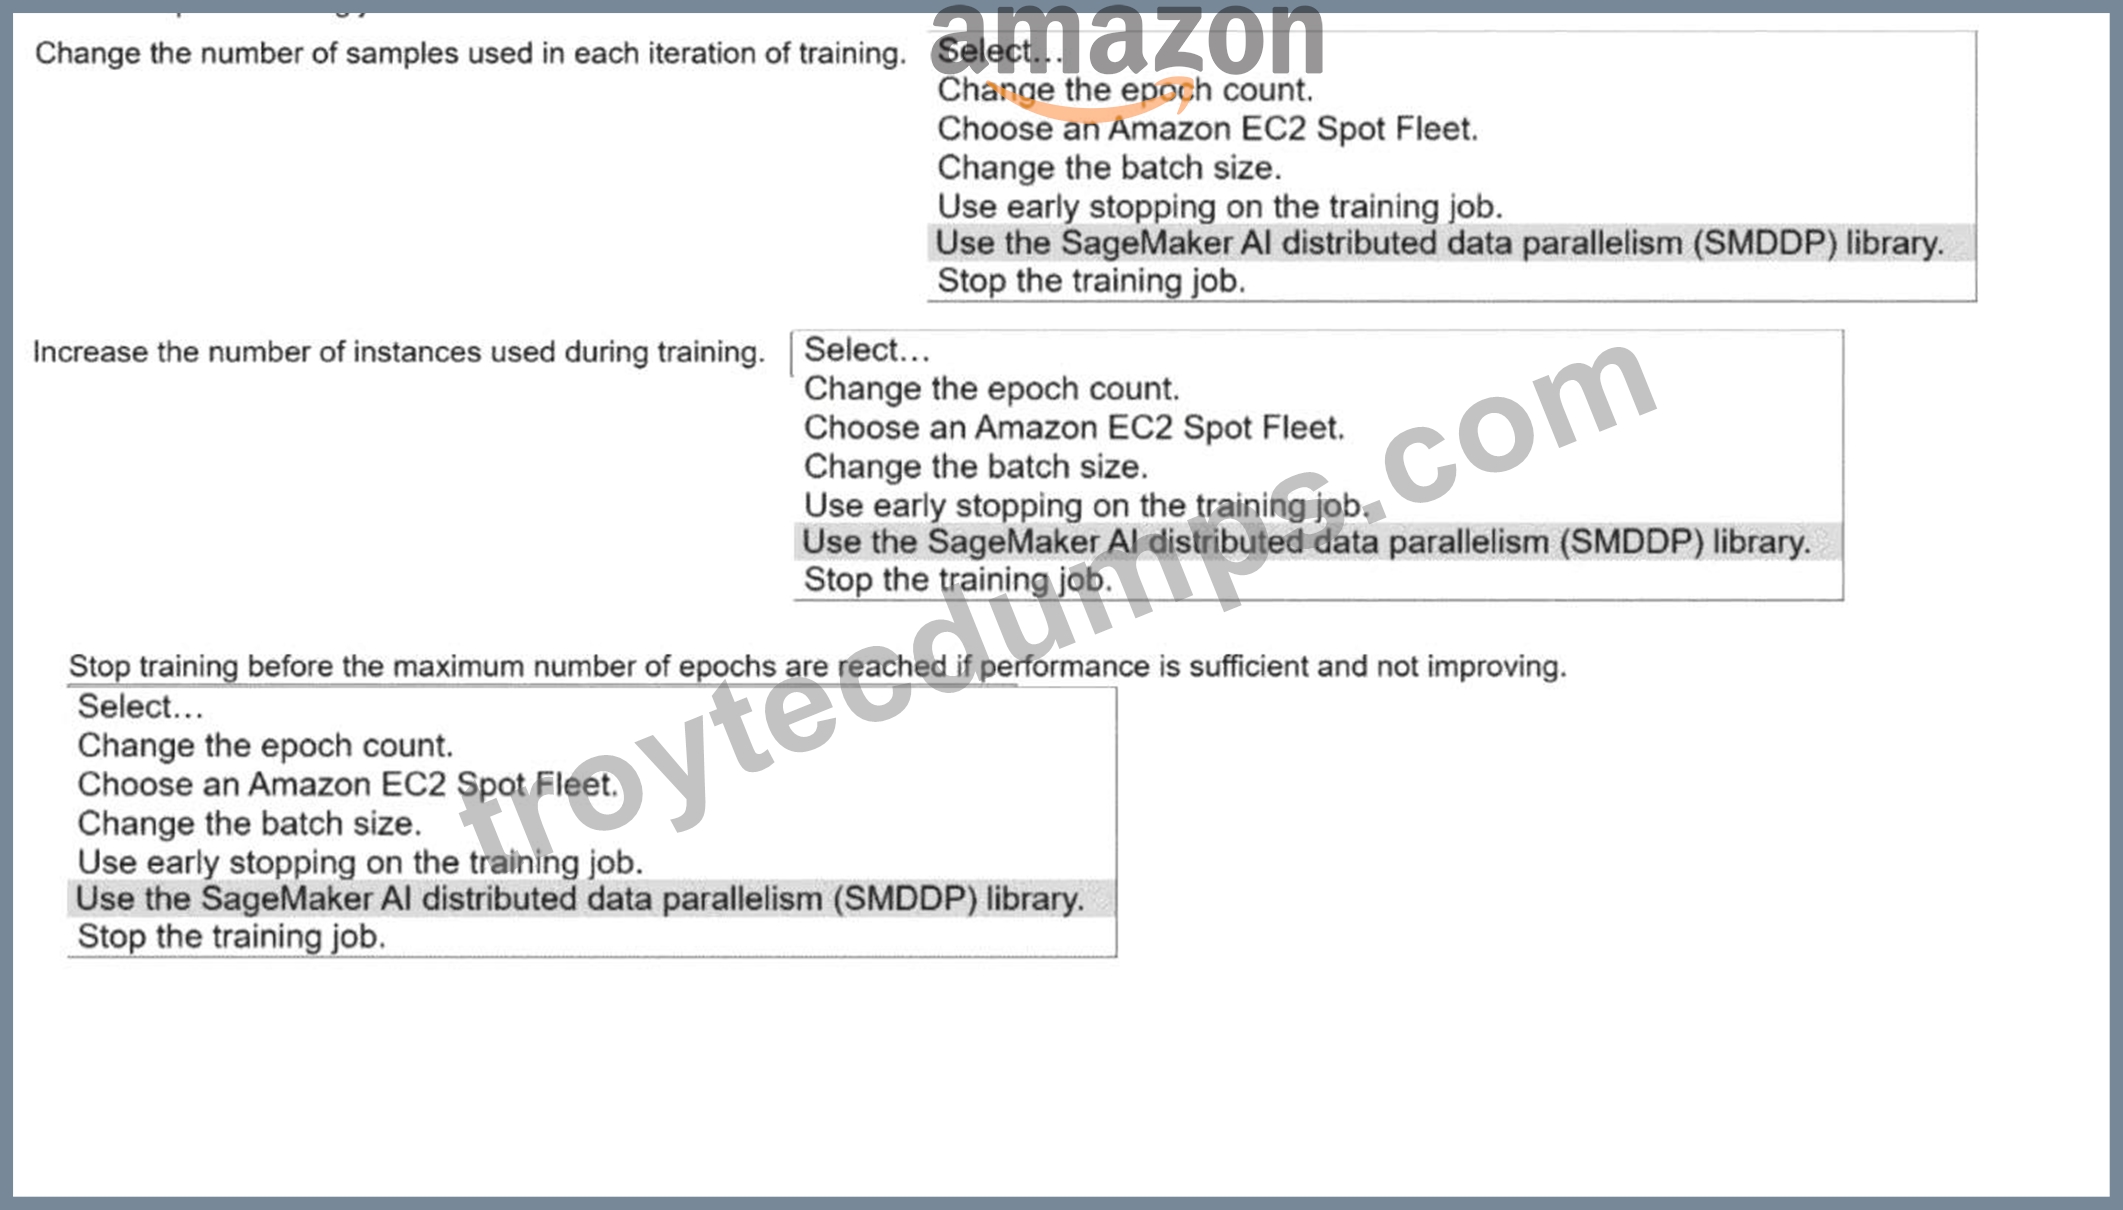
Answer:
Explanation: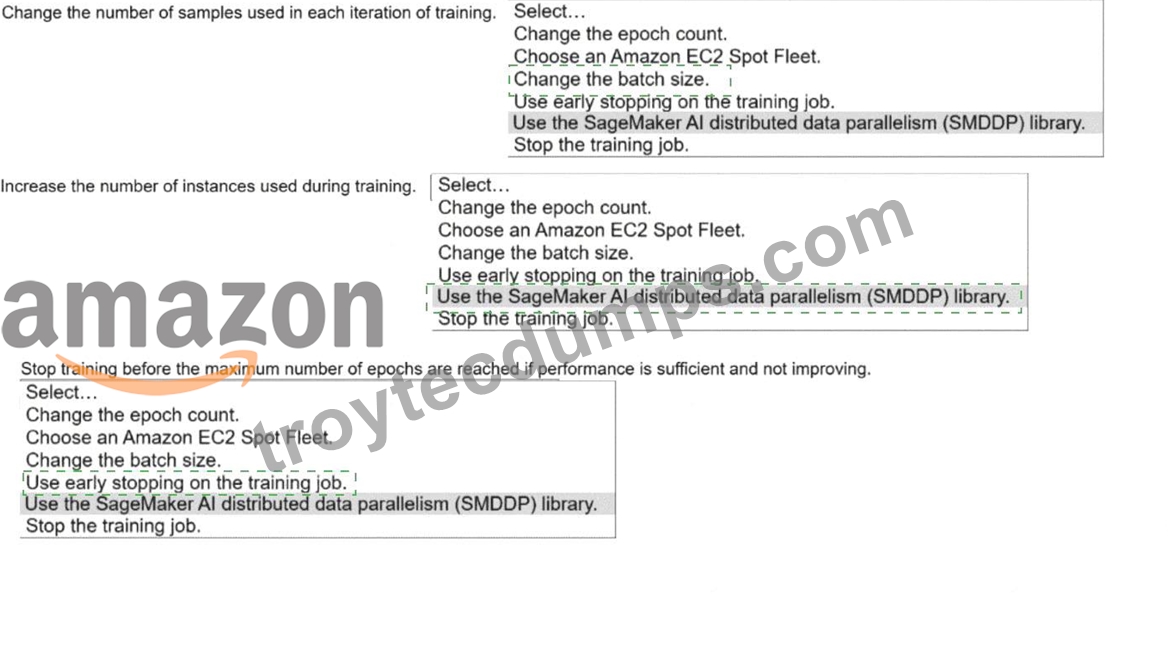
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
NEW QUESTION # 243
A company needs to give its ML engineers appropriate access to training data. The ML engineers must access training data from only their own business group. The ML engineers must not be allowed to access training data from other business groups.
The company uses a single AWS account and stores all the training data in Amazon S3 buckets. All ML model training occurs in Amazon SageMaker.
Which solution will provide the ML engineers with the appropriate access?
Answer: B
Explanation:
By creating IAM policies with specific permissions, you can restrict access to Amazon S3 buckets or objects based on the user ' s business group. These policies can be attached to IAM users or IAM roles associated with the ML engineers, ensuring that each engineer can only access training data belonging to their group.
This approach is secure, scalable, and aligns with AWS best practices for access control.
NEW QUESTION # 244
A company has an ML model that generates text descriptions based on images that customers upload to the company's website. The images can be up to 50 MB in total size.
An ML engineer decides to store the images in an Amazon S3 bucket. The ML engineer must implement a processing solution that can scale to accommodate changes in demand.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
SageMaker Asynchronous Inference is designed for processing large payloads, such as images up to 50 MB, and can handle requests that do not require an immediate response.
It scales automatically based on the demand, minimizing operational overhead while ensuring cost-efficiency.
A script can be used to send inference requests for each image, and the results can be retrieved asynchronously. This approach is ideal for accommodating varying levels of traffic with minimal manual intervention.
NEW QUESTION # 245
......
MLA-C01 Latest Test Prep: https://www.troytecdumps.com/MLA-C01-troytec-exam-dumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by TroytecDumps: https://drive.google.com/open?id=1sXUXBK8VWhqo2E0Rz4nlL_ZYzKg9b0s4