BTW, DOWNLOAD part of Pass4SureQuiz SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1WJWwA5mxPUBc_CWnXzuqV4tSCkPwrMng
Our Snowflake SPS-C01 exam dumps give help to give you an idea about the actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam. You can attempt multiple Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions on the software to improve your performance. Pass4SureQuiz has many Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice questions that reflect the pattern of the real Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam. Pass4SureQuiz allows you to create a Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps according to your preparation. It is easy to create the Snowflake SPS-C01 practice questions by following just a few simple steps. Our Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps are customizable based on the time and type of questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Snowpark Sessions and connection management - Stored procedures and conditional logic - Snowpark DataFrames and query plans - Transformations vs. Actions - Snowpark architecture and core concepts |
| Topic 2: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Complex data pipelines - Window functions |
| Topic 3: Snowpark API for Python | 30% | - Working with Semi-structured data - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - DataFrame creation and manipulation |
| Topic 4: Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Caching strategies - Warehouse sizing for Snowpark - Minimizing data transfer - Query pushdown and optimization - Vectorized UDFs |
>> Relevant SPS-C01 Exam Dumps <<
In real life, every great career must have the confidence to take the first step. When you suspect your level of knowledge, and cramming before the exam, do you think of how to pass the Snowflake SPS-C01 exam with confidence? Do not worry, Pass4SureQuiz is the only provider of training materials that can help you to pass the exam. Our training materials, including questions and answers, the pass rate can reach 100%. With Pass4SureQuiz Snowflake SPS-C01 Exam Training materials, you can begin your first step forward. When you get the certification of Snowflake SPS-C01 exam, the glorious period of your career will start.
NEW QUESTION # 212
Consider two Snowpark DataFrames, 'employees' and 'departments' , with the following schemas: 'employees': (employee_id: Integer Type, employee_name: StringType, department_id: Integer Type, salary: IntegerType) 'departments': (department_id: Integer Type, department_name: StringType, location: StringType) You want to find the highest salary within each department, along with the department name and location, and display the results in a Snowpark DataFrame. Which of the following Snowpark Python code snippets correctly achieves this?




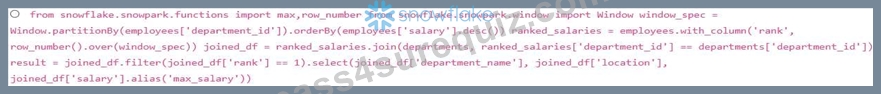
Answer: D
Explanation:
Option A correctly groups the 'employees' DataFrame by 'department_id' , calculates the maximum salary for each department using and then joins the resulting DataFrame with the 'departments' DataFrame on Finally, it selects the required columns: department name, location, and the calculated maximum salary. Option B is not correct as it calculates the rank of all salaries within each department but it does not aggregate on 'department_id'. Option C incorrectly attempts to group by columns from both tables before joining. Option D incorrectly uses the un-joined employees table where rank_salaries are from department_id. Option E will not work due to table names during select. It tries to use 'joined_df table for columns which doesn't have it.
NEW QUESTION # 213
Consider a DataFrame 'products df loaded from a SnoMlake table. It contains a 'features' column of type VARIANT, where each row contains a JSON object representing product features. Your task is to create a new DataFrame where each feature becomes a separate column. You need to dynamically extract these features without knowing the specific feature names in advance. Which of the following approaches could achieve this using Snowpark, and what considerations are important? Choose all that apply:
Answer: C,D
Explanation:
Options B and C are viable approaches. Option B: You can use the native function on the VARIANT column to extract the keys, then iterate over the returned array to dynamically create new columns. This relies on knowing the structure of the data at runtime, but doesn't require a UDE Option C: FLATTEN' offers a SQL-centric way to achieve this, which might be preferable for performance and maintainability. After flattening, you would typically pivot the data. Option A is possible with IJDFs, but might be less performant than using native functions or FLATTEN. Option D is incorrect; dynamic column creation is possible. While OBJECT_CONSTRUCT() can construct JSON objects, it's not directly helpful for dynamically extracting JSON properties into separate columns in this scenario (Option E).
NEW QUESTION # 214
You are tasked with creating a Snowpark DataFrame from a series of large Parquet files stored in an external stage 'my_stage' . The files contain customer transaction data, but some files are corrupted and cause errors during DataFrame creation. You want to implement a solution that skips the corrupted files and logs the filenames of those files to a table named 'failed_files'. Assuming you have a Snowpark session 'session' and a UDF that inserts filenames into the 'failed_files' table, which of the following approaches is the MOST efficient and robust way to achieve this, while minimizing impact on performance and maintaining data integrity? Consider that you don't have direct control over the file format and data quality within the stage.
Answer: D
Explanation:
Option C is the most efficient and robust. 'COPY INTO with = CONTINUE directly leverages Snowflake's optimized loading capabilities to handle file-level errors gracefully. The 'VALIDATION_MODE allows identifying errored files before the load process. A, B, D and E involve more complex and potentially less efficient workarounds within Snowpark itself.
NEW QUESTION # 215
When creating UDFs/UDTFs in Snowpark Python, what are the advantages of explicitly specifying data types (either via Python type hints or the registration API) compared to relying on implicit type inference?
Answer: B,D,E
Explanation:
Specifying data types explicitly offers several benefits. (A) Explicit data types allow Snowflake to optimize query execution by eliminating the need to infer types at runtime, resulting in improved performance. (B) Type hints and registration APIs enhance code readability and maintainability by clearly indicating the expected data types. (C) Explicit data types enable early detection of type-related errors during development, preventing unexpected runtime failures. (D) While Snowflake can perform some implicit conversions, explicit type declarations don't guarantee automatic conversion in all scenarios and manual casting might still be needed. (E) deployment time is not significantly affected.
NEW QUESTION # 216
You have a Snowpark Python application that reads data from a Snowflake table, performs several transformations, and then writes the results back to a new Snowflake table. The transformations involve complex calculations and aggregations. During testing, you observe that the application is consuming a significant amount of credits. Which of the following optimization strategies would be MOST effective in reducing the credit consumption of your Snowpark application?
Answer: B,E
Explanation:
Converting Python UDFs to Java UDTFs can significantly improve performance and reduce credit consumption because Java UDTFs execute within the Snowflake engine. Minimizing data transfer by pushing down transformations and using stored procedures reduces the amount of data processed and transferred, thus reducing credit consumption. Disabling auto-scaling might reduce peak credit consumption but could also increase overall execution time and potentially increase costs if the warehouse is under-sized. Caching can help in some cases but introduces memory management complexities. Snowflake automatically handles index management and query optimization; explicitly specifying hints is generally not necessary and using cache might not be suitable for large datasets.
NEW QUESTION # 217
......
Pass4SureQuiz proudly says that its product is accurate and trustworthy because it was formulated according to the prescribed content of the Snowflake SPS-C01 actual test. We offer Snowflake SPS-C01 Exam Questions free updates for up to 12 months after purchasing. These free updates of actual SPS-C01 questions will follow the fresh updates in the exam content.
SPS-C01 Reliable Test Test: https://www.pass4surequiz.com/SPS-C01-exam-quiz.html
BTW, DOWNLOAD part of Pass4SureQuiz SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1WJWwA5mxPUBc_CWnXzuqV4tSCkPwrMng