Frankly speaking, it is difficult to get the Databricks-Certified-Data-Engineer-Professional certificate without help. Usually, the time you invest to prepare the exam is long. Now, all of your worries can be wiped out because of our Databricks-Certified-Data-Engineer-Professional exam questions. Some people worry about that some difficult knowledge is hard to understand or the Databricks-Certified-Data-Engineer-Professional test guide is not suitable for them. Actually, the difficult parts of the exam have been simplified, which will be easy for you to understand. Also, there will be examples, simulations and charts to make explanations vivid. In order to aid you to memorize the Databricks Certified Data Engineer Professional Exam exam cram better, we have integrated knowledge structure. You will clearly know what you are learning and which part you need to learn carefully. You will regret if you give up challenging yourself.
| Section | Objectives |
|---|---|
| Databricks Lakehouse Platform Architecture | - Medallion architecture (Bronze, Silver, Gold) - Data governance concepts (Unity Catalog basics) - Workspace and cluster architecture |
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - Structured Streaming fundamentals - ETL pipeline design patterns |
| Data Modeling and Transformation | - Spark SQL transformations - Performance optimization techniques - Dimensional modeling concepts |
| Delta Lake and Data Management | - Delta Lake transactions and ACID properties - Time travel and versioning - Schema evolution and enforcement |
| Production Pipelines and Orchestration | - Error handling and recovery strategies - Job scheduling and monitoring - Databricks Workflows |
>> Online Databricks-Certified-Data-Engineer-Professional Version <<
Our Databricks-Certified-Data-Engineer-Professional study practice guide takes full account of the needs of the real exam and conveniences for the clients. Our Databricks-Certified-Data-Engineer-Professional certification questions are close to the real exam and the questions and answers of the test bank cover the entire syllabus of the real exam and all the important information about the exam. Our Databricks-Certified-Data-Engineer-Professional learning dump can stimulate the real exam’s environment to make the learners be personally on the scene and help the learners adjust the speed when they attend the real exam. To be convenient for the learners, our Databricks-Certified-Data-Engineer-Professional Certification Questions provide the test practice software to help the learners check their learning results at any time.
NEW QUESTION # 123
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: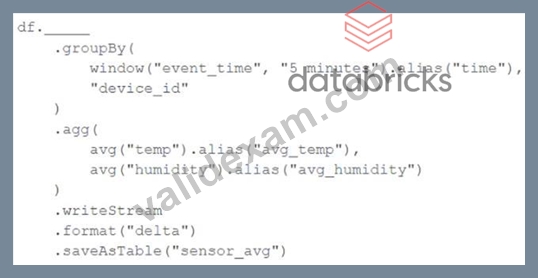
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: E
Explanation:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
NEW QUESTION # 124
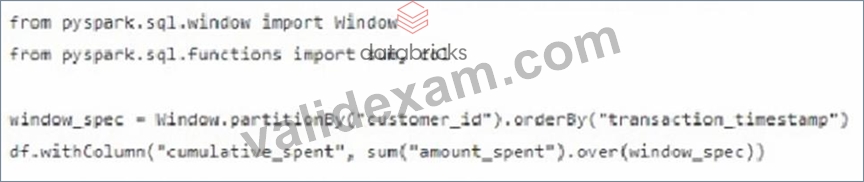
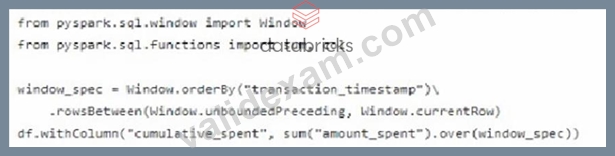
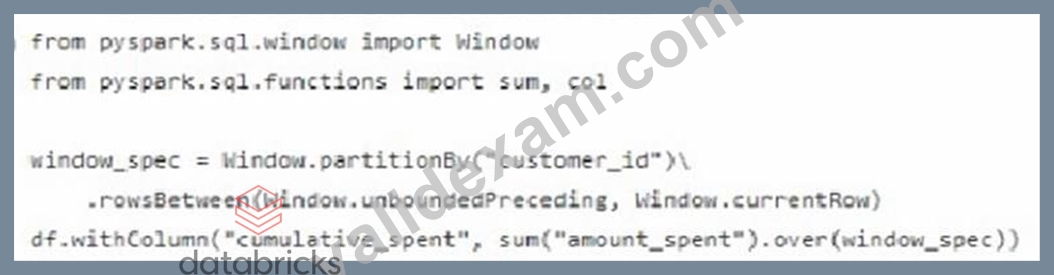
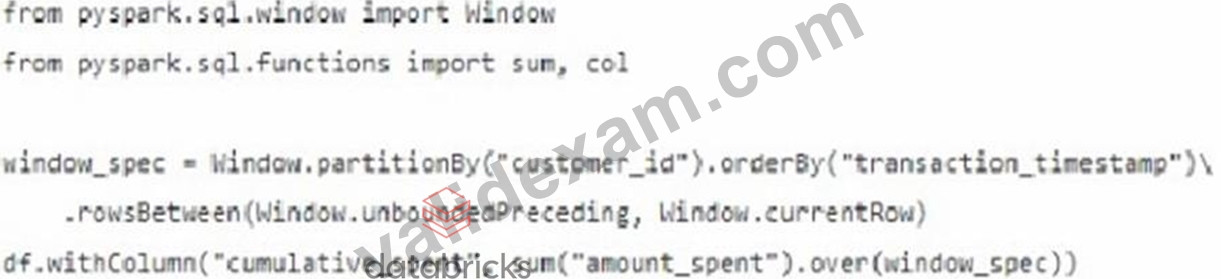
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
Answer: D
Explanation:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
NEW QUESTION # 125
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table")
\
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
Answer: B
Explanation:
Delta Lake's data skipping relies on partitioning and clustering (such as Z-ordering) on the filtered columns. If event_date is neither a partition column nor included in the table's clustering strategy, Spark must scan most files because file-level statistics cannot be effectively used to prune irrelevant data.
NEW QUESTION # 126
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
Answer: D
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 127
A platform team lead is responsible for automating the individual teams attribution towards SQL Warehouse usage. The requirement is to identify the SQL warehouse usage at the individual user's level and generate a daily report to be shared with an executive team that includes leaders from all business units. How should the platform lead generate an automated report that can be shared daily?
Answer: A
Explanation:
System tables provide authoritative audit and billing data needed for per-user SQL Warehouse attribution. Creating a dashboard with a scheduled daily refresh automates report generation and ensures executives receive consistent, up-to-date insights without needing to run queries themselves.
NEW QUESTION # 128
......
In order to pass Databricks certification Databricks-Certified-Data-Engineer-Professional exam, selecting the appropriate training tools is very necessary. And professional study materials about Databricks certification Databricks-Certified-Data-Engineer-Professional exam is a very important part. Our ValidExam can have a good and quick provide of professional study materials about Databricks Certification Databricks-Certified-Data-Engineer-Professional Exam. Our ValidExam IT experts are very experienced and their study materials are very close to the actual exam questions, almost the same. ValidExam is a convenient website specifically for people who want to take the certification exams, which can effectively help the candidates to pass the exam.
Databricks-Certified-Data-Engineer-Professional Latest Exam Materials: https://www.validexam.com/Databricks-Certified-Data-Engineer-Professional-latest-dumps.html