Your dream is very high, so you have to find a lot of material to help you prepare for the exam. LatestCram Databricks Databricks-Certified-Professional-Data-Engineer Exam Materials can help you to achieve your ideal. LatestCram Databricks Databricks-Certified-Professional-Data-Engineer exam materials is a collection of experience and innovation from highly certified IT professionals in the field. Our products will let you try all the problems that may arise in a really examinations. We can give you a guarantee, to ensure that candidates get a 100% correct answer.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Medallion Architecture implementation - Delta Lake table design - Schema design and management |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Topic 3: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Topic 4: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 5: Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Topic 6: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 7: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Topic 8: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Topic 9: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Topic 10: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
>> Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives <<
About the materials that relate to Databricks Databricks-Certified-Professional-Data-Engineer exam, many websites can offer the exam materials. But these websites can't guarantee the quality of the exam dumps, meanwhile when you fail the exam, they can't also give you FULL REFUND guarantee. Compared with common reference materials, LatestCram Databricks Databricks-Certified-Professional-Data-Engineer certification training materials is the tool that worth your use. With the help of LatestCram Databricks Databricks-Certified-Professional-Data-Engineer Real Questions and answers, you can absolutely well prepare for the exam and pass the exam with ease. If you want to great development in IT industry, you need to take IT certification exam. If you want to pass your IT certification test successfully, it is necessary for you to use LatestCram exam dumps.
NEW QUESTION # 30
Create a sales database using the DBFS location 'dbfs:/mnt/delta/databases/sales.db/'
Answer: E
Explanation:
Explanation
The answer is
CREATE DATABASE sales LOCATION 'dbfs:/mnt/delta/databases/sales.db/'
Note: with the introduction of the Unity catalog and three-layer namespace usage of SCHEMA and DATABASE is interchangeable
NEW QUESTION # 31
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 32
When defining external tables using formats CSV, JSON, TEXT, BINARY any query on the exter-nal tables caches the data and location for performance reasons, so within a given spark session any new files that may have arrived will not be available after the initial query. How can we address this limitation?
Answer: D
Explanation:
Explanation
The answer is REFRESH TABLE table_name
REFRESH TABLE table_name will force Spark to refresh the availability of external files and any changes.
When spark queries an external table it caches the files associated with it, so that way if the table is queried again it can use the cached files so it does not have to retrieve them again from cloud object storage, but the drawback here is that if new files are available Spark does not know until the Refresh command is ran.
NEW QUESTION # 33
A nightly job ingests data into a Delta Lake table using the following code: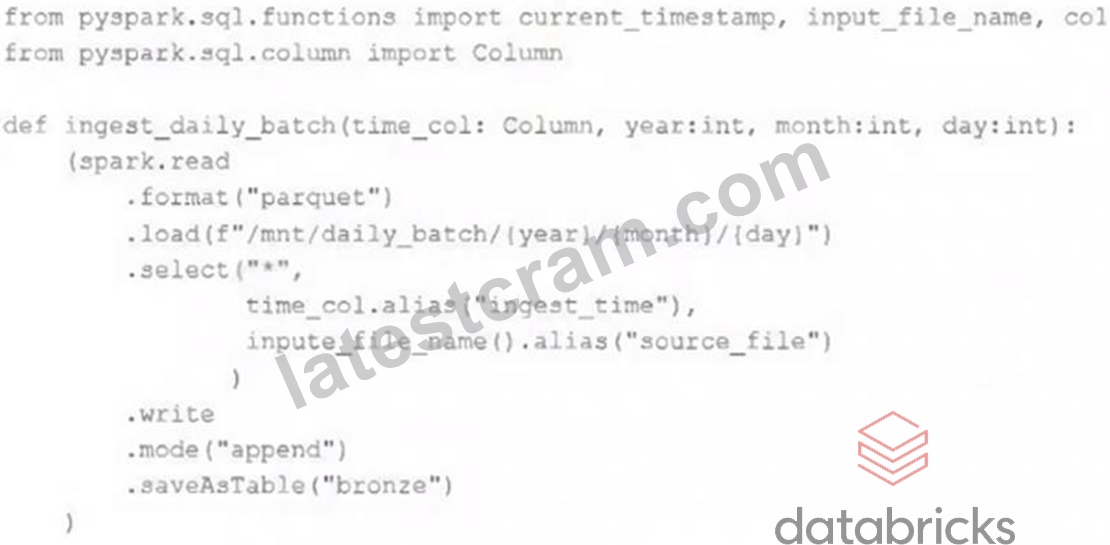
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
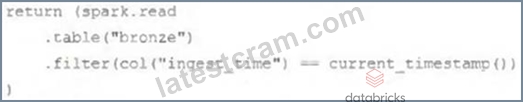
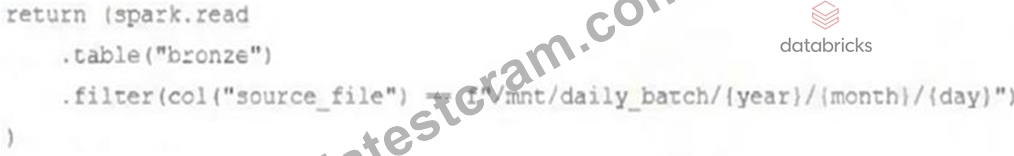
Answer: D
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 34
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: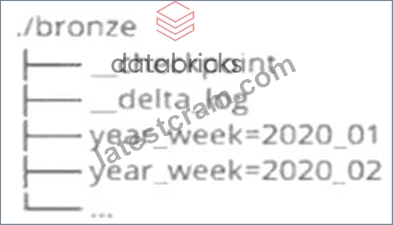
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: D
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Checkpointing" section.
NEW QUESTION # 35
......
However, you should keep in mind that to get success in the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam is not an easy task. It is a challenging exam and not a traditional exam. But complete Databricks Databricks-Certified-Professional-Data-Engineer exam preparation can enable you to crack the Databricks Databricks-Certified-Professional-Data-Engineer exam easily. For the quick and complete Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam preparation you can trust Databricks-Certified-Professional-Data-Engineer exam practice test questions. The Databricks Databricks-Certified-Professional-Data-Engineer exam practice test questions have already helped many Databricks Databricks-Certified-Professional-Data-Engineer exam candidates in their preparation and success and you can also trust "LatestCram" exam questions and start preparing today.
Databricks-Certified-Professional-Data-Engineer Reliable Test Materials: https://www.latestcram.com/Databricks-Certified-Professional-Data-Engineer-exam-cram-questions.html