
P.S. Free & New AIF-C01 dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1c8WcOYWP0pM0_N-FWTcorrfpOfNZra77
Persistence and proficiency made our experts dedicated in this line over so many years on the AIF-C01 study guide. Their passing rates of our AIF-C01 exam materials are over 98 and more, which is quite riveting outcomes. After using our AIF-C01 practice engine, you will have instinctive intuition to conquer all problems and difficulties in your review. And with the simplified the content, you will find it is easy and interesting to study with our AIF-C01 learning questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> AIF-C01 Pass4sure Study Materials <<
If you want to get through the AIF-C01 practice exam quickly with less time and efforts, our learning materials is definitely your best option. One or two days' preparation and remember the correct AIF-C01 test answers, getting the certification will be simple for our candidates. Free trials of AIF-C01 Exam PDF are available for everyone and great discounts are waiting for you. Join us and realize your dream.
NEW QUESTION # 59
An airline company wants to build a conversational AI assistant to answer customer questions about flight schedules, booking, and payments. The company wants to use large language models (LLMs) and a knowledge base to create a text-based chatbot interface.
Which solution will meet these requirements with the LEAST development effort?
Answer: C
Explanation:
The airline company aims to build a conversational AI assistant using large language models (LLMs) and a knowledge base to create a text-based chatbot with minimal development effort. Retrieval Augmented Generation (RAG) on Amazon Bedrock is an ideal solution because it combines LLMs with a knowledge base to provide accurate, contextually relevant responses without requiring extensive model training or custom development. RAG retrieves relevant information from a knowledge base and uses an LLM to generate responses, simplifying the development process.
Exact Extract from AWS AI Documents:
From the AWS Bedrock User Guide:
"Retrieval Augmented Generation (RAG) in Amazon Bedrock enables developers to build conversational AI applications by combining foundation models with external knowledge bases. This approach minimizes development effort by leveraging pre-trained models and integrating them with data sources, such as FAQs or databases, to provide accurate and contextually relevant responses." (Source: AWS Bedrock User Guide, Retrieval Augmented Generation) Detailed Explanation:
Option A: Train models on Amazon SageMaker Autopilot.SageMaker Autopilot is designed for automated machine learning (AutoML) tasks like classification or regression, not for building conversational AI with LLMs and knowledge bases. It requires significant data preparation and is not optimized for chatbot development, making it less suitable.
Option B: Develop a Retrieval Augmented Generation (RAG) agent by using Amazon Bedrock.This is the correct answer. RAG on Amazon Bedrock allows the company to use pre-trained LLMs and integrate them with a knowledge base (e.g., flight schedules or FAQs) to build a chatbot with minimal effort. It avoids the need for extensive training or coding, aligning with the requirement for least development effort.
Option C: Create a Python application by using Amazon Q Developer.While Amazon Q Developer can assist with code generation, building a chatbot from scratch in Python requires significant development effort, including integrating LLMs and a knowledge base manually, which is more complex than using RAG on Bedrock.
Option D: Fine-tune models on Amazon SageMaker Jumpstart.Fine-tuning models on SageMaker Jumpstart requires preparing training data and customizing LLMs, which involves more effort than using a pre-built RAG solution on Bedrock. This option is not the least effort-intensive.
References:
AWS Bedrock User Guide: Retrieval Augmented Generation (https://docs.aws.amazon.com/bedrock/latest
/userguide/rag.html)
AWS AI Practitioner Learning Path: Module on Generative AI and Conversational AI Amazon Bedrock Developer Guide: Building Conversational AI (https://aws.amazon.com/bedrock/)
NEW QUESTION # 60
A company wants to create an application to summarize meetings by using meeting audio recordings.
Select and order the correct steps from the following list to create the application. Each step should be selected one time or not at all. (Select and order THREE.)
* Convert meeting audio recordings to meeting text files by using Amazon Polly.
* Convert meeting audio recordings to meeting text files by using Amazon Transcribe.
* Store meeting audio recordings in an Amazon S3 bucket.
* Store meeting audio recordings in an Amazon Elastic Block Store (Amazon EBS) volume.
* Summarize meeting text files by using Amazon Bedrock.
* Summarize meeting text files by using Amazon Lex.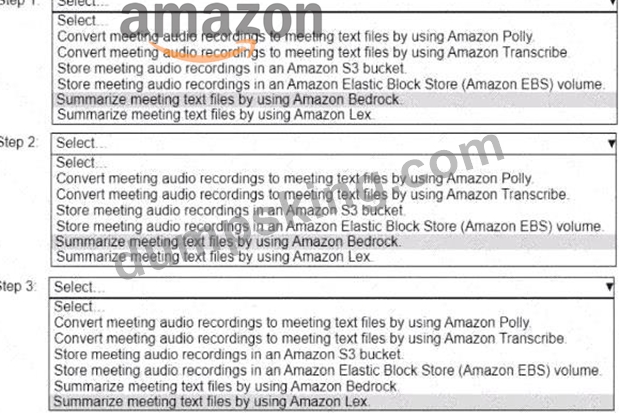
Answer:
Explanation: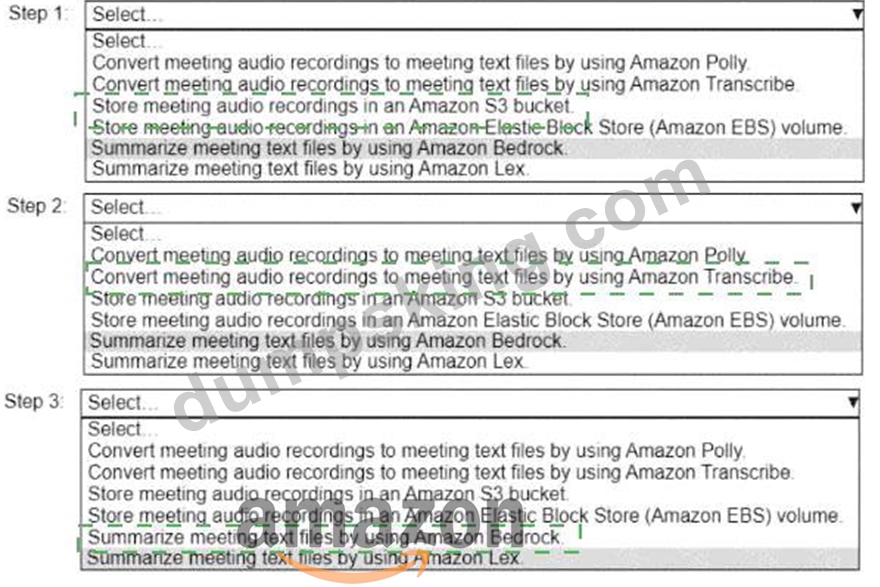
Explanation:
Step 1: Store meeting audio recordings in an Amazon S3 bucket.
Step 2: Convert meeting audio recordings to meeting text files by using Amazon Transcribe.
Step 3: Summarize meeting text files by using Amazon Bedrock.
The company wants to create an application to summarize meeting audio recordings, which requires a sequence of steps involving storage, speech-to-text conversion, and text summarization. Amazon S3 is the recommended storage service for audio files, Amazon Transcribe converts audio to text, and Amazon Bedrock provides generative AI capabilities for summarization. These three steps, in this order, create an efficient workflow for the application.
Exact Extract from AWS AI Documents:
From the Amazon Transcribe Developer Guide:
"Amazon Transcribe uses deep learning to convert audio files into text, supporting applications such as meeting transcription. Audio files can be stored in Amazon S3, and Transcribe can process them directly from an S3 bucket." From the AWS Bedrock User Guide:
"Amazon Bedrock provides foundation models that can perform text summarization, enabling developers to build applications that generate concise summaries from text data, such as meeting transcripts." (Source: Amazon Transcribe Developer Guide, Introduction to Amazon Transcribe; AWS Bedrock User Guide, Text Generation and Summarization) Detailed Explanation:
Step 1: Store meeting audio recordings in an Amazon S3 bucket.Amazon S3 is the standard storage service for audio files in AWS workflows, especially for integration with services like Amazon Transcribe. Storing the recordings in S3 allows Transcribe to access and process them efficiently. This is the first logical step.
Step 2: Convert meeting audio recordings to meeting text files by using Amazon Transcribe.Amazon Transcribe is designed for automatic speech recognition (ASR), converting audio files (stored in S3) into text.
This step is necessary to transform the meeting recordings into a format that can be summarized.
Step 3: Summarize meeting text files by using Amazon Bedrock.Amazon Bedrock provides foundation models capable of generative AI tasks like text summarization. Once the audio is converted to text, Bedrock can summarize the meeting transcripts, completing the application's requirements.
Unused Options Analysis:
Convert meeting audio recordings to meeting text files by using Amazon Polly.Amazon Polly is a text-to- speech service, not for converting audio to text. This option is incorrect and not used.
Store meeting audio recordings in an Amazon Elastic Block Store (Amazon EBS) volume.Amazon EBS is for block storage, typically used for compute instances, not for storing files for processing by services like Transcribe. S3 is the better choice, so this option is not used.
Summarize meeting text files by using Amazon Lex.Amazon Lex is for building conversational interfaces (chatbots), not for text summarization. Bedrock is the appropriate service for summarization, so this option is not used.
Hotspot Selection Analysis:
The task requires selecting and ordering three steps from the list, with each step used exactly once or not at all. The selected steps-storing in S3, converting with Transcribe, and summarizing with Bedrock-form a complete and logical workflow for the application.
References:
Amazon Transcribe Developer Guide: Introduction to Amazon Transcribe (https://docs.aws.amazon.com
/transcribe/latest/dg/what-is.html)
AWS Bedrock User Guide: Text Generation and Summarization (https://docs.aws.amazon.com/bedrock/latest
/userguide/what-is-bedrock.html)
AWS AI Practitioner Learning Path: Module on Speech-to-Text and Generative AI Amazon S3 User Guide: Storing Data for Processing (https://docs.aws.amazon.com/AmazonS3/latest
/userguide/Welcome.html)
NEW QUESTION # 61
An education provider is building a question and answer application that uses a generative AI model to explain complex concepts. The education provider wants to automatically change the style of the model response depending on who is asking the question. The education provider will give the model the age range of the user who has asked the question.
Which solution meets these requirements with the LEAST implementation effort?
Answer: C
Explanation:
Adding a role description to the prompt context is a straightforward way to instruct the generative AI model to adjust its response style based on the user's age range. This method requires minimal implementation effort as it does not involve additional training or complex logic.
* Option B (Correct): "Add a role description to the prompt context that instructs the model of the age range that the response should target": This is the correct answer because it involves the least implementation effort while effectively guiding the model to tailor responses according to the age range.
* Option A: "Fine-tune the model by using additional training data" is incorrect because it requires significant effort in gathering data and retraining the model.
* Option C: "Use chain-of-thought reasoning" is incorrect as it involves complex reasoning that may not directly address the need to adjust response style based on age.
* Option D: "Summarize the response text depending on the age of the user" is incorrect because it involves additional processing steps after generating the initial response, increasing complexity.
AWS AI Practitioner References:
* Prompt Engineering Techniques on AWS: AWS recommends using prompt context effectively to guide generative models in providing tailored responses based on specific user attributes.
NEW QUESTION # 62
Which functionality does Amazon SageMaker Clarify provide?
Answer: B
Explanation:
Exploratory data analysis (EDA) involves understanding the data by visualizing it, calculating statistics, and creating correlation matrices. This stage helps identify patterns, relationships, and anomalies in the data, which can guide further steps in the ML pipeline.
Option C (Correct): "Exploratory data analysis": This is the correct answer as the tasks described (correlation matrix, calculating statistics, visualizing data) are all part of the EDA process.
Option A: "Data pre-processing" is incorrect because it involves cleaning and transforming data, not initial analysis.
Option B: "Feature engineering" is incorrect because it involves creating new features from raw data, not analyzing the data's existing structure.
Option D: "Hyperparameter tuning" is incorrect because it refers to optimizing model parameters, not analyzing the data.
AWS AI Practitioner Reference:
Stages of the Machine Learning Pipeline: AWS outlines EDA as the initial phase of understanding and exploring data before moving to more specific preprocessing, feature engineering, and model training stages.
NEW QUESTION # 63
Which feature of Amazon OpenSearch Service gives companies the ability to build vector database applications?
Answer: A
Explanation:
Amazon OpenSearch Service (formerly Amazon Elasticsearch Service) has introduced capabilities to support vector search, which allows companies to build vector database applications. This is particularly useful in machine learning, where vector representations (embeddings) of data are often used to capture semantic meaning.
Scalable index management and nearest neighbor search capability are the core features enabling vector database functionalities in OpenSearch. The service allows users to index high-dimensional vectors and perform efficient nearest neighbor searches, which are crucial for tasks such as recommendation systems, anomaly detection, and semantic search.
Here is why option C is the correct answer:
* Scalable Index Management: OpenSearch Service supports scalable indexing of vector data. This means you can index a large volume of high-dimensional vectors and manage these indexes in a cost- effective and performance-optimized way. The service leverages underlying AWS infrastructure to ensure that indexing scales seamlessly with data size.
* Nearest Neighbor Search Capability: OpenSearch Service's nearest neighbor search capability allows for fast and efficient searches over vector data. This is essential for applications like product recommendation engines, where the system needs to quickly find the most similar items based on a user's query or behavior.
* AWS AI Practitioner References:
* According to AWS documentation, OpenSearch Service's support for nearest neighbor search using vector embeddings is a key feature for companies building machine learning applications that require similarity search.
* The service uses Approximate Nearest Neighbors (ANN) algorithms to speed up searches over large datasets, ensuring high performance even with large-scale vector data.
The other options do not directly relate to building vector database applications:
* A. Integration with Amazon S3 for object storage is about storing data objects, not vector-based searching or indexing.
* B. Support for geospatial indexing and queries is related to location-based data, not vectors used in machine learning.
* D. Ability to perform real-time analysis on streaming data relates to analyzing incoming data streams, which is different from the vector search capabilities.
NEW QUESTION # 64
......
We do admire our experts' familiarity and dedication with the industry all these years. By their help, you can qualify yourself with AIF-C01 guide materials. Our experts pass onto the exam candidate their know-how of coping with the exam by our AIF-C01 Exam Braindumps. Exam candidates are susceptible to the influence of ads, so our experts' know-how is impressive to pass the AIF-C01 exam instead of making financial reward solely.
AIF-C01 Reliable Dumps: https://www.dumpsking.com/AIF-C01-testking-dumps.html
What's more, part of that DumpsKing AIF-C01 dumps now are free: https://drive.google.com/open?id=1c8WcOYWP0pM0_N-FWTcorrfpOfNZra77