Exam Certified-Data-Engineer-Professional Preparation | Certified-Data-Engineer-Professional Flexible Testing Engine

Although we have three versions of our Certified-Data-Engineer-Professional exam braindumps: the PDF, Software and APP online, i do think the most amazing version is the APP online. This version of our Certified-Data-Engineer-Professional study materials can be supportive to offline exercise on the condition that you practice it without mobile data. So even trifling mistakes can be solved by using our Certified-Data-Engineer-Professional Practice Questions, as well as all careless mistakes you may make.
| Section | Weight | Objectives |
|---|
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering
- Apply dimensional modeling techniques
|
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Implement scalable Python/SQL code and project structures
|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
>> Exam Certified-Data-Engineer-Professional Preparation <<
Certified-Data-Engineer-Professional Flexible Testing Engine, Latest Certified-Data-Engineer-Professional Cram Materials
Our key priority is to provide such authentic Databricks Certified-Data-Engineer-Professional Exam Material which helps the candidate qualify for Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam on the very first attempt. This means that you can download the product right after purchasing and start your journey toward your big career.
Databricks Certified Data Engineer Professional Sample Questions (Q193-Q198):
NEW QUESTION # 193
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- B. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- C. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date. - D. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- E. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
Answer: D
Explanation:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
NEW QUESTION # 194
Which statement regarding spark configuration on the Databricks platform is true?
- A. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- B. When the same spar configuration property is set for an interactive to the same interactive cluster.
- C. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- D. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- E. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
Answer: C
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
NEW QUESTION # 195
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
Answer: B
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
NEW QUESTION # 196
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
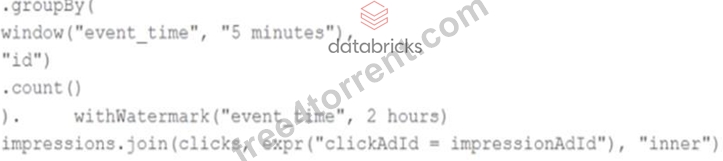
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
- B. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
- C. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
- D. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
Answer: D
NEW QUESTION # 197
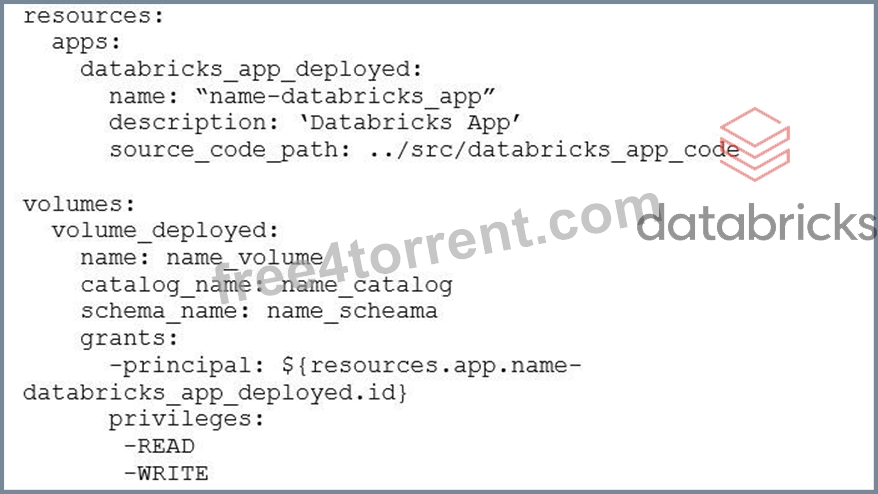
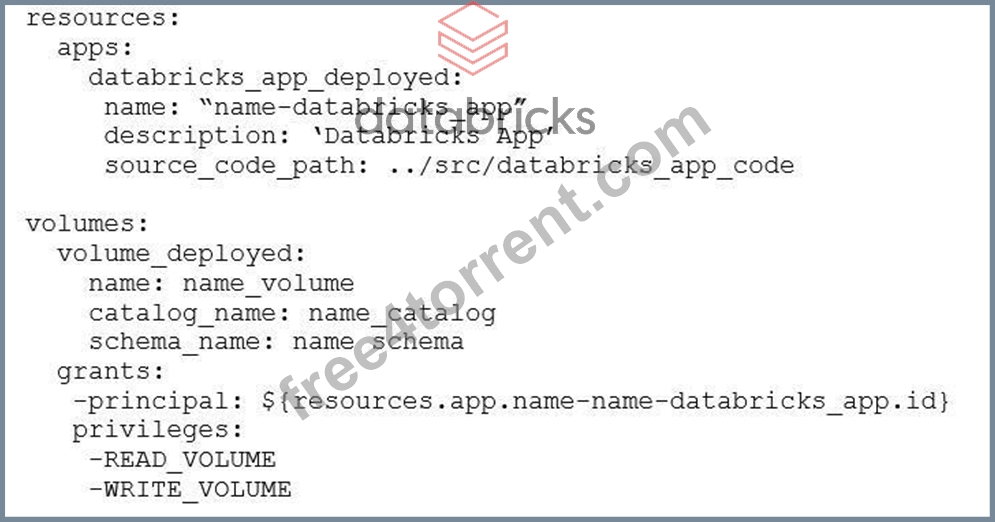
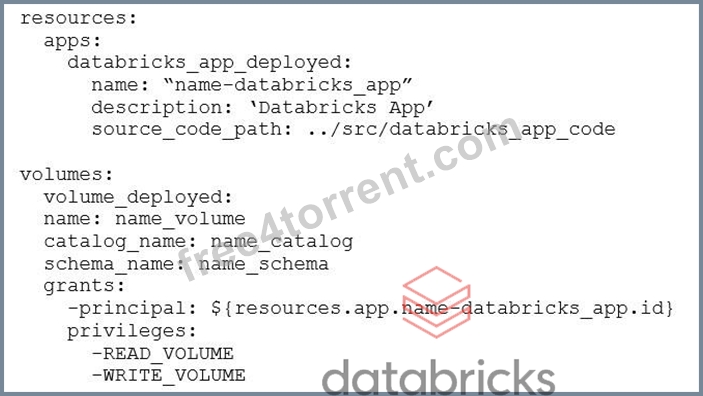
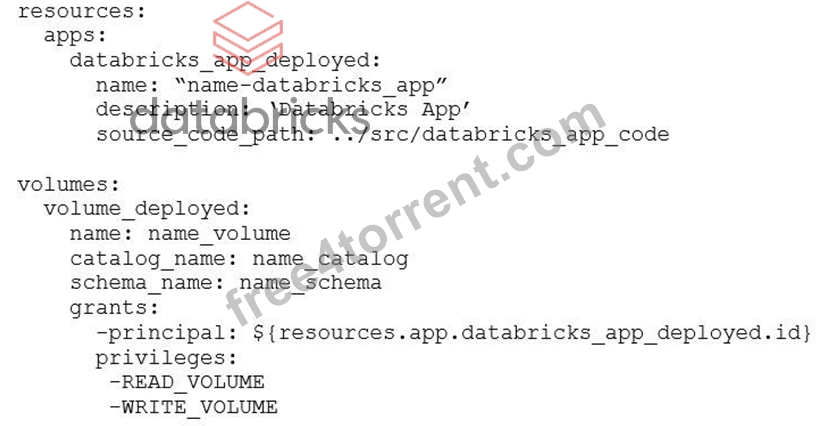
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: D
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 198
......
One of features of us is that we are pass guaranteed and money back guaranteed if you fail to pass the exam after buying Certified-Data-Engineer-Professional training materials of us. Or if you have other exam to attend, we can replace other 2 valid exam dumps to you, at the same time, you can get the update version for Certified-Data-Engineer-Professional Training Materials. Besides, we offer you free update for 365 days after purchasing, and the update version will be sent to your email address automatically. The Certified-Data-Engineer-Professional exam dumps include both the questions and answers, and it will help you to practice.
Certified-Data-Engineer-Professional Flexible Testing Engine: https://www.free4torrent.com/Certified-Data-Engineer-Professional-braindumps-torrent.html
- 2026 100% Free Certified-Data-Engineer-Professional –High-quality 100% Free Exam Preparation | Databricks Certified Data Engineer Professional Flexible Testing Engine 🌰 Download ( Certified-Data-Engineer-Professional ) for free by simply entering [ www.examcollectionpass.com ] website ⌨Demo Certified-Data-Engineer-Professional Test
- Test Certified-Data-Engineer-Professional Dumps Pdf 🎊 Reliable Certified-Data-Engineer-Professional Braindumps Sheet 🤣 Demo Certified-Data-Engineer-Professional Test 🔌 Simply search for ➠ Certified-Data-Engineer-Professional 🠰 for free download on ➤ www.pdfvce.com ⮘ 🐈Certified-Data-Engineer-Professional Valid Test Questions
- Certified-Data-Engineer-Professional Valid Test Questions 🌤 Certified-Data-Engineer-Professional Reliable Test Forum 🦥 Certified-Data-Engineer-Professional Valid Test Questions ❤ Go to website ▷ www.prepawayexam.com ◁ open and search for [ Certified-Data-Engineer-Professional ] to download for free 🐷Certified-Data-Engineer-Professional Reliable Test Objectives
- 100% Pass Quiz Databricks Marvelous Exam Certified-Data-Engineer-Professional Preparation 🧪 Simply search for [ Certified-Data-Engineer-Professional ] for free download on ⏩ www.pdfvce.com ⏪ 🍩Exam Certified-Data-Engineer-Professional Objectives
- Demo Certified-Data-Engineer-Professional Test 🏠 Valid Dumps Certified-Data-Engineer-Professional Sheet 💸 Certified-Data-Engineer-Professional Preparation Store 🐖 Easily obtain free download of ⇛ Certified-Data-Engineer-Professional ⇚ by searching on ➽ www.examcollectionpass.com 🢪 🏍Certified-Data-Engineer-Professional Valid Test Questions
- Accurate Certified-Data-Engineer-Professional Test 🥥 Test Certified-Data-Engineer-Professional Dumps Pdf 🛑 Demo Certified-Data-Engineer-Professional Test 🙆 Enter { www.pdfvce.com } and search for { Certified-Data-Engineer-Professional } to download for free 🦓Certified-Data-Engineer-Professional Real Dumps
- Real Certified-Data-Engineer-Professional Exam ⚔ Certified-Data-Engineer-Professional Preparation Store 📦 Certified-Data-Engineer-Professional Valid Test Questions 📔 Search for [ Certified-Data-Engineer-Professional ] and download it for free immediately on 【 www.prep4sures.top 】 🌖Certified-Data-Engineer-Professional Preparation Store
- 100% Pass Quiz Databricks Marvelous Exam Certified-Data-Engineer-Professional Preparation 🕧 Search on ⏩ www.pdfvce.com ⏪ for “ Certified-Data-Engineer-Professional ” to obtain exam materials for free download ⏩Reliable Certified-Data-Engineer-Professional Test Question
- Certified-Data-Engineer-Professional training exam pdf - Certified-Data-Engineer-Professional real valid dumps 🕘 Enter ➡ www.vce4dumps.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free ⛽Certified-Data-Engineer-Professional Valid Test Questions
- 2026 100% Free Certified-Data-Engineer-Professional –Latest 100% Free Exam Preparation | Databricks Certified Data Engineer Professional Flexible Testing Engine 🆑 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply entering ✔ www.pdfvce.com ️✔️ website ⚡Demo Certified-Data-Engineer-Professional Test
- Downloadable Certified-Data-Engineer-Professional PDF 🤮 Certified-Data-Engineer-Professional Valid Exam Topics 🤰 Reliable Certified-Data-Engineer-Professional Test Preparation 🍆 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering ➥ www.pdfdumps.com 🡄 website 〰Downloadable Certified-Data-Engineer-Professional PDF
- www.stes.tyc.edu.tw, users.playground.ru, scalar.usc.edu, me.muz.li, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes