2026 100% Free Certified-Data-Engineer-Professional–Updated 100% Free Pdf Braindumps | Certified-Data-Engineer-Professional Real Braindumps

2026 Latest Real4Prep Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1r8XE0GxAlCcPnPG8zCmENLTTXlm6TAoY
In order to reflect our sincerity on consumers and the trust of more consumers, we provide a 100% pass rate guarantee for all customers who have purchased Certified-Data-Engineer-Professional study quiz. If you fail to pass the exam after you purchased Certified-Data-Engineer-Professional preparation questions, you only need to provide your transcript to us, and then you can receive a full refund. Or we can free exchange two other exam materials for you if you have other exams to attend at the same time. So just buy our Certified-Data-Engineer-Professional Exam Questions!
| Section | Weight | Objectives |
|---|
| Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics
- Implement reliable streaming pipelines
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Security and Governance | ~10% | - Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
>> Pdf Certified-Data-Engineer-Professional Braindumps <<
Certified-Data-Engineer-Professional Real Braindumps & Latest Certified-Data-Engineer-Professional Demo
Real4Prep guarantees that if you use the product, you will pass the exam on your first try. Its primary goal is to save students time and money, not just conduct a business transaction. Candidates can take advantage of the free trials to evaluate the quality and standard of the Certified-Data-Engineer-Professional Dumps before making a purchase. With the right Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) study material and support team passing the examination at first attempt is an achievable goal.
Databricks Certified Data Engineer Professional Sample Questions (Q188-Q193):
NEW QUESTION # 188
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
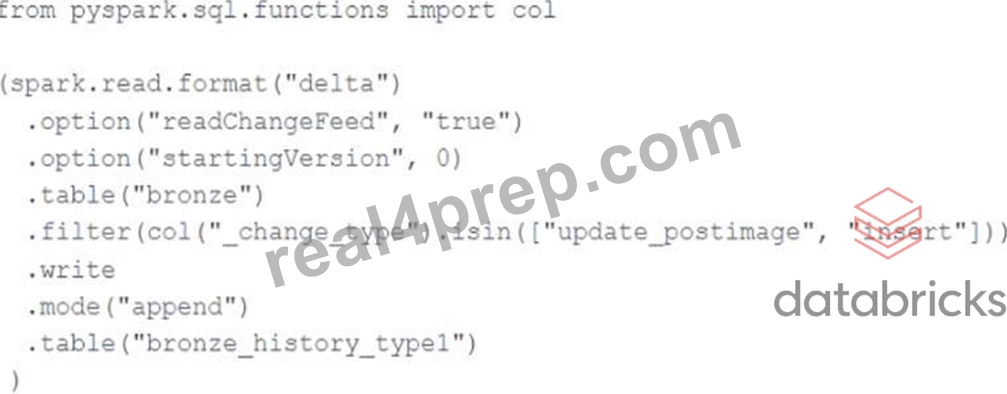
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- B. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
- C. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
Answer: B
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 189
Which statement characterizes the general programming model used by Spark Structured Streaming?
- A. Structured Streaming is implemented as a messaging bus and is derived from Apache Kafka.
- B. Structured Streaming uses specialized hardware and I/O streams to achieve sub-second latency for data transfer.
- C. Structured Streaming models new data arriving in a data stream as new rows appended to an unbounded table.
- D. Structured Streaming relies on a distributed network of nodes that hold incremental state values for cached stages.
- E. Structured Streaming leverages the parallel processing of GPUs to achieve highly parallel data throughput.
Answer: C
Explanation:
The key idea in Structured Streaming is to treat a live data stream as a table that is being continuously appended. This leads to a new stream processing model that is very similar to a batch processing model. You will express your streaming computation as standard batch-like query as on a static table, and Spark runs it as an incremental query on the unbounded input table. Let's understand this model in more detail.
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html
NEW QUESTION # 190
A nightly batch job is configured to ingest all data files from a cloud object storage container where records are stored in a nested directory structure YYYY/MM/DD. The data for each date represents all records that were processed by the source system on that date, noting that some records may be delayed as they await moderator approval. Each entry represents a user review of a product and has the following schema:
user_id STRING, review_id BIGINT, product_id BIGINT, review_timestamp TIMESTAMP, review_text STRING The ingestion job is configured to append all data for the previous date to a target table reviews_raw with an identical schema to the source system. The next step in the pipeline is a batch write to propagate all new records inserted into reviews_raw to a table where data is fully deduplicated, validated, and enriched.
Which solution minimizes the compute costs to propagate this batch of data?
- A. Reprocess all records in reviews_raw and overwrite the next table in the pipeline.
- B. Use Delta Lake version history to get the difference between the latest version of reviews_raw and one version prior, then write these records to the next table.
- C. Configure a Structured Streaming read against the reviews_raw table using the trigger once execution mode to process new records as a batch job.
- D. Filter all records in the reviews_raw table based on the review_timestamp; batch append those records produced in the last 48 hours.
- E. Perform a batch read on the reviews_raw table and perform an insert-only merge using the natural composite key user_id, review_id, product_id, review_timestamp.
Answer: C
Explanation:
https://www.databricks.com/blog/2017/05/22/running-streaming-jobs-day-10x-cost-savings.html
NEW QUESTION # 191
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
- A. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to compute the daily aggregated distance and fuel efficiency per truck_id reporting. Create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
- B. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to incrementally compute the latest location, speed, and fuel_level per truck_id for real-time monitoring. Create a materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
- C. Define a materialized view to ingest and store the raw telemetry data, and create a streaming table to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting. - D. Define a streaming table to ingest and store the raw telemetry data, and create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
Answer: B
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 192
A Data Engineer is building a fraud detection pipeline that calls out to Open AI, via a Python library, and needs to include an access token when using the API. Which Databricks CLI command should the Data Engineer use to create the secret?
- A. databricks secrets put-secret KEY SCOPE; dbutils.secrets.get (KEY, SCOPE)
- B. databricks tokens put-token KEY SCOPE; dbutils.secrets.get (KEY, SCOPE)
- C. databricks secrets put-secret SCOPE KEY; dbutils.secrets.get (SCOPE, KEY)
- D. databricks tokens put-token SCOPE KEY; dbutils.tokens.get (SCOPE, KEY)
Answer: C
Explanation:
The Databricks CLI command databricks secrets put-secret <scope> <key> is used to securely store sensitive values such as API access tokens in a secret scope. The secret can then be retrieved at runtime using dbutils.secrets.get(scope, key), ensuring credentials are not hard- coded and remain protected.
NEW QUESTION # 193
......
Due to its unique features, it is ideal for the majority of the students. It provides them complete assistance for understanding of the syllabus. It contains the comprehensive Certified-Data-Engineer-Professional exam questions that are not difficult to understand. By using these aids you will be able to modify your skills to the required limits. Your Certified-Data-Engineer-Professional Certification success is just a step away and is secured with 100% money back guarantee.
Certified-Data-Engineer-Professional Real Braindumps: https://www.real4prep.com/Certified-Data-Engineer-Professional-exam.html
- Certified-Data-Engineer-Professional Practice Test Online 🦕 New Certified-Data-Engineer-Professional Exam Preparation 🙈 Certified-Data-Engineer-Professional Cost Effective Dumps 👉 ➥ www.examcollectionpass.com 🡄 is best website to obtain ➠ Certified-Data-Engineer-Professional 🠰 for free download 🍌Frenquent Certified-Data-Engineer-Professional Update
- Certified-Data-Engineer-Professional Tests Dumps, Certified-Data-Engineer-Professional Test Exam, Certified-Data-Engineer-Professional Valid Dumps 🐘 Go to website ▛ www.pdfvce.com ▟ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free 🔡Reliable Certified-Data-Engineer-Professional Exam Review
- Certified-Data-Engineer-Professional Tests Dumps, Certified-Data-Engineer-Professional Test Exam, Certified-Data-Engineer-Professional Valid Dumps 🌭 ✔ www.prep4away.com ️✔️ is best website to obtain 《 Certified-Data-Engineer-Professional 》 for free download 🧍New Certified-Data-Engineer-Professional Braindumps Files
- Certified-Data-Engineer-Professional Tests Dumps, Certified-Data-Engineer-Professional Test Exam, Certified-Data-Engineer-Professional Valid Dumps 🧖 Open ▷ www.pdfvce.com ◁ enter ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download 🦆Certified-Data-Engineer-Professional Unlimited Exam Practice
- New Certified-Data-Engineer-Professional Test Tutorial 🏉 New Certified-Data-Engineer-Professional Exam Preparation 💰 Reliable Certified-Data-Engineer-Professional Exam Review 🔷 Copy URL ▷ www.easy4engine.com ◁ open and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free 🧣High Certified-Data-Engineer-Professional Passing Score
- Desktop and Web-Based Practice Exams to Evaluate Certified-Data-Engineer-Professional Exam Preparation 🌵 Open website ➡ www.pdfvce.com ️⬅️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download 🧞Certified-Data-Engineer-Professional Valid Test Tips
- Certified-Data-Engineer-Professional Real Exam - Certified-Data-Engineer-Professional Torrent Vce - Certified-Data-Engineer-Professional Valid Questions 🌃 The page for free download of ⏩ Certified-Data-Engineer-Professional ⏪ on ▛ www.verifieddumps.com ▟ will open immediately ❎Frenquent Certified-Data-Engineer-Professional Update
- Certified-Data-Engineer-Professional Pass-Sure materials - Certified-Data-Engineer-Professional Quiz Torrent - Certified-Data-Engineer-Professional Passing Rate 🕠 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on ⇛ www.pdfvce.com ⇚ 🔫Exam Certified-Data-Engineer-Professional Learning
- Efficient Pdf Certified-Data-Engineer-Professional Braindumps to Obtain Databricks Certification 🏟 Enter ➽ www.troytecdumps.com 🢪 and search for ( Certified-Data-Engineer-Professional ) to download for free 🕠Certified-Data-Engineer-Professional Test Duration
- Reliable Certified-Data-Engineer-Professional Test Notes 🏀 Reliable Certified-Data-Engineer-Professional Test Labs 🧦 New Certified-Data-Engineer-Professional Braindumps Files 🎑 Search for 「 Certified-Data-Engineer-Professional 」 on ➽ www.pdfvce.com 🢪 immediately to obtain a free download 🍟High Certified-Data-Engineer-Professional Passing Score
- Desktop and Web-Based Practice Exams to Evaluate Certified-Data-Engineer-Professional Exam Preparation 🌇 Open ➠ www.easy4engine.com 🠰 enter ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download 🥀Certified-Data-Engineer-Professional Cost Effective Dumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that Real4Prep Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1r8XE0GxAlCcPnPG8zCmENLTTXlm6TAoY