Our NCP-BC-7.5 exam materials are compiled by experts and approved by the professionals who are experienced. They are revised and updated according to the pass exam papers and the popular trend in the industry. The language of our NCP-BC-7.5 exam torrent is simple to be understood and our NCP-BC-7.5 test questions are suitable for any learners. Only 20-30 hours are needed for you to learn and prepare our NCP-BC-7.5 Test Questions for the exam and you will save your time and energy. No matter you are the students or the in-service staff you are busy in your school learning, your jobs or other important things and can't spare much time to learn.
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Protection Domains - Replication Types (Sync/Async) - Nutanix Leap Overview |
| Topic 2: Recovery Operations | - Recovery Plans and Orchestration - Test Recovery Workflows - Failover and Failback Procedures |
| Topic 3: Prism Central Management | - Cluster and Site Management - DR Monitoring and Operations |
| Topic 4: Data Protection and Backup Integration | - Backup Solutions Integration - Snapshot Management |
| Topic 5: Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
We will provide you with three different versions of our NCP-BC-7.5 exam questions on our test platform. You have the opportunity to download the three different versions from our test platform. The three different versions of our NCP-BC-7.5 test torrent include the PDF version, the software version and the online version. The three different versions will offer you same questions and answers, but they have different functions. According to your needs, you can choose any one version of our NCP-BC-7.5 Guide Torrent. For example, if you need to use our products in an offline state, you can choose the online version; if you want to try to simulate the real examination, you can choose the software. In a word, the three different versions of our NCP-BC-7.5 test torrent.
NEW QUESTION # 68
An administrator is tasked with ensuring the VMs do not experience downtime during an upcoming network maintenance on the primary cluster. The VMs are protected by a Protection Policy and are configured under a Recovery Plan. What failover mechanism should the administrator use to ensure the VMs are available on the target cluster before the maintenance window?
Answer: D
Explanation:
In a Business Continuity strategy, " downtime " can be categorized as either unexpected (disaster) or controlled (maintenance). When an administrator knows that a disruption is coming, such as scheduled network maintenance on a primary cluster, they should utilize the " Planned Failover " mechanism within the Nutanix Recovery Plan.
A Planned Failover is a graceful, orchestrated migration. It first shuts down the virtual machines at the primary site to ensure all data is flushed and no new writes occur. It then performs a final synchronization to the recovery site to ensure zero data loss (Zero RPO), and finally powers the VMs on at the destination site according to the plan ' s sequence. This differs significantly from an " Unplanned Failover " (Option A), which assumes the primary site is already offline and may result in minor data loss depending on the last successful replication. A " Test Failover " (Option D) merely validates the process in an isolated environment and does not move the actual production workload. By executing a Planned Failover before the maintenance begins, the administrator ensures that the services are safely running on the target cluster, maintaining application availability and meeting the objective of zero downtime during the maintenance window.
NEW QUESTION # 69
An administrator has recently completed the initial configuration of Nutanix Disaster Recovery for a production environment. Protection Policies and Recovery Plans have been configured and validated by the senior infrastructure team.
The administrator has confirmed that the expected categories are correctly associated with both the Protection Policies and Recovery Plans. During a scheduled test failover, the administrator notices that several VMs are missing from the recovery.
The administrator reviews the environment and notes the following:
* The Protection Summary tab does not show any warnings or errors
* No replication tasks are currently ongoing
* The missing VMs were all deployed within the last two weeks as part of a new application rollout
* The missing VMs are running on the same cluster as other VMs that recovered successfully during the test failover
* The application team followed the standard VM deployment checklist but did not coordinate with the infrastructure team during provisioning Given this information, what is the most likely cause of the missing VMs?
Answer: D
Explanation:
Modern Nutanix Disaster Recovery (Leap) relies on " Categories " to automate the inclusion of virtual machines into Protection Policies and Recovery Plans. When a Protection Policy is created, it is typically applied to a category (e.g., AppType:SQL) rather than individual VM names.
In this scenario, the newly deployed VMs were missed during a test failover despite other VMs on the same cluster recovering successfully. The most likely root cause is that the application team, working independently, failed to assign the required categories to the new VMs during the provisioning process.
Because the VMs lacked the correct category tags, the Nutanix Protection Policy did not " see " them, and consequently, no recovery points were ever created for them. This is a common operational failure in environments where " infrastructure as code " or strict provisioning standards are not enforced. Recovery Plans (Option A) do not need manual re-synchronization for new VMs if the categories are correctly mapped.
While an initial sync is required (Option D), it would typically show a task or progress rather than just leaving the VMs " missing " from the entire protection summary. Therefore, verifying category assignment is the primary troubleshooting step.
NEW QUESTION # 70
In the case of a protection domain containing more than 500 VMs, what is the first step an engineer must take before migrating to Prism Central-based protection policies while ensuring all VMs remain protected?
Answer: B
Explanation:
Migrating from legacy Protection Domains to modern Prism Central Protection Policies is a recommended practice for scaling DR management. However, large environments must account for architectural limits during this transition. A Nutanix cluster has specific maximum thresholds for the number of entities (VMs) that can be contained within a single Protection Domain, and similar limits exist for the initial " handoff " to Prism Central.
If a single legacy Protection Domain contains more than 500 VMs, attempting to migrate it as a single unit can lead to timeouts, metadata synchronization failures, and potential gaps in protection. To ensure that all VMs remain consistently protected during the migration, the first step is to " split " the existing large Protection Domain into multiple smaller, more manageable ones. For example, an administrator might split a
600-VM domain into three 200-VM domains. This reduction in " entity density " allows the Nutanix Cerebro and Prism Central services to process the migration tasks more efficiently without hitting resource contention or task timeout limits. Once the VMs are organized into these smaller groups, they can be systematically unlinked from the legacy domains and added to the new PC-based Protection Policies. This phased and controlled approach minimizes risk and ensures that a valid recovery point always exists for every VM throughout the entire migration lifecycle.
NEW QUESTION # 71
Exhibit: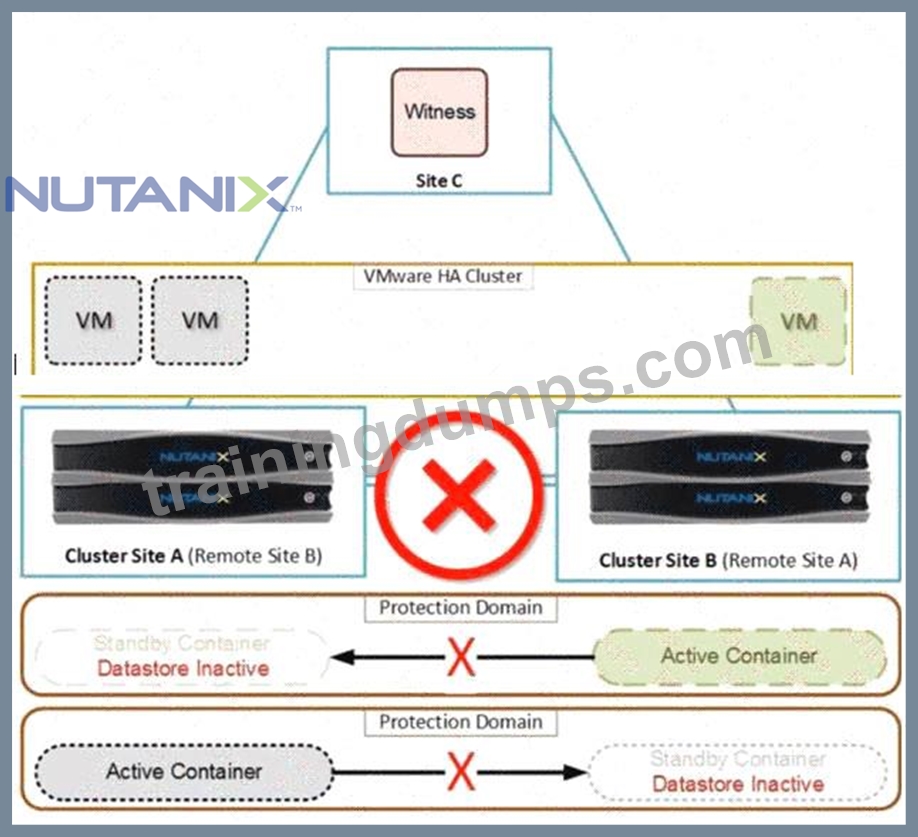
An administrator wants to protect the snapshots created on the cluster. Only authorized users should be allowed to modify or delete the snapshots on the cluster. How can the administrator harden the security of the snapshots?
Answer: D
Explanation:
Security hardening for BCDR is focused on protecting the integrity of recovery points against accidental deletion, administrative errors, or malicious intent such as ransomware. While infrastructure-level hardening like SSH keys (Option C) or host-level security (Option A) is important, they do not prevent a user with valid administrative credentials in Prism from deleting a snapshot. To address the specific requirement of ensuring only " authorized " and verified actions can modify or delete snapshots, the administrator should implement an " Approval Policy " .
An Approval Policy introduces a " four-eyes " principle for critical management tasks. When this policy is active, any attempt to delete or modify a recovery point does not execute immediately. Instead, it triggers a request in the Prism Central " Task " console and enters a " Pending Approval " state. A separate authorized user-an " Approver " -must then review the request and explicitly grant permission before the deletion can occur. This creates a vital procedural safeguard, ensuring that no single individual has the unilateral power to destroy the organization ' s backup data. By configuring this policy, the administrator hardens the DR environment against both internal threats and external actors who might gain access to a single set of admin credentials, providing a robust layer of defense for critical data assets.
NEW QUESTION # 72
Which two VM disk types does Self-Service restore support? (Choose two.)
Answer: A,B
Explanation:
Self-Service Restore (SSR) relies on the Nutanix Guest Tools (NGT) agent to mount a historical snapshot disk to the guest OS via the hypervisor ' s virtual controller. For this to work seamlessly, the guest OS and the NGT agent must support the virtual bus types used by the virtual machine.
Nutanix SSR natively supports the two most common virtual disk controller types: SCSI (VirtIO) and IDE.
These are the standard formats for most virtual disks in Nutanix AHV and ESXi environments. When a user requests a file-level restore, the system takes the vDisk from the recovery point and attaches it as a new SCSI or IDE device to the running VM, which the guest OS then scans and mounts. Conversely, specialized storage entities like Volume Groups (VGs) (Option D) and certain high-performance direct-attached PCI-based storage (Option C) are not supported by the standard SSR workflow. Volume Groups, which are often used for shared storage between VMs (like SQL Clusters), require a different recovery method because they are not part of the standard VM-centric snapshot metadata that the SSR agent can browse. Therefore, SSR is primarily designed for the standard virtual disks that form the OS and application drives of typical virtualized workloads.
NEW QUESTION # 73
......
Our company is a professional certification exam materials provider, we have occupied in this field for more than ten years, and therefore we have rich experience. NCP-BC-7.5 exam braindumps are high quality, because we have a professional team to collect the first-hand information for the exam, we can ensure that you can get the latest information for the exam. In addition, our company is strict with the quality and answers for NCP-BC-7.5 Exam Materials, and therefore you can use them at ease. Our NCP-BC-7.5 exam braindumps are known as instant access to download, you can obtain the downloading link and password within ten minutes.
NCP-BC-7.5 Exam Collection Pdf: https://www.trainingdumps.com/NCP-BC-7.5_exam-valid-dumps.html