DP-800試験に合格して認定を取得すると、対処方法がわからない多くのハンディキャップが発生する可能性があるため、DP-800試験に合格して受験することは難しいと思われるかもしれません。認証。これらの問題を解決し、試験に簡単に合格できるようにするため、このようなDP-800試験急流を遵守しました。 DP-800試験問題集を購入した後悔がないことをお約束します。 DP-800試験問題の合格率は99%〜100%であり、必ず合格します。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Exam Format: | Multiple choice, Case studies |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Available Languages: | English |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
今後のDP-800学習教材について心配がある場合は、学習教材が問題の解決に役立ちます。弊社のDP-800学習教材の高品質をお約束するために、当社には優れた技術スタッフがおり、販売後の完璧なサービスシステムがあります。さらに重要なことは、当社のDP-800ガイド質問と完璧なアフターサービスが、地元および海外のお客様に認められていることです。模擬試験に合格する場合は、学習エンジンが必須の選択肢になると考えています。過去数年間、DP-800ガイドの質問を購入する人が増えています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 64
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.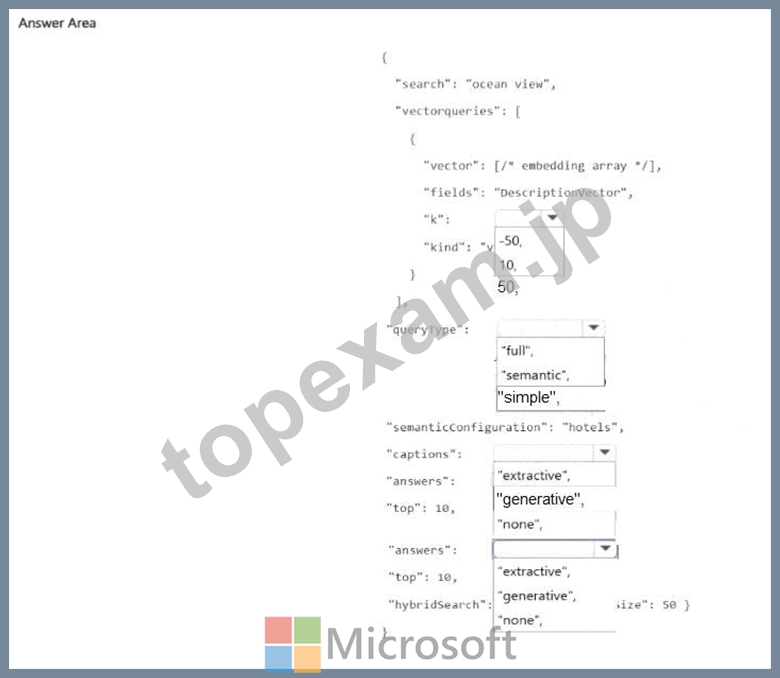
正解:
解説: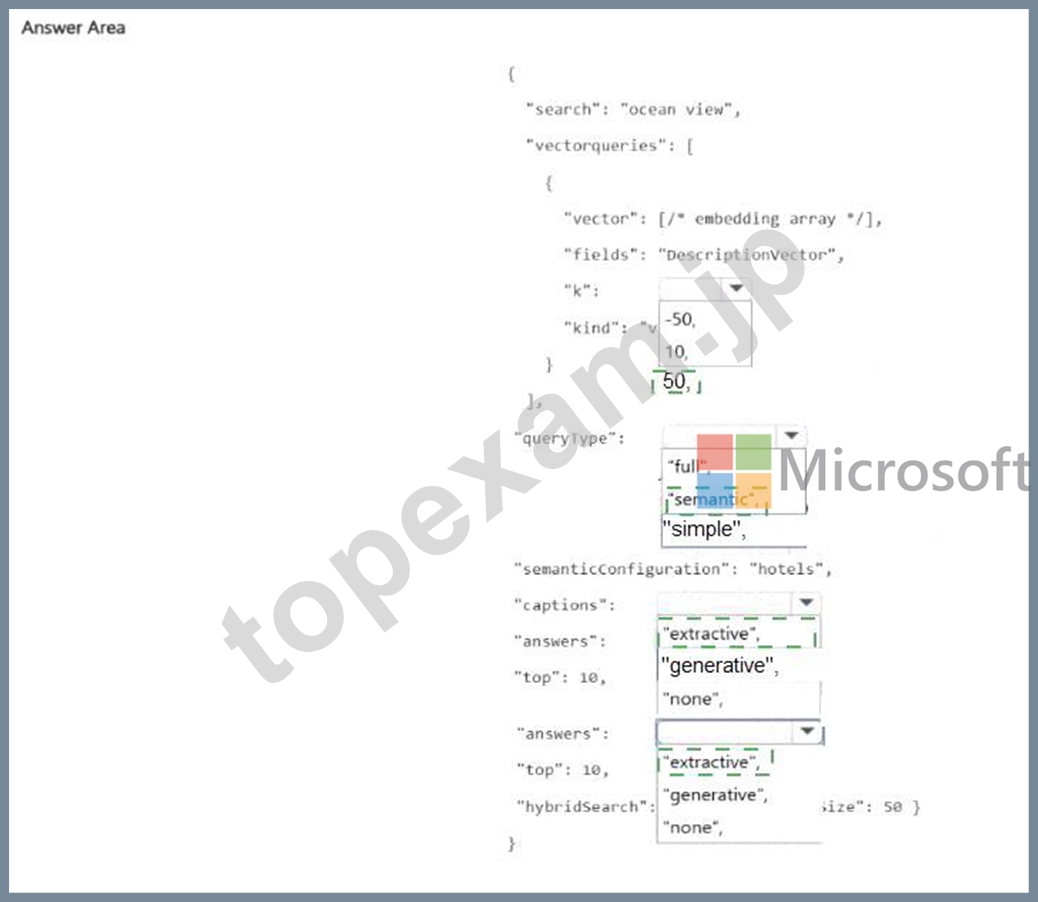
Explanation: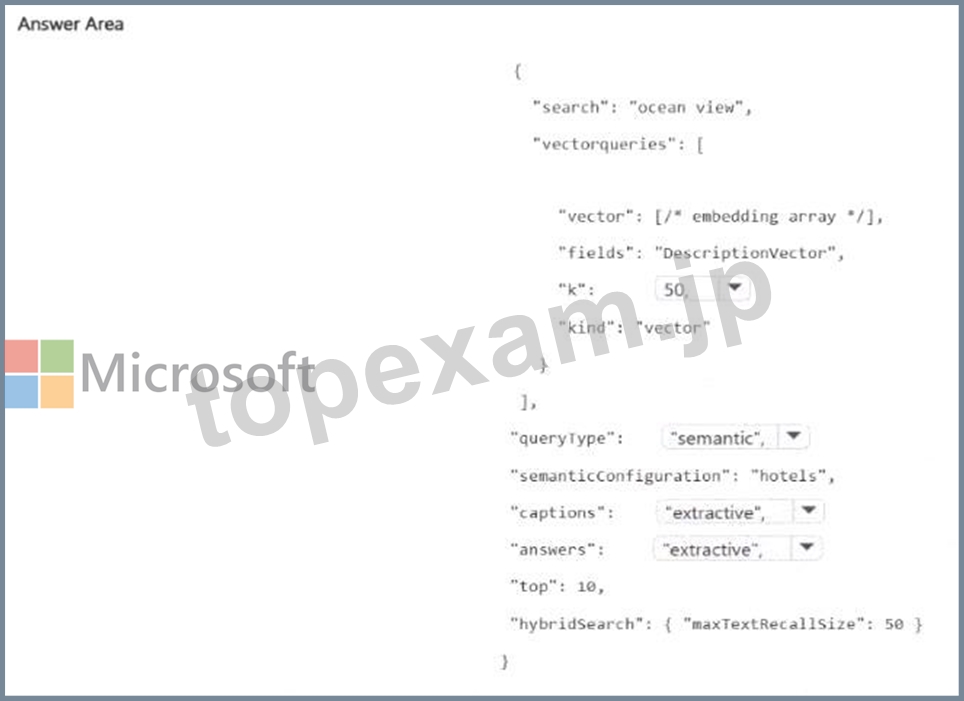
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
質問 # 65
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.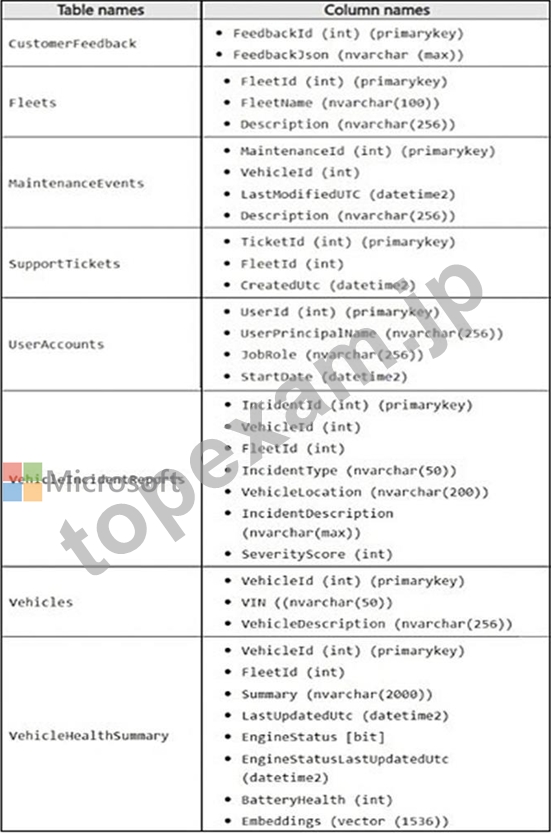
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.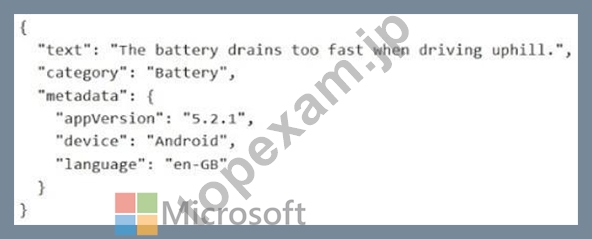
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.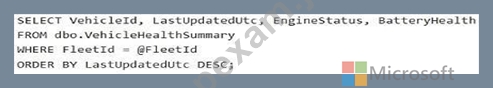
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
正解:C
解説:
Scenario: VehicleIncidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
The column you should use to generate embeddings is IncidentDescription.
Why this is the correct choice:
Semantic Meaning: Embeddings are designed to capture the semantic meaning of rich, unstructured text. The IncidentDescription column likely contains the detailed natural language notes about weather, traffic, and location that the analysts are struggling to search effectively using standard methods.
Vector Search: By converting the text in IncidentDescription into mathematical vectors (embeddings), you can perform a semantic vector search. This allows the database to find
"similar" incidents based on the context of the description rather than just matching exact keywords or categories.
Incorrect:
[Not A]
VehicleLocation: Typically contains specific coordinates or addresses which are better handled by spatial data types or exact matching.
[Not C]
IncidentType: Is likely a categorical label (e.g., "Fender Bender", "Multi-car pileup") and too simple for meaningful embedding generation.
[Not D]
SeverityScore: Is a numeric value that represents a magnitude, not a semantic concept.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/spatial-geography/spatial-types-geography
質問 # 66
Drag and Drop Question
You have an Azure SQL database named sqldb-ai-prod that stores customer support tickets for a multitenant software as a service (SaaS) application. sqldb-ai-prod contains a table named Tickets. Tickets contains columns named TenantId, TicketId, CustomerEmail, CustomerPhone, and Notes.
You plan to harden data access, since a new support team will use ad hoc reporting tools that connect directly to sqldb-ai-prod.
You need to configure security to meet the following requirements:
- Support agents must see only the rows of their own TenantId column.
- Support agents must see only the domain name portion of the
CustomerEmail column.
What should you do for each requirement? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.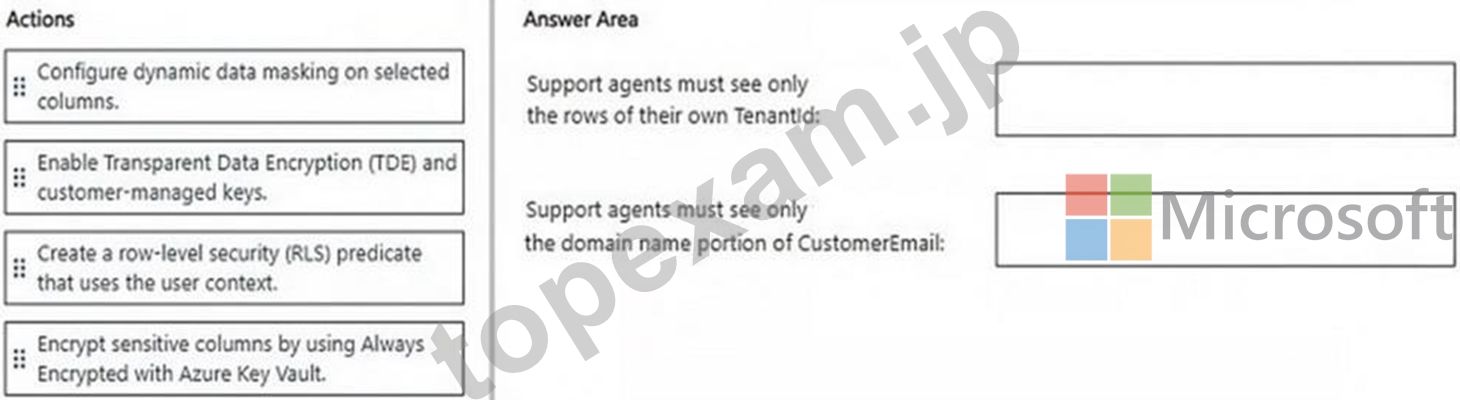
正解:
解説: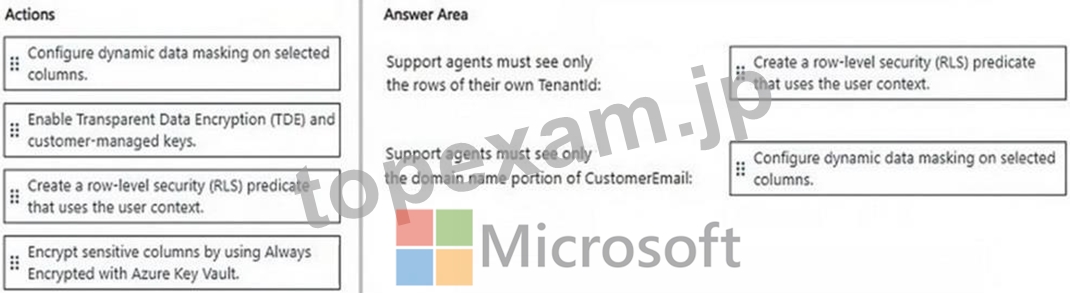
質問 # 67
You have an Azure SQL database that contains a table named dbo.Products. dbo.Products contains three columns named Embedding, Category, and Price. The Embedding column is defined as VECTOR(1536).
You use AI_GENERATE_EMBEDDINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3- small. Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
正解:C
解説:
To ensure your applications can transition models without runtime errors while using VECTOR_SEARCH, you must first define a Vector Index that explicitly identifies the dimensions and distance metric.
Since you are moving from text-embedding-ada-002 to text-embedding-3-small, both models default to 1536 dimensions, which matches your existing column definition. To create the index as the first step, use the following SQL:
CREATE VECTOR INDEX idx_embedding ON YourTableName (Embedding)
WITH ( DISTANCE_METRIC = 'COSINE' );
Use code with caution.
Why this works:
Schema Consistency: Because both models use 1536 dimensions, you don't need to alter the VECTOR(1536) column type immediately.
Search Stability: Creating the index allows the engine to optimize the VECTOR_SEARCH function. As long as the incoming query vector (generated by the app) matches the dimensions of the stored vectors, the search will execute without a runtime dimension mismatch error.
Reference:
https://docs.couchbase.com/cloud/n1ql/n1ql-language-reference/vectorfun.html
質問 # 68
You have a Microsoft SQL Server 2025 instance that has a managed identity enabled.
You have a database that contains a table named dbo.ManualChunks. dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpoint for chat completions. The solution must provide the highest level of security.
You write the following Transact-SG1 code.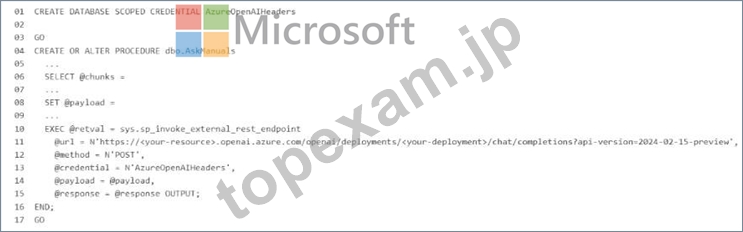
What should you insert at line 02?
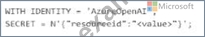
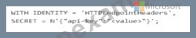
正解:B
解説:
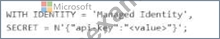
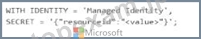
The correct answer is Option B because the requirement is to call an Azure OpenAI REST endpoint from SQL Server 2025 while providing the highest level of security , and the instance already has a managed identity enabled . For Microsoft's SQL AI features, the preferred secure pattern is to use a database scoped credential with IDENTITY = ' Managed Identity ' instead of storing an API key. Microsoft documents that SQL Server 2025 supports managed identity for external AI endpoints, and for Azure OpenAI the credential secret uses the Cognitive Services resource identifier: { " resourceid " : " https://cognitiveservices.azure.
com " } .
So line 02 should be:
WITH IDENTITY = ' Managed Identity ' ,
SECRET = ' { " resourceid " : " https://cognitiveservices.azure.com " } ' ; Why the other options are incorrect:
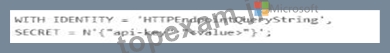
* A and D use HTTP header or query-string credentials with an API key , which is less secure than managed identity because a secret key must be stored and rotated manually. Microsoft recommends managed identity where supported to avoid embedded secrets.
* C mixes Managed Identity with an api-key secret, which is not the correct pattern for Azure OpenAI managed-identity authentication.
* E uses an invalid identity value for this scenario. The accepted credential identities for external REST endpoint calls include HTTPEndpointHeaders , HTTPEndpointQueryString , Managed Identity , and Shared Access Signature .
Because the endpoint is Azure OpenAI and the question explicitly asks for the highest security , managed identity with the Cognitive Services resource ID is the Microsoft-aligned answer.
質問 # 69
......
DP-800参考資料: https://www.topexam.jp/DP-800_shiken.html