我們提供最有效的Databricks-Certified-Data-Engineer-Professional資訊,保證妳100%通過考試

順便提一下,可以從雲存儲中下載Testpdf Databricks-Certified-Data-Engineer-Professional考試題庫的完整版:https://drive.google.com/open?id=11xbKYKfOmn5O-t4cK5iNpmvHDU2vROcj
Databricks Databricks-Certified-Data-Engineer-Professional認證考試是目前IT人士報名參加的考試中很受歡迎的一個認證考試。通過了Databricks Databricks-Certified-Data-Engineer-Professional認證考試不僅能使你工作和生活帶來提升,而且還能鞏固你在IT 領域的地位。但是事實情況是它通過率確很低。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions
- Ensure data privacy and compliance
- Secure data at rest and in transit
|
| Topic 2: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Use Auto Loader and structured streaming
- Ingest data from diverse sources
|
| Topic 3: Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Topic 4: Data Governance | 7% | - Use Unity Catalog for governance
- Enforce data policies and standards
- Manage data assets and metadata
|
| Topic 5: Data Sharing and Federation | 5% | - Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
- Manage cross-platform data access
|
| Topic 6: Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
- Implement CI/CD and DevOps practices
|
| Topic 7: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Enforce data quality standards
- Apply data cleansing and validation rules
|
| Topic 8: Data Modelling | 6% | - Implement dimensional and relational models
- Design Medallion Architecture
- Optimize table design and partitioning
|
| Topic 9: Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Topic 10: Monitoring and Alerting | 10% | - Track data lineage and metrics
- Monitor pipeline performance and health
- Set up alerts and notifications
|
>> Databricks-Certified-Data-Engineer-Professional資訊 <<
Databricks Databricks-Certified-Data-Engineer-Professional證照考試 & Databricks-Certified-Data-Engineer-Professional考題套裝
為了通過Databricks Databricks-Certified-Data-Engineer-Professional 認證考試,請選擇我們的Testpdf來取得好的成績。你不會後悔這樣做的,花很少的錢取得如此大的成果這是值得的。我們的Testpdf不僅能給你一個好的考試準備,讓你順利通過Databricks Databricks-Certified-Data-Engineer-Professional 認證考試,而且還會為你提供免費的一年更新服務。
最新的 Databricks Certification Databricks-Certified-Data-Engineer-Professional 免費考試真題 (Q231-Q236):
問題 #231
The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Which statement describes what the number alongside this field represents?
- A. The total number of jobs that have been run in the workspace.
- B. The number of times the job definition has been run in the workspace.
- C. The job_id is returned in this field.
- D. The globally unique ID of the newly triggered run.
- E. The job_id and number of times the job has been are concatenated and returned.
答案:D
解題說明:
When triggering a job run using the Databricks CLI, the run_id field in the response represents a globally unique identifier for that particular run of the job. This run_id is distinct from the job_id.
While the job_id identifies the job definition and is constant across all runs of that job, the run_id is unique to each execution and is used to track and query the status of that specific job run within the Databricks environment. This distinction allows users to manage and reference individual executions of a job directly.
問題 #232
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM 160 total cores and only one Executor per VM.
Given an extremely long-running job for which completion must be guaranteed, which cluster configuration will be able to guarantee completion of the job in light of one or more VM failures?
- A. - Total VMs: 8
- 50 GB per Executor
- 20 Cores / Executor - B. - Total VMs: 1
- 400 GB per Executor
- 160 Cores/Executor - C. - Total VMs: 16
- 25 GB per Executor
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- 10 Cores / Executor - D. - Total VMs: 4
- 100 GB per Executor
- 40 Cores / Executor - E. - Total VMs: 2
- 200 GB per Executor
- 80 Cores / Executor
答案:C
解題說明:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
問題 #233
Review the following error traceback:
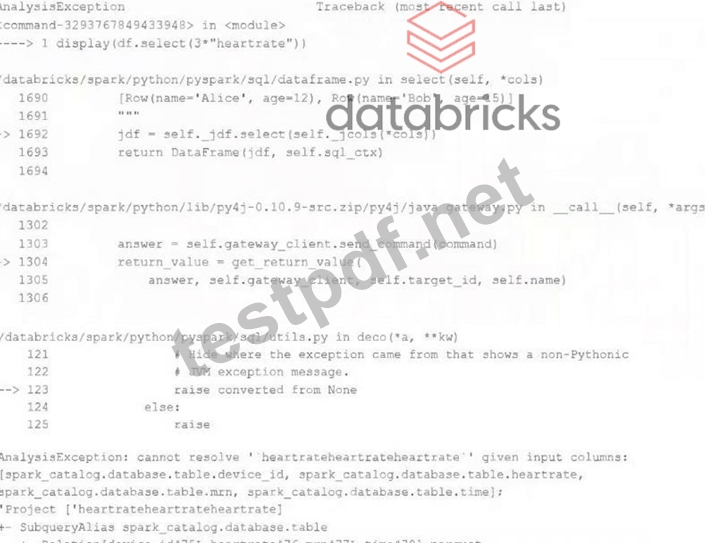
Which statement describes the error being raised?
- A. The code executed was PvSoark but was executed in a Scala notebook.
- B. There is no column in the table named heartrateheartrateheartrate
- C. There is a type error because a DataFrame object cannot be multiplied.
- D. There is a type error because a column object cannot be multiplied.
- E. There is a syntax error because the heartrate column is not correctly identified as a column.
答案:B
解題說明:
https://sparkbyexamples.com/spark/spark-cannot-resolve-given-input-columns/
問題 #234
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
- B. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- C. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- D. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
答案:C
解題說明:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
問題 #235
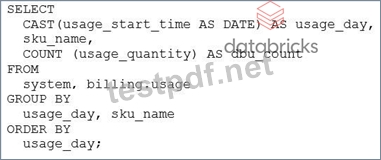
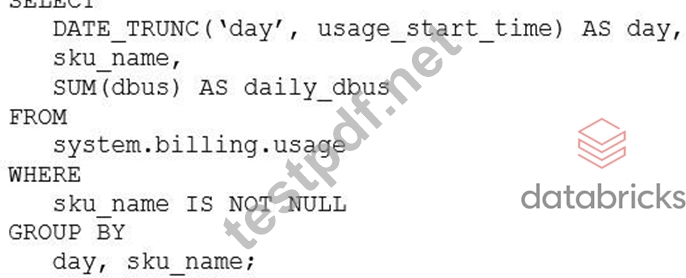
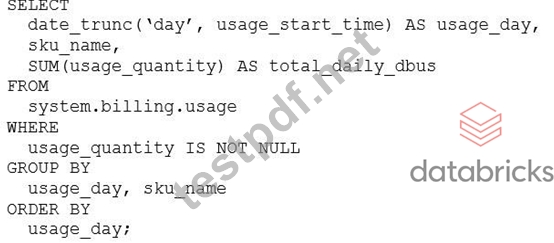
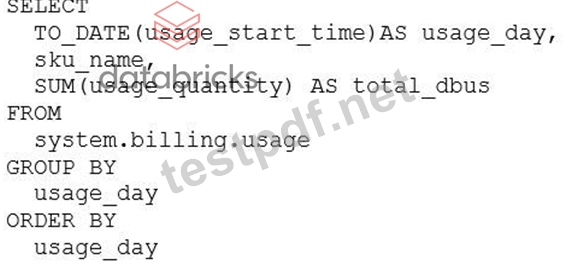
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
答案:C
解題說明:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
問題 #236
......
選擇參加Databricks Databricks-Certified-Data-Engineer-Professional 認證考試是一個明智的選擇,因為有了Databricks Databricks-Certified-Data-Engineer-Professional認證證書後,你的工資和職位都會有所提升,生活水準就會相應的提供。但是通過Databricks Databricks-Certified-Data-Engineer-Professional 認證考試不是很容易的,需要花很多時間和精力掌握好相關專業知識。Testpdf是一個制訂Databricks Databricks-Certified-Data-Engineer-Professional 認證考試培訓方案的專業IT培訓網站。你可以先在我們的網站上免費下載部分部分關於Databricks Databricks-Certified-Data-Engineer-Professional 認證考試的練習題和答案作為免費嘗試,以便你可以檢驗我們的可靠性。一般,試用Testpdf的產品後,你會對我們的產品很有信心的。
Databricks-Certified-Data-Engineer-Professional證照考試: https://www.testpdf.net/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional考題寶典 😘 Databricks-Certified-Data-Engineer-Professional PDF 🥶 Databricks-Certified-Data-Engineer-Professional認證題庫 🕎 在⏩ www.pdfexamdumps.com ⏪網站上查找「 Databricks-Certified-Data-Engineer-Professional 」的最新題庫Databricks-Certified-Data-Engineer-Professional考題寶典
- Databricks-Certified-Data-Engineer-Professional測試題庫 🏺 Databricks-Certified-Data-Engineer-Professional最新考證 🅱 Databricks-Certified-Data-Engineer-Professional題庫更新 🎅 [ www.newdumpspdf.com ]上搜索▛ Databricks-Certified-Data-Engineer-Professional ▟輕鬆獲取免費下載Databricks-Certified-Data-Engineer-Professional題庫更新
- Databricks-Certified-Data-Engineer-Professional考試證照 🔮 Databricks-Certified-Data-Engineer-Professional認證題庫 💅 Databricks-Certified-Data-Engineer-Professional考題寶典 🏋 ➠ www.vcesoft.com 🠰上搜索➠ Databricks-Certified-Data-Engineer-Professional 🠰輕鬆獲取免費下載Databricks-Certified-Data-Engineer-Professional考題寶典
- Databricks-Certified-Data-Engineer-Professional PDF ⭕ Databricks-Certified-Data-Engineer-Professional最新考證 🐵 免費下載Databricks-Certified-Data-Engineer-Professional考題 🕕 ( www.newdumpspdf.com )上的( Databricks-Certified-Data-Engineer-Professional )免費下載只需搜尋Databricks-Certified-Data-Engineer-Professional題庫資料
- Databricks-Certified-Data-Engineer-Professional最新考證 🦋 免費下載Databricks-Certified-Data-Engineer-Professional考題 ↩ 最新Databricks-Certified-Data-Engineer-Professional考證 🖕 ➥ www.kaoguti.com 🡄提供免費( Databricks-Certified-Data-Engineer-Professional )問題收集Databricks-Certified-Data-Engineer-Professional考試心得
- Databricks-Certified-Data-Engineer-Professional软件版 🔀 Databricks-Certified-Data-Engineer-Professional最新題庫資源 🏀 最新Databricks-Certified-Data-Engineer-Professional題庫 🚨 打開▛ www.newdumpspdf.com ▟搜尋{ Databricks-Certified-Data-Engineer-Professional }以免費下載考試資料最新Databricks-Certified-Data-Engineer-Professional題庫
- Databricks-Certified-Data-Engineer-Professional PDF 🌌 Databricks-Certified-Data-Engineer-Professional软件版 🗻 Databricks-Certified-Data-Engineer-Professional考試證照 🚕 在➤ www.pdfexamdumps.com ⮘搜索最新的《 Databricks-Certified-Data-Engineer-Professional 》題庫Databricks-Certified-Data-Engineer-Professional證照信息
- Databricks-Certified-Data-Engineer-Professional證照信息 🍞 Databricks-Certified-Data-Engineer-Professional考試心得 🚪 Databricks-Certified-Data-Engineer-Professional考題寶典 👬 在《 www.newdumpspdf.com 》網站下載免費▶ Databricks-Certified-Data-Engineer-Professional ◀題庫收集Databricks-Certified-Data-Engineer-Professional熱門題庫
- 已驗證的Databricks-Certified-Data-Engineer-Professional資訊 |高通過率的考試材料|正確的Databricks-Certified-Data-Engineer-Professional證照考試 🔨 進入▶ www.newdumpspdf.com ◀搜尋☀ Databricks-Certified-Data-Engineer-Professional ️☀️免費下載Databricks-Certified-Data-Engineer-Professional題庫更新
- 準備充分的Databricks-Certified-Data-Engineer-Professional資訊和資格考試中的領先提供者和更新的Databricks Databricks Certified Data Engineer Professional Exam 🕋 ⇛ www.newdumpspdf.com ⇚網站搜索✔ Databricks-Certified-Data-Engineer-Professional ️✔️並免費下載Databricks-Certified-Data-Engineer-Professional測試題庫
- Databricks-Certified-Data-Engineer-Professional考試證照 🌞 Databricks-Certified-Data-Engineer-Professional PDF 🧑 最新Databricks-Certified-Data-Engineer-Professional題庫 🎣 ➡ tw.fast2test.com ️⬅️是獲取⮆ Databricks-Certified-Data-Engineer-Professional ⮄免費下載的最佳網站Databricks-Certified-Data-Engineer-Professional題庫更新
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Testpdf最新的Databricks-Certified-Data-Engineer-Professional PDF版考試題庫和Databricks-Certified-Data-Engineer-Professional考試問題和答案免費分享:https://drive.google.com/open?id=11xbKYKfOmn5O-t4cK5iNpmvHDU2vROcj