P.S. Free & New DP-750 dumps are available on Google Drive shared by PracticeTorrent: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw
Our Implementing Data Engineering Solutions Using Azure Databricks study questions have a high quality, that mainly reflected in the passing rate. More than 99% students who use our DP-750 exam material passed the exam and successfully obtained the relating certificate. This undoubtedly means that if you purchased DP-750 exam guide and followed the information we provided you, you will have a 99% chance of successfully passing the exam. So our DP-750 study materials are a good choice for you. In order to gain your trust, we will provide you with a full refund commitment. If you failed to pass the exam after you purchase DP-750 Exam Material, whatever the reason, you just need to submit your transcript to us and we will give you a full refund. We dare to make assurances because we have absolute confidence in the quality of Implementing Data Engineering Solutions Using Azure Databricks study questions. We also hope you can believe that DP-750 exam guide is definitely the most powerful weapon to help you pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
As the saying goes, to sensible men, every day is a day of reckoning. Time is very important to people. People often complain that they are wasting their time on study and work. They do not have time to look at the outside world. Now, DP-750 exam guide gives you this opportunity. DP-750 test prep helps you save time by improving your learning efficiency. With our study materials, you can efficiently use all your fragmented time to learn. You can use your mobile phone to practice whether on the bus or at the time you are queuing up for a meal or waiting for someone. DP-750 learning question helps you to enjoy the joy of life while climbing the top of your career. What are you hesitating? Come and buy it.
NEW QUESTION # 79
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.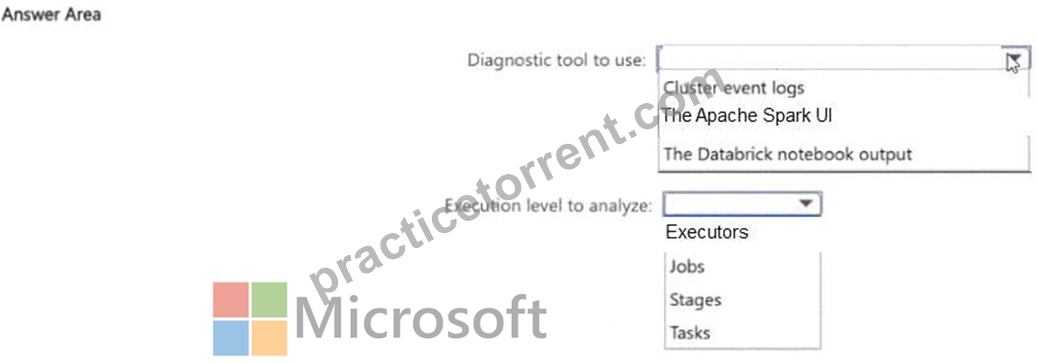
Answer:
Explanation: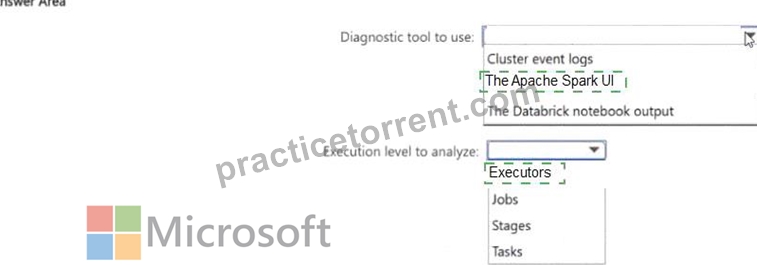
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 80
You need to curate Unity Catalog objects that reference the ERP data. The solution must meet the governance requirements.
What should you do?
Answer: A
Explanation:
A foreign catalog mirrors the external ERP database and provides read-only access through Lakehouse Federation. Consequently, it cannot host managed volumes or locally created Delta tables, and its foreign tables cannot be altered to add analytics columns. The appropriate design is to create governed views in the managed analytics catalog and have those views reference the foreign tables through fully qualified catalog.
schema.table names. This preserves the ERP data in its source system, avoids duplication, and exposes standardized curated objects through Unity Catalog. Permissions can then be granted on the managed views while access to underlying foreign objects remains controlled. Unity Catalog uses a three-level namespace, and foreign catalogs are specifically intended to make external database data queryable without copying it into Databricks-managed storage. Microsoft Learn
NEW QUESTION # 81
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: C
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 82
You have an Azure Databricks workspace that contains the objects shown in the following table.
Name | Type
Catalog1 | Catalog
Schema1 | Schema
Sales1 | Table
Notebook1 | Notebook
Space1 | AI/BI Genie space
Users often use the following words to refer to a sale: transaction, event, order, and invoice.
You need to create a knowledge store. The solution must ensure that when the users use any of the words in Space1, Genie queries the Sales1 table. Any other Genie spaces must remain unaffected.
To which object should you add the instructions?
Answer: A
Explanation:
The instructions must be added to Space1 because a Genie knowledge store is scoped to the individual Genie space, now called a Genie Agent. Adding synonyms and business-language instructions there teaches Space1 that "transaction," "event," "order," and "invoice" refer to sales information in Sales1. The configuration affects only that Genie space, satisfying the requirement that other spaces remain unchanged. Adding instructions to Sales1 or Schema1 would modify shared Unity Catalog metadata and could affect other consumers of those objects. Notebook1 is unrelated to the semantic instructions used by Genie when converting natural-language questions into SQL. Genie knowledge stores contain space-specific definitions, synonyms, join relationships, SQL expressions, and prompt-matching guidance without changing the underlying Unity Catalog objects. Microsoft Learn
NEW QUESTION # 83
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: D
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 84
......
We all know that Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps are an important section of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam that is purely based on your skills, expertise, and knowledge. So, we must find quality DP-750 Questions drafted by industry experts who have complete knowledge regarding the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam and can share the same with those who want to clear the DP-750 exam. The best approach to finding Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps is to check the PracticeTorrent that is offering the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice questions.
DP-750 Reliable Exam Simulations: https://www.practicetorrent.com/DP-750-practice-exam-torrent.html
What's more, part of that PracticeTorrent DP-750 dumps now are free: https://drive.google.com/open?id=1W-b8QyjInySOX5AHEBL_hE4YzfM6j2Hw